Splash Engine - the fastest local Qwen3.8 on Apple Silicon
What is Splash Engine?
Splash is an open-source inference engine from Inco AI for running language models locally on Apple silicon. It is optimized specifically for Qwen3.6-35B-A3B and Qwen3.8-27B. The engine provides GPU kernels and a memory plan tailored to each supported model. Each model ships with a dedicated DFlash 2 draft model for speculative decoding, which improves generation speed.
In Inco's tests on a 48 GB M5 Pro, Splash delivered roughly twice the decode speed of the next-fastest engine they measured on Qwen3.8-27B: 74 tokens per second on short prompts and 54 at 32K context. With four concurrent requests on short prompts, its combined throughput reached 170 tokens per second—3.9× the next-fastest engine in their comparison. Read more about Splash in Inco's blog post.
Use it in LM Studio Bionic
Download and install LM Studio Bionic 1.1.5 or newer, then open the app. Splash requires an M3-or-newer Mac running macOS 26.4 or later with at least 36 GB of unified memory; Inco recommends 48 GB or more.
Navigate to Settings > Runtime. Under Experimental backends, click Download next to Splash (Metal) to install the engine.
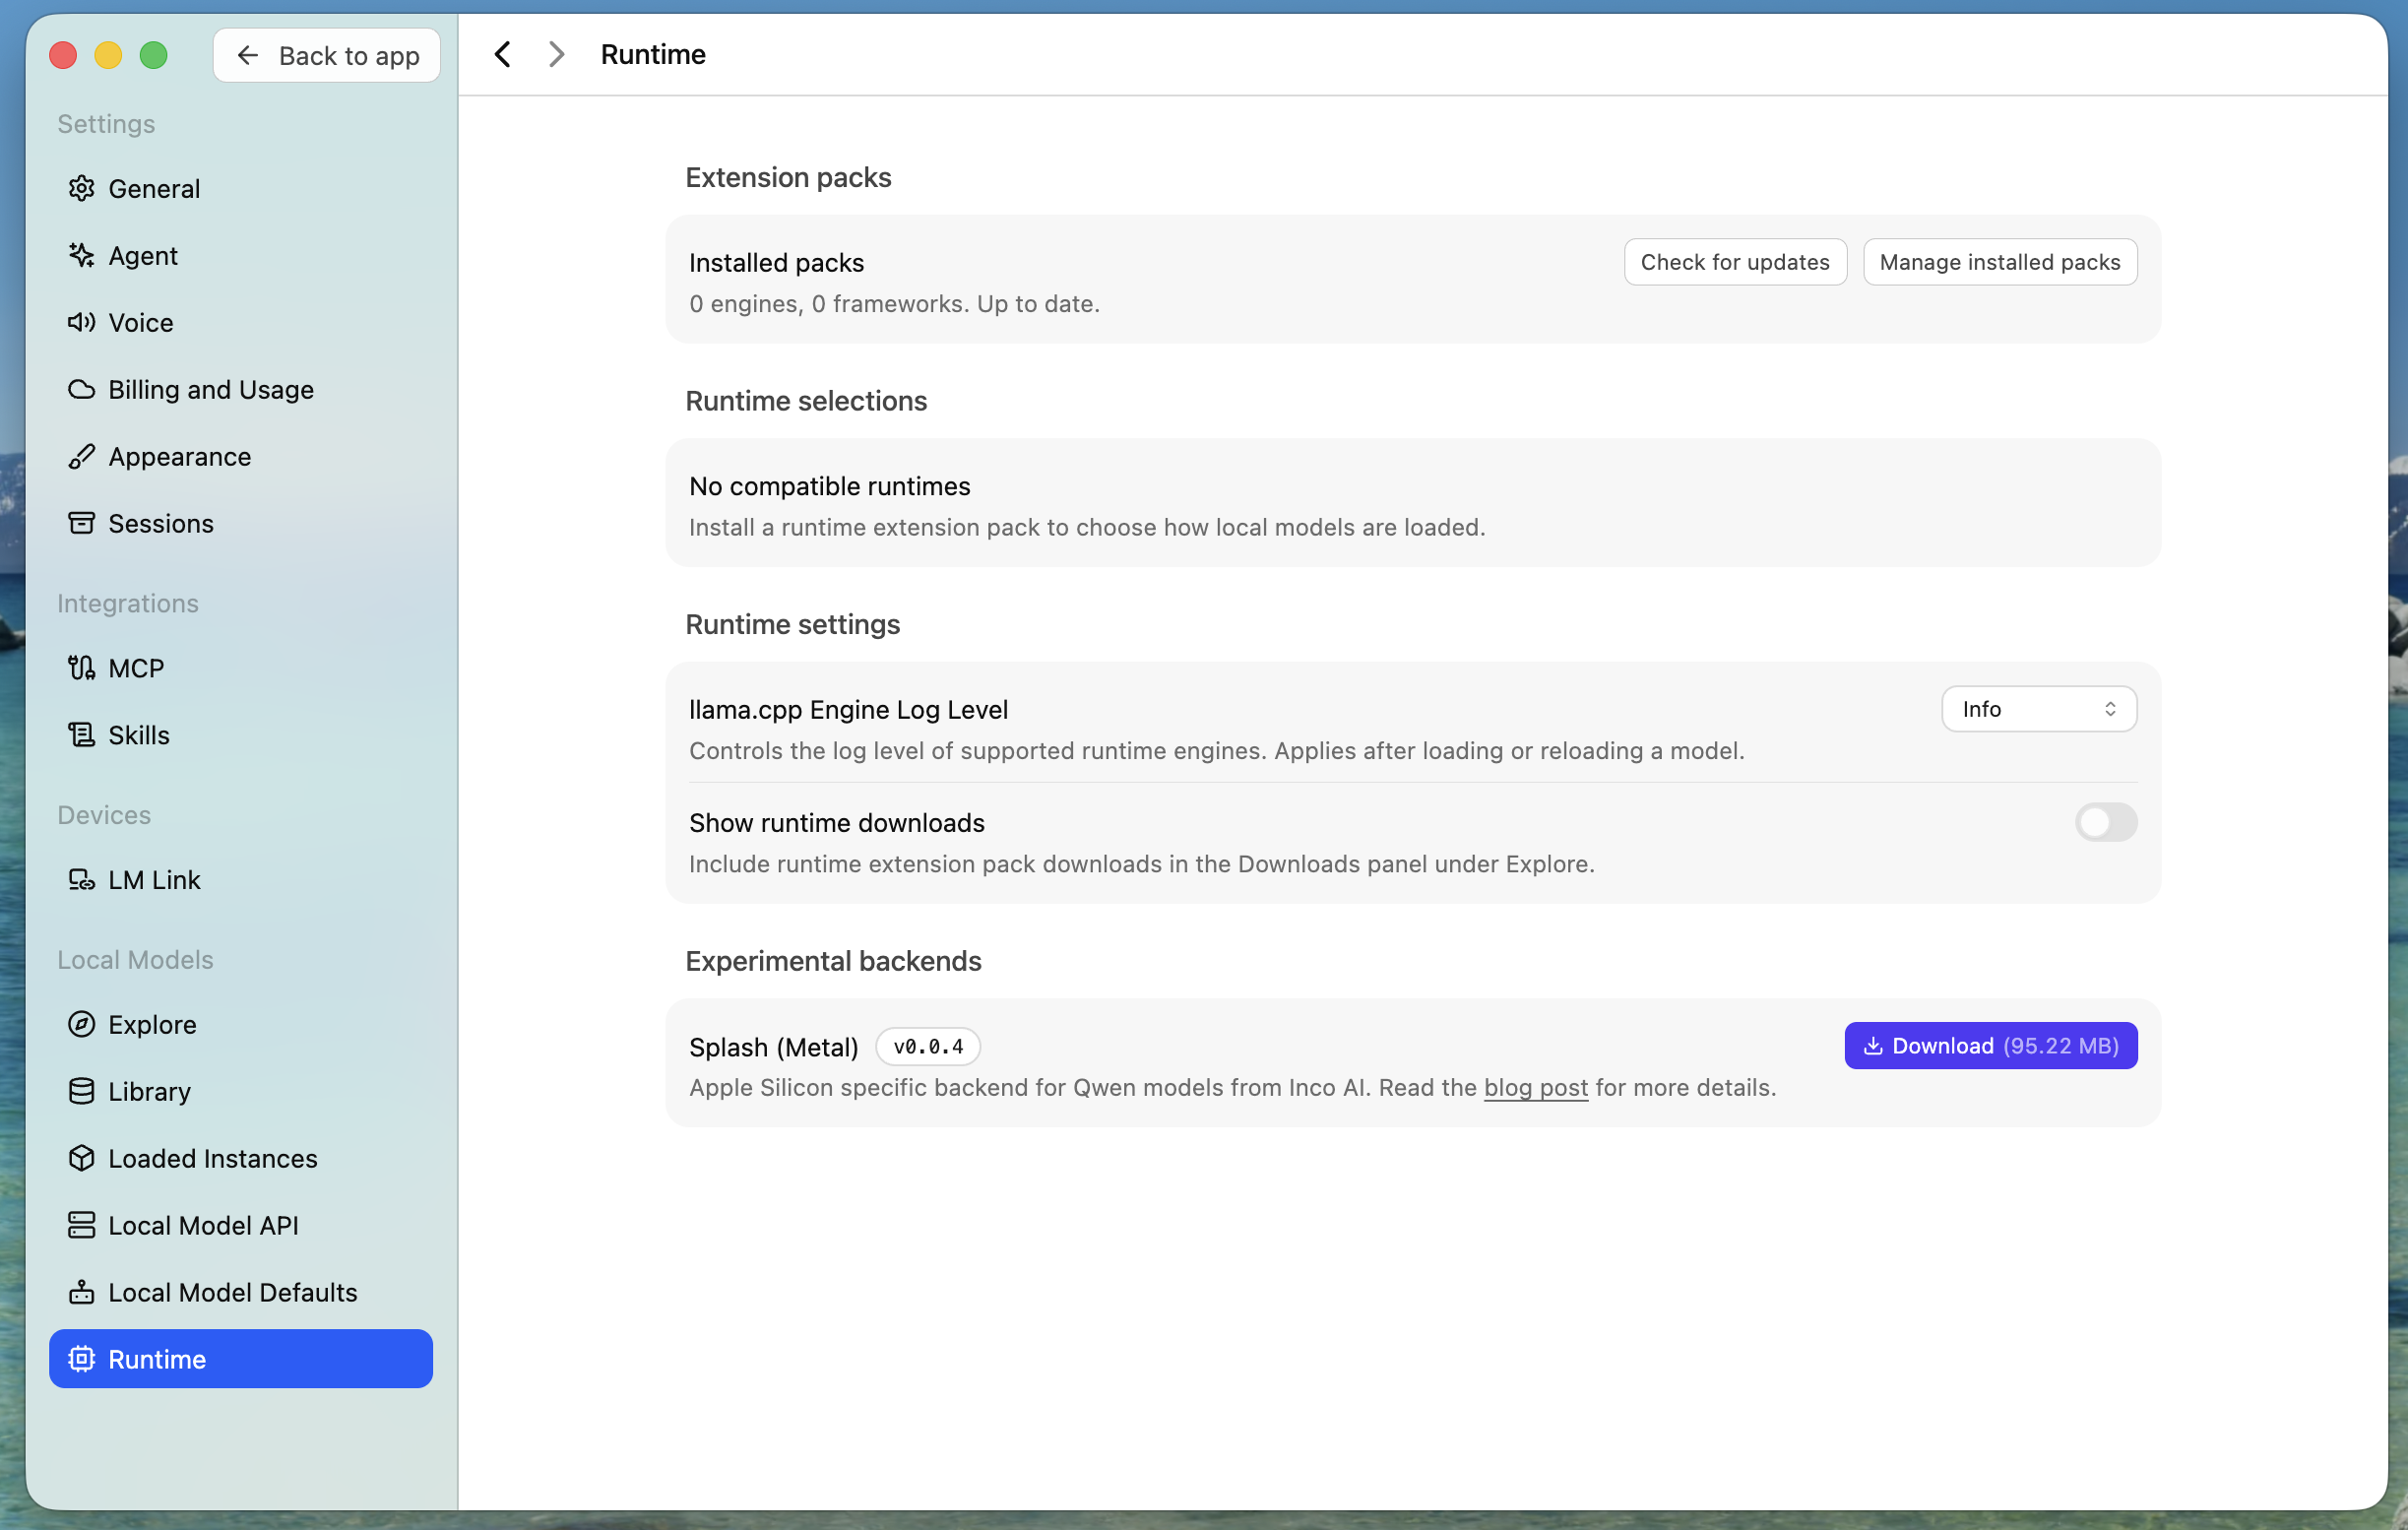
Download the Splash engine from Settings > Runtime.
Then go to Settings > Explore, paste one of the following Hugging Face links into the search bar, select the model, and click Download:
Once the download finishes, start a new session and select the model from the local model picker.