Tags
Last updated
Updated on July 14byREADME
Sources
The underlying model files this model uses
Tags
Last updated
Updated on July 14byREADME
Sources
The underlying model files this model uses
Parable models are trained on real agent work: multi-step tool use, planning, and thinking traces captured from Claude Fable 5 and GPT-5.5 sessions, not synthetic Q&A. Every release is eval-gated against its base before it ships.
This page hosts the Qwen3 line of the family. It adds structured <think> reasoning and agent-style task execution to Qwen3, tuned for local coding and terminal work.
Highlights:
<think> reasoning from actual Claude Fable 5 and GPT-5.5 sessions, not synthetic Q&A.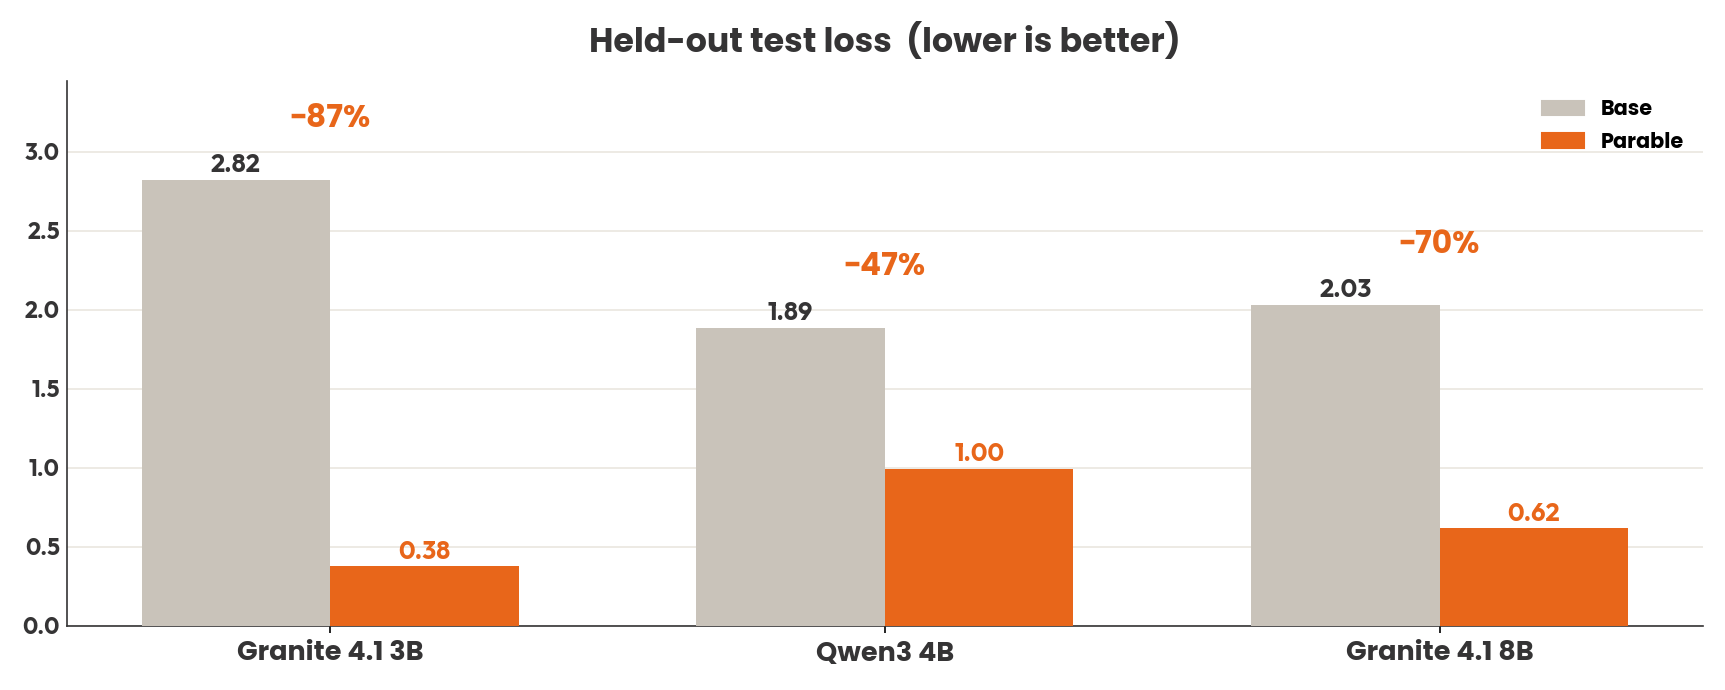
Evaluation (held-out test split, identical eval code for base and fine-tune):
Token accuracy 4b: 0.683 → 0.782. Strictly graded qualitative results are published on the Hugging Face cards.
Usage notes
<think>...</think> block before the final answer.Family
parable/granite4.1-fablelms get)ollama run parable/qwen3-fable, plus the sibling line and the family flagship parable/fableBase model: Qwen3 (Apache-2.0). Training data: Glint-Research/Fable-5-traces (AGPL-3.0), gpt5.5-terminal (MIT). Third-party assistant traces; providers' terms may apply to downstream training.
Based on
Parable models are trained on real agent work: multi-step tool use, planning, and thinking traces captured from Claude Fable 5 and GPT-5.5 sessions, not synthetic Q&A. Every release is eval-gated against its base before it ships.
This page hosts the Qwen3 line of the family. It adds structured <think> reasoning and agent-style task execution to Qwen3, tuned for local coding and terminal work.
Highlights:
<think> reasoning from actual Claude Fable 5 and GPT-5.5 sessions, not synthetic Q&A.Evaluation (held-out test split, identical eval code for base and fine-tune):
Token accuracy 4b: 0.683 → 0.782. Strictly graded qualitative results are published on the Hugging Face cards.
Usage notes
<think>...</think> block before the final answer.Family
parable/granite4.1-fablelms get)ollama run parable/qwen3-fable, plus the sibling line and the family flagship parable/fableBase model: Qwen3 (Apache-2.0). Training data: Glint-Research/Fable-5-traces (AGPL-3.0), gpt5.5-terminal (MIT). Third-party assistant traces; providers' terms may apply to downstream training.
Based on
