Nemotron 3.5 Super VL
Nemotron 3.5 Super VL
NVIDIA's 120B vision-language MoE model (12B active) for multimodal reasoning and tool use, with up to 1M tokens of context.
Memory Requirements
To run the smallest Nemotron 3.5 Super VL, you need at least 70 GB of RAM.
Capabilities
Nemotron 3.5 Super VL models support tool use, vision input, and reasoning. They are available in gguf.
About Nemotron 3.5 Super VL
NVIDIA Nemotron 3.5 Super VL is a vision-language reasoning model for specialized agents, combining text and visual understanding with instruction following, tool use, and structured output. Its 120B-parameter hybrid Mixture-of-Experts architecture activates 12B parameters per token.
Capabilities
- Multimodal reasoning: document question answering, chart interpretation, GUI understanding, and visual Q&A. NVIDIA's upstream model also supports video through sampled frames.
- Long context: supports up to 1M tokens shared across prompts, visual inputs, conversation history, tool results, and generated responses. Usable context depends on memory and runtime configuration.
- Configurable thinking: supports thinking and non-thinking modes, an optional medium reasoning effort, and truncation of prior thinking history.
- Hybrid architecture: interleaves Mamba-2, MoE, and Attention layers with a C-RADIO v4-H vision encoder. A built-in Multi-Token Prediction head enables speculative decoding in supported runtimes.
NVIDIA-reported results
NVIDIA reports the following agent-harness results in its release announcement:
| Model | Hermes Bench | LangChain Evals |
|---|---|---|
| Nemotron 3 Ultra | 56.33% | 84.3% |
| Nemotron 3.5 Super VL | 63.44% | 87.05% |
The official model card also compares full-precision and NVFP4 checkpoints:
| Benchmark | BF16 | NVFP4 |
|---|---|---|
| GPQA-Diamond | 89.52 | 89.90 |
| MMLongBench-Doc | 62.82 | 62.82 |
| OCRBench v2, English | 68.12 | 68.34 |
| CharXiv reasoning | 80.82 | 79.88 |
These are NVIDIA-reported upstream results, not measurements of every downloadable GGUF quantization. NVIDIA holds harnesses and other non-model settings fixed for the BF16/NVFP4 comparison; see the model card and linked evaluation recipes for benchmark-specific methodology.
DGX Spark accuracy and task-completion time
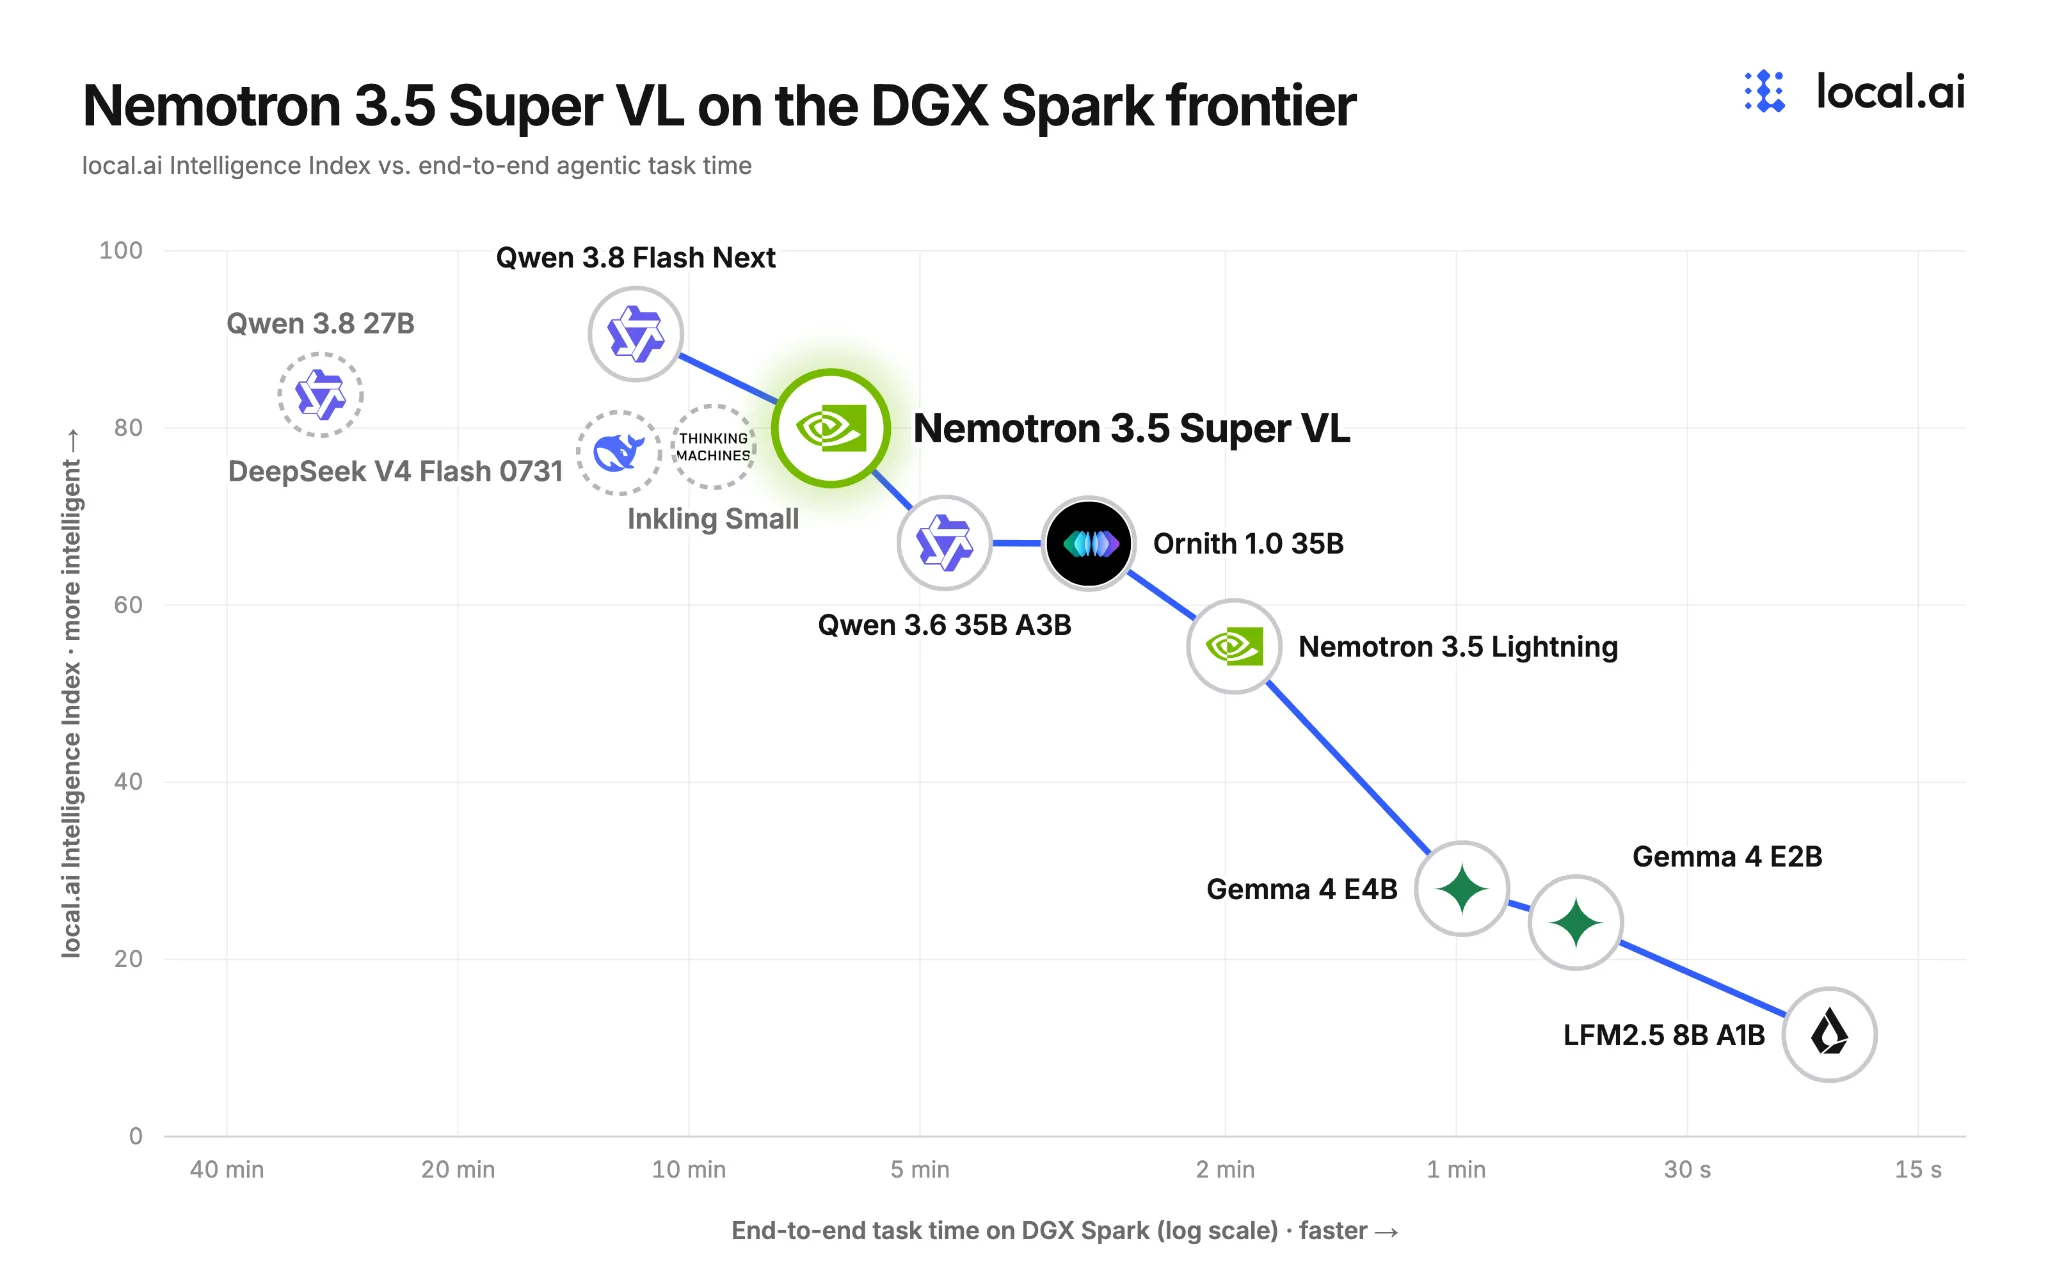
Source: NVIDIA’s release announcement, citing an EXO Labs evaluation on a single 128 GB DGX Spark. Results reflect the evaluated hardware and serving configurations, not measurements of every downloadable GGUF build.
Local deployment
The linked artifact provides GGUF downloads for local inference. The current Q4_K_M weights are approximately 70 GB; additional memory is needed for visual inputs, context, and runtime buffers. Native model capabilities and acceleration features depend on runtime support and configuration.
License
Use is governed by the OpenMDW License Agreement, version 1.1.