DeepSeek V4.1 Flash 1017
DeepSeek V4.1 Flash 1017
DeepSeek V4.1 Flash 1017 is a multimodal model for reasoning, coding, and long-context agents, with native image input, a 1M-token context window, and improved performance over the original V4.1 Flash.
About DeepSeek V4.1 Flash 1017
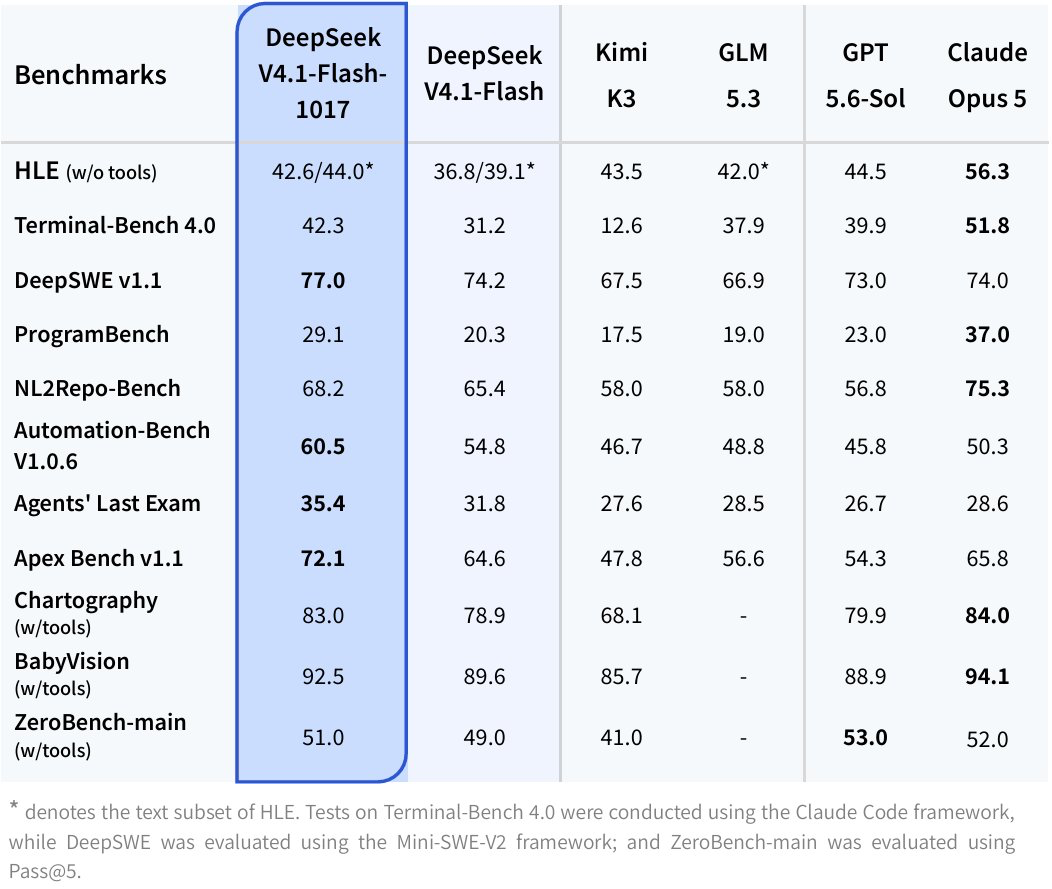
Results reported by DeepSeek. Evaluations use different task-specific settings, including with-tool and without-tool evaluations. See the official model card for methodology and harness details.
DeepSeek V4.1 Flash 1017 is an update to DeepSeek V4.1 Flash for reasoning, coding, visual understanding, and long-running agents. DeepSeek reports stronger benchmark performance alongside shorter outputs and faster task execution. The model natively accepts text and images and supports a context window of up to one million tokens.
Highlights
- Native text and image input with text output
- Up to a 1M-token context window
- Improved reasoning, coding, agentic, and visual benchmark results over the original V4.1 Flash
- A 552B-parameter backbone, with 8B active parameters during prefill and 16B during decoding
- MIT-licensed open weights
- Cloud inference without managing the model locally
What's new in 1017?
The 1017 update focuses on completing demanding tasks more effectively and efficiently. In DeepSeek's evaluations, Terminal-Bench 4.0 improves from 31.2 to 42.3, DeepSWE v1.1 from 74.2 to 77.0, and ProgramBench from 20.3 to 29.1 compared with the original V4.1 Flash. Visual evaluations also improve, including Chartography with tools from 78.9 to 83.0 and BabyVision with tools from 89.6 to 92.5.
DeepSeek reports using the Claude Code harness for Terminal-Bench 4.0 and Mini-SWE-V2 for DeepSWE v1.1. Results depend on the harness, reasoning settings, tools, and evaluation methodology; they are not guarantees for individual workloads.
Built for long-context agents
V4.1 Flash uses an asymmetric Causal Encoder–Decoder architecture that activates fewer parameters while processing input than while generating output. Its 552B-parameter backbone activates 8B parameters per token during prefill and 16B during decoding. Native vision support lets the model process images alongside text.
Compressed Sparse Attention 2 reduces long-context inference overhead. Together with the 1M-token context window, this makes the model a fit for repository-scale coding, visual document understanding, and input-heavy agent workflows.
Use DeepSeek V4.1 Flash 1017 in Bionic
Choose DeepSeek V4.1 Flash 1017 from the Cloud model picker in Bionic to use hosted inference without downloading the weights or provisioning local hardware.
License and sources
DeepSeek V4.1 Flash 1017 is released under the MIT License.
Official model card · DeepSeek release notes · Baseten model library