 LM Link is a new feature in LM Studio that provides a way to access local models across devices, wherever you are. Links are custom made, end-to-end encrypted networks intended for loading and serving LLMs across devices you own, made possible in partnership with Tailscale.
What can I do with LM Link? [#what-can-i-do-with-lm-link]
LM Link unlocks the full potential of your hardware by sharing compute across connected devices.
For example, you might have a powerful desktop in your home office, and a lightweight laptop you carry on the go. With LM Link, you can run large open-weight models on a powerful machine, and use them seamlessly from your laptop or your iPhone as if they were local.
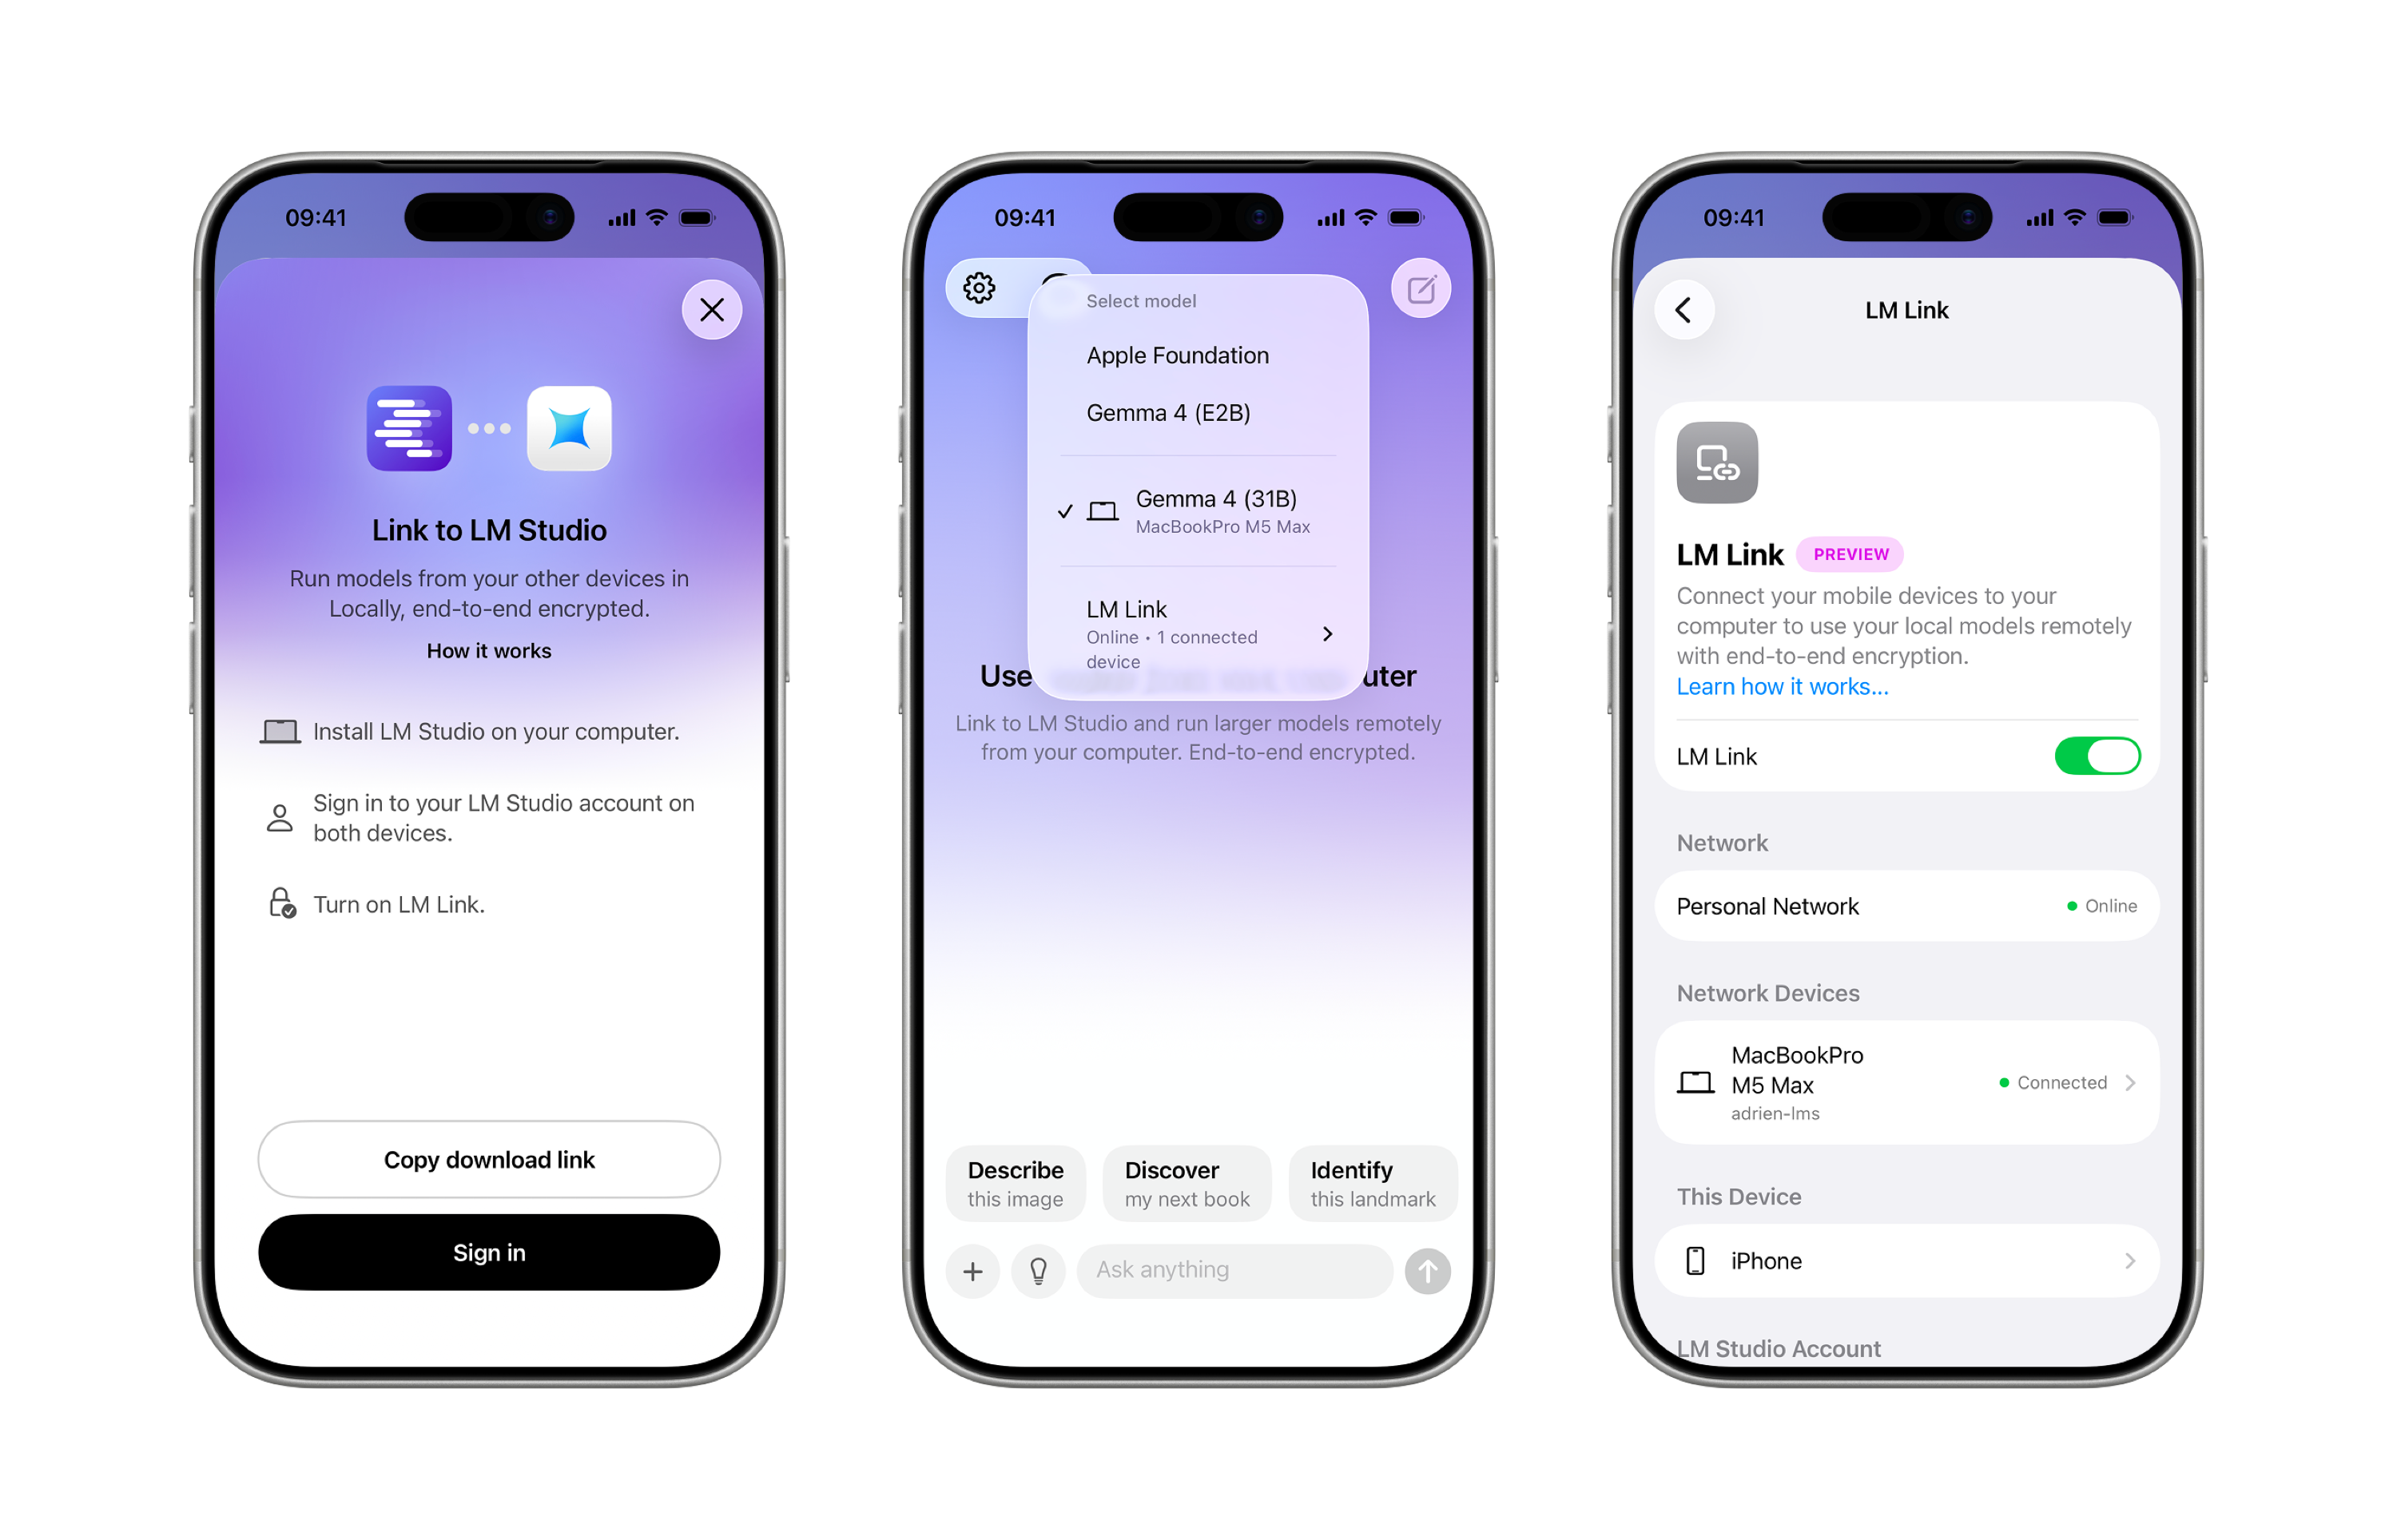
To use LM Link on iPhone, [download Locally](https://apps.apple.com/us/app/locally-ai-local-ai-chat/id6741426692), link it to LM Studio, and those models are now in your pocket wherever you are. All communication and data transfer between devices is always end-to-end encrypted, thanks to Tailscale.
Use Cases [#use-cases]
LM Link use cases span individuals as well as teams.
You can manage a private link to keep your prized gaming GPU busy even when you're on the go. Moreover, LM Link allows you to set up LLM serving in a server and start using it with just few clicks.
Use LM Link with [#use-lm-link-with]
* **CLI** — manage LM Link from the terminal with [`lms link`](/docs/cli/link/link-enable)
* **REST API** — use remote models via the REST API with [LM Link](/docs/developer/core/lmlink)
* **Integrations** — use remote models with coding tools like Claude Code and Codex via [LM Link](/docs/integrations/lmlink)
[Locally](https://apps.apple.com/us/app/locally-ai-local-ai-chat/id6741426692) is LM Studio's mobile app, available for iPhone and iPad. Enable LM Link in Locally to use your largest local models running in LM Studio directly from your phone. All data and communication between your devices stay end-to-end encrypted.
 Getting Started [#getting-started]
1. If you don't yet have LM Studio, [download it here](https://lmstudio.ai/download).
2. Sign in to your LM Studio account, and make sure LM Link is enabled in LM Studio.
3. [Download the Locally app](https://apps.apple.com/us/app/locally-ai-local-ai-chat/id6741426692) on your iPhone or iPad.
4. Sign in to Locally with the same account you used for LM Studio, and enable LM Link in Locally.
Your Locally and LM Studio devices will discover each other over the link, and you can begin using your largest models running in LM Studio, directly from your phone.
FAQ [#faq]
Does the connection stay active when I close the Locally app?
LM Link is an alive end-to-end encrypted connection between your devices, while this ensures it is secure there are limitations on how long this connection can last once the app is backgrounded. We are actively working on both improving the latency for faster reconnect and ways of keeping the connection alive.Does LM Link require internet connection?
Yes. LM Link requires an internet connection to establish the connection between your devices.I see Locally is also supported on Macs. Can I use LM Link between my iPhone and Mac versions of Locally?
Not quite — LM Link is designed to connect LM Studio on your computer to Locally on your mobile device, not between two Locally apps.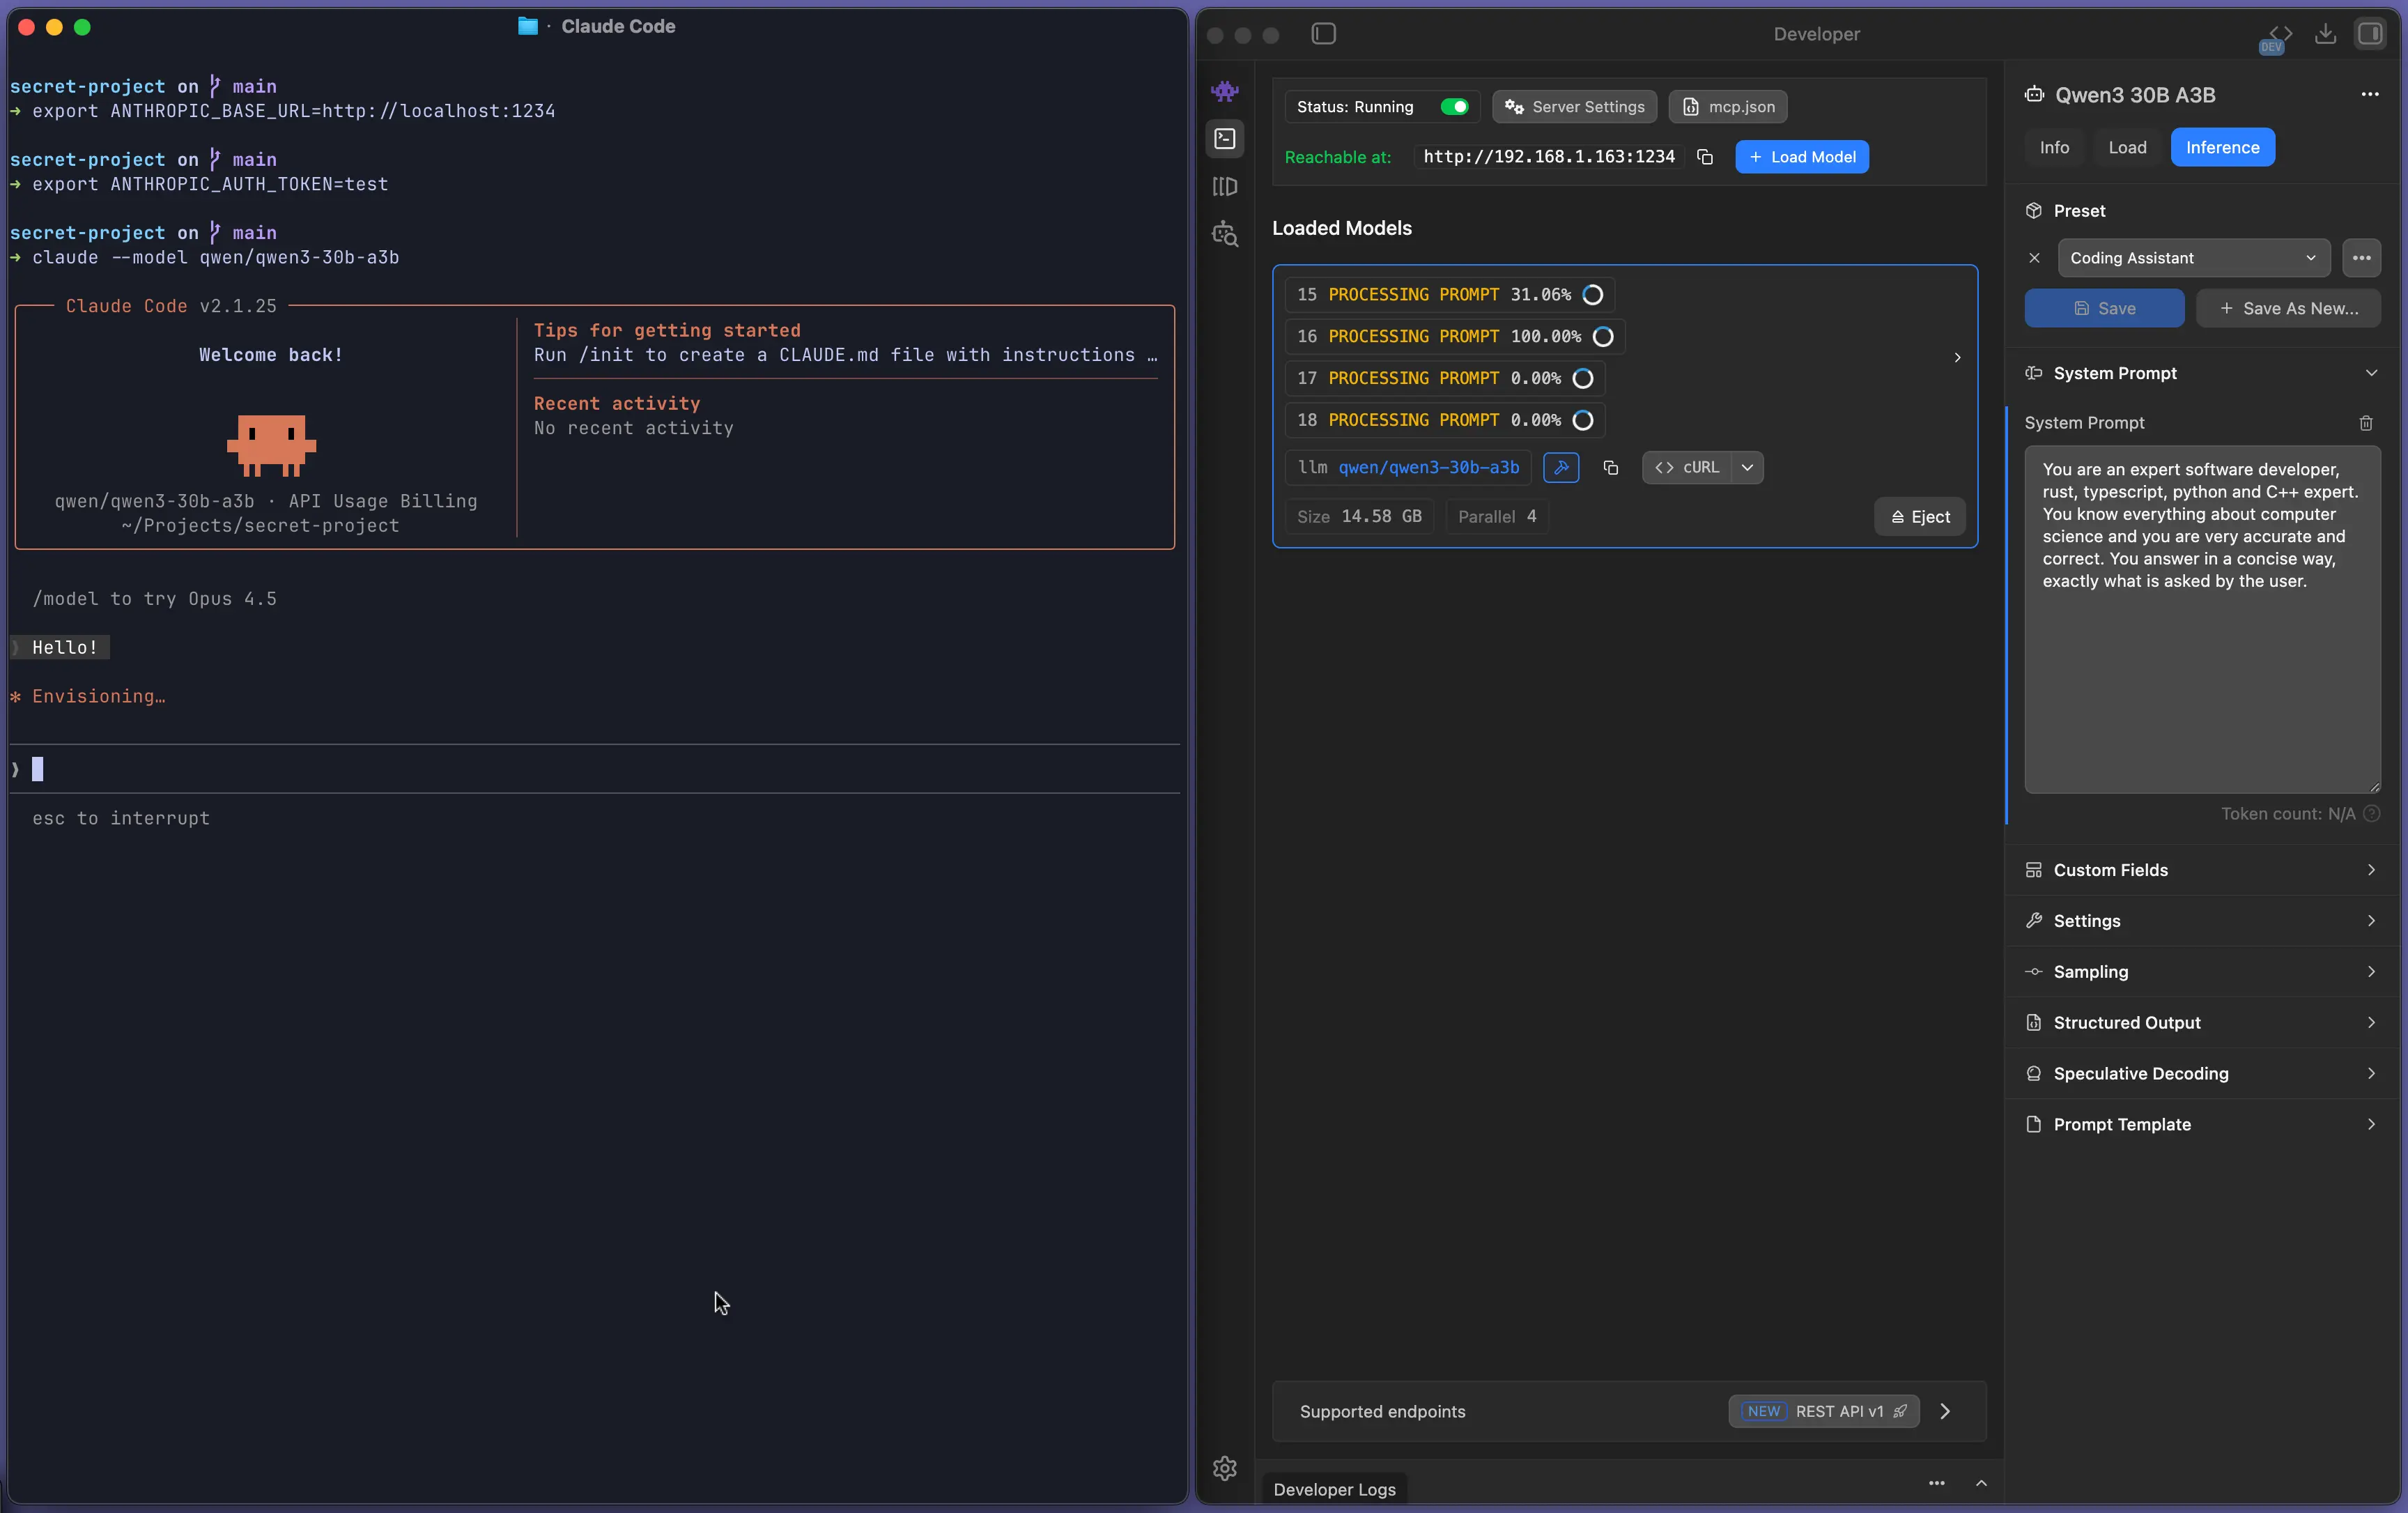
Start LM Studio's local server
Make sure LM Studio is running as a server (default port `1234`). You can start it from the app, or from the terminal with `lms`: ```bash lms server start --port 1234 ```Configure Claude Code
Set these environment variables so the `claude` CLI points to your local LM Studio: ```bash export ANTHROPIC_BASE_URL=http://localhost:1234 export ANTHROPIC_AUTH_TOKEN=lmstudio export CLAUDE_CODE_ATTRIBUTION_HEADER=0 ``` Notes: * If Require Authentication is enabled, set `ANTHROPIC_AUTH_TOKEN` to your LM Studio API token. To learn more, see: [Authentication](/docs/developer/core/authentication).Run Claude Code against a local model
```bash claude --model openai/gpt-oss-20b ```If Require Authentication is enabled, use your LM Studio API token
If you turned on "Require Authentication" in LM Studio, create an API token and set: ```bash export LM_API_TOKEN=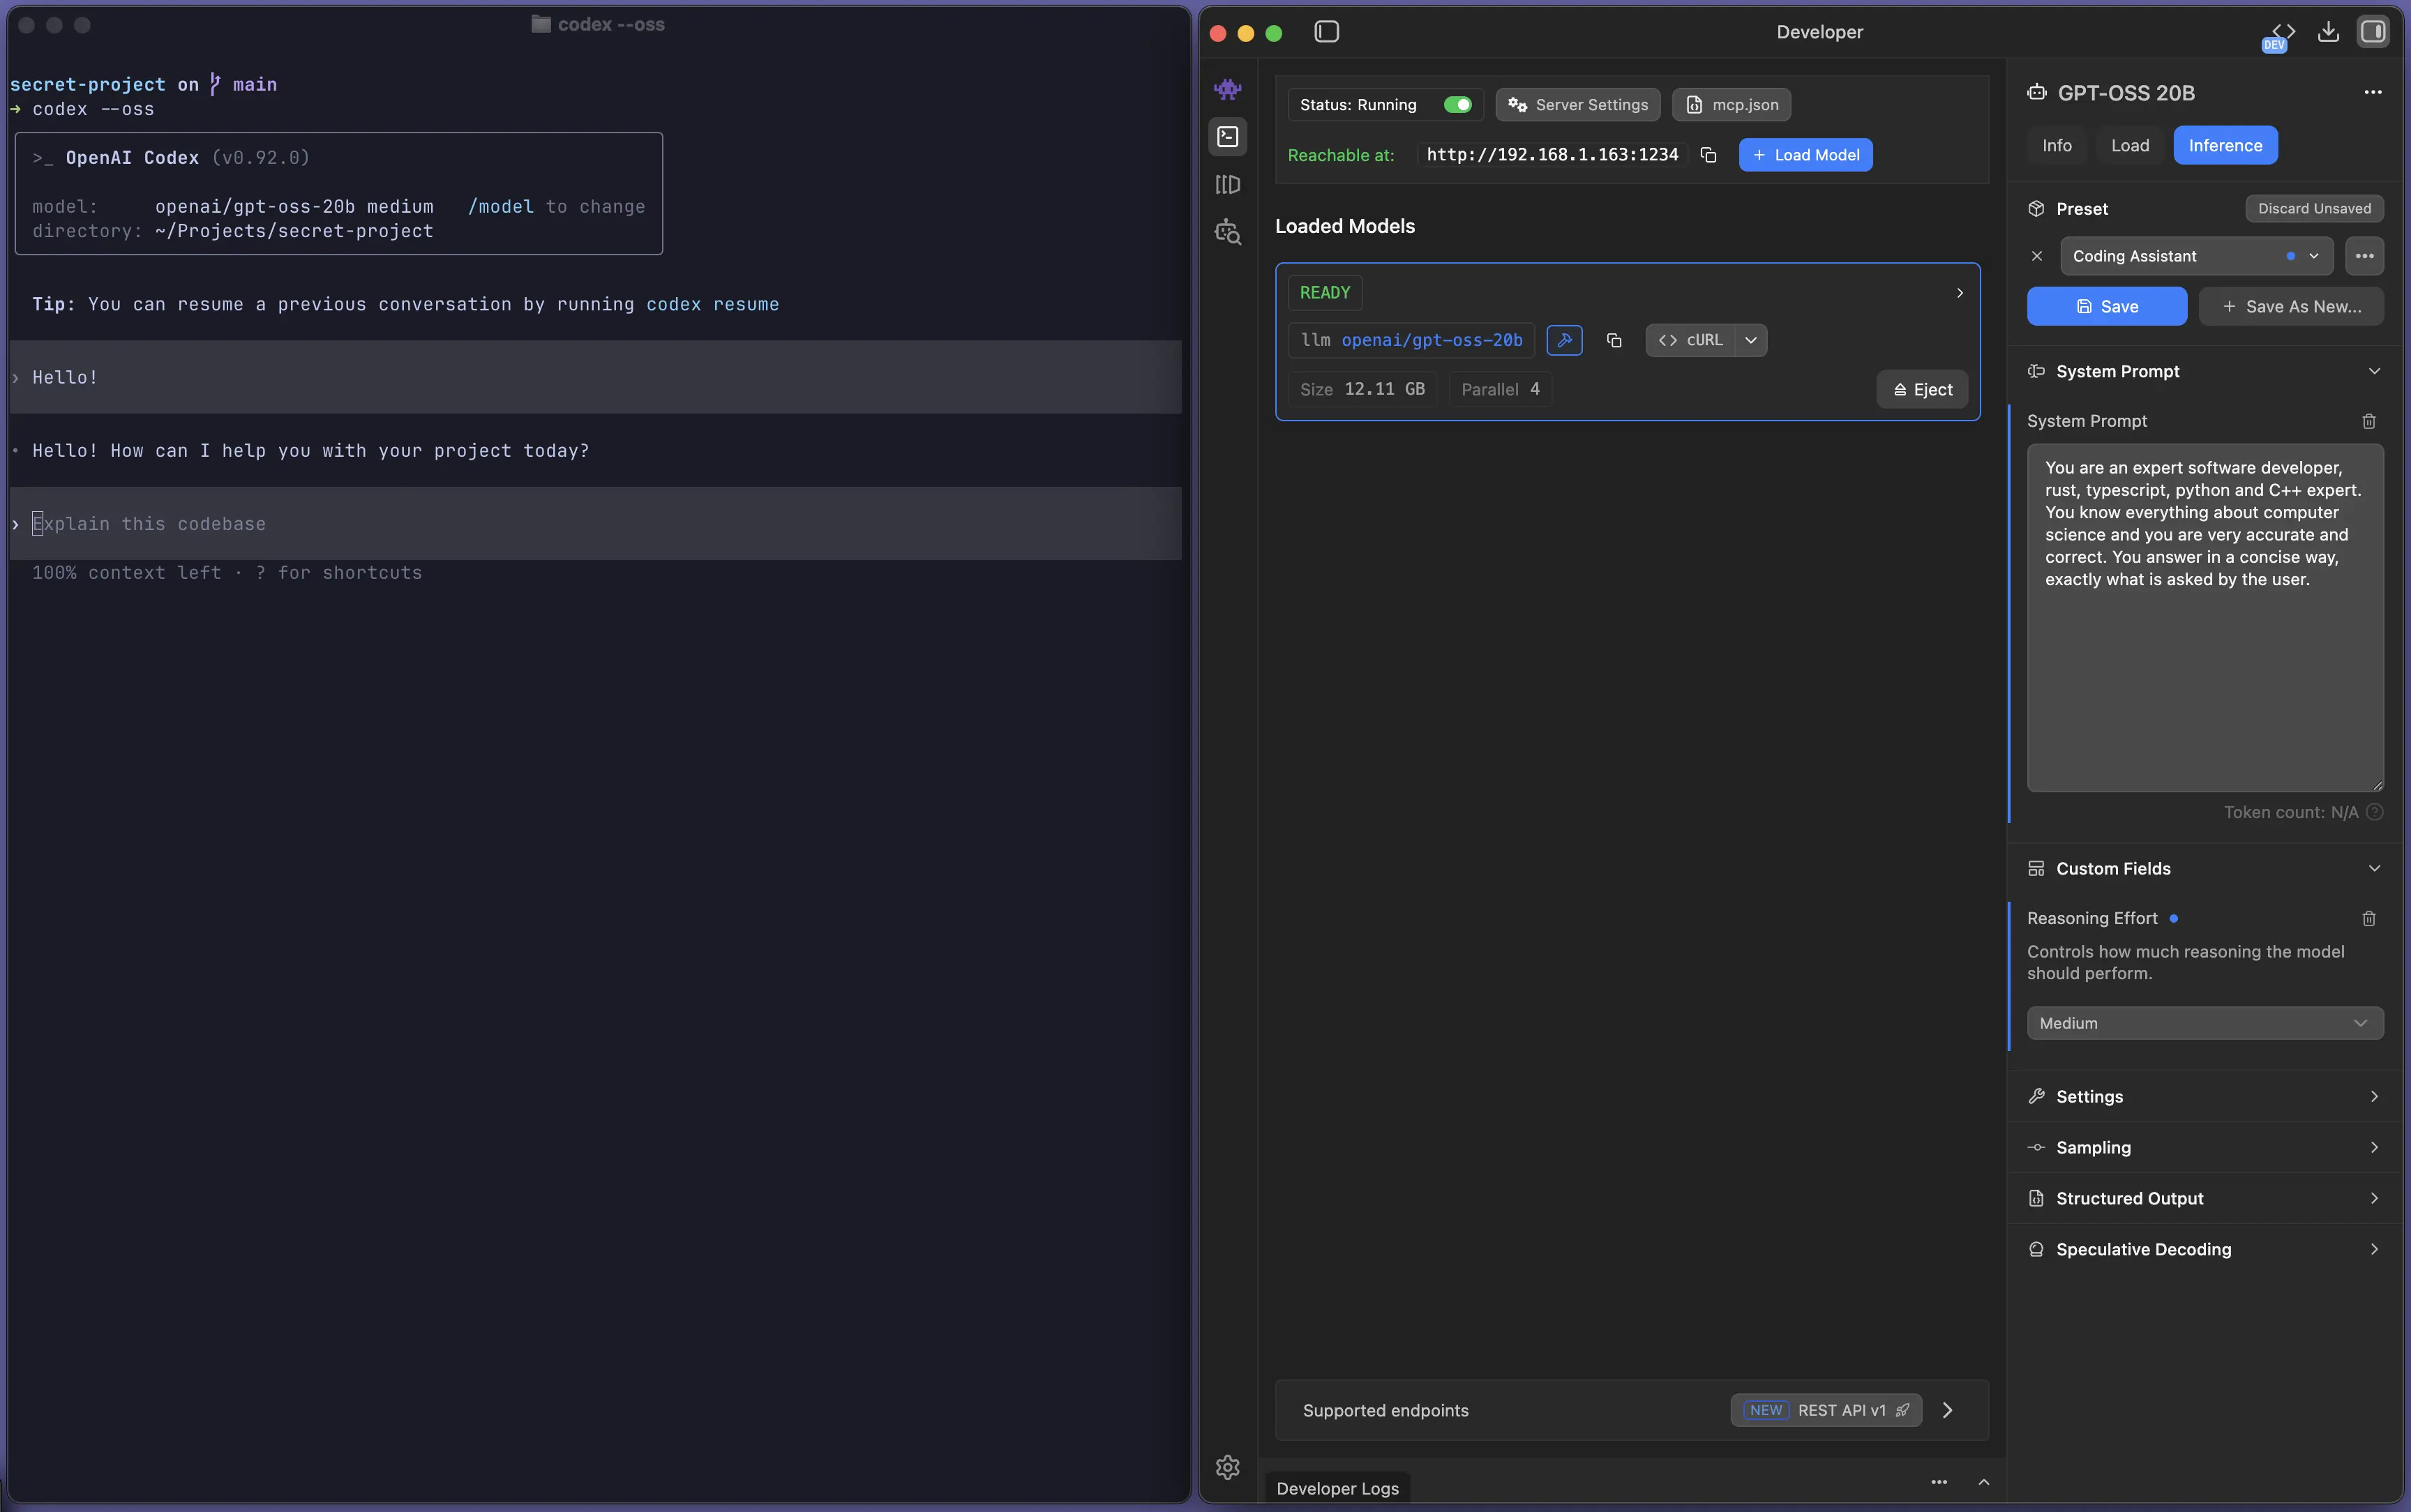
Start LM Studio's local server
Make sure LM Studio is running as a server (default port `1234`). You can start it from the app, or from the terminal with `lms`: ```bash lms server start --port 1234 ```Run Codex against a local model
Run Codex as you normally would, but with the `--oss` flag to point it to LM Studio. Example: ```bash codex --oss ``` By default, Codex will download and use [openai/gpt-oss-20b](https://lmstudio.ai/models/openai/gpt-oss-20b).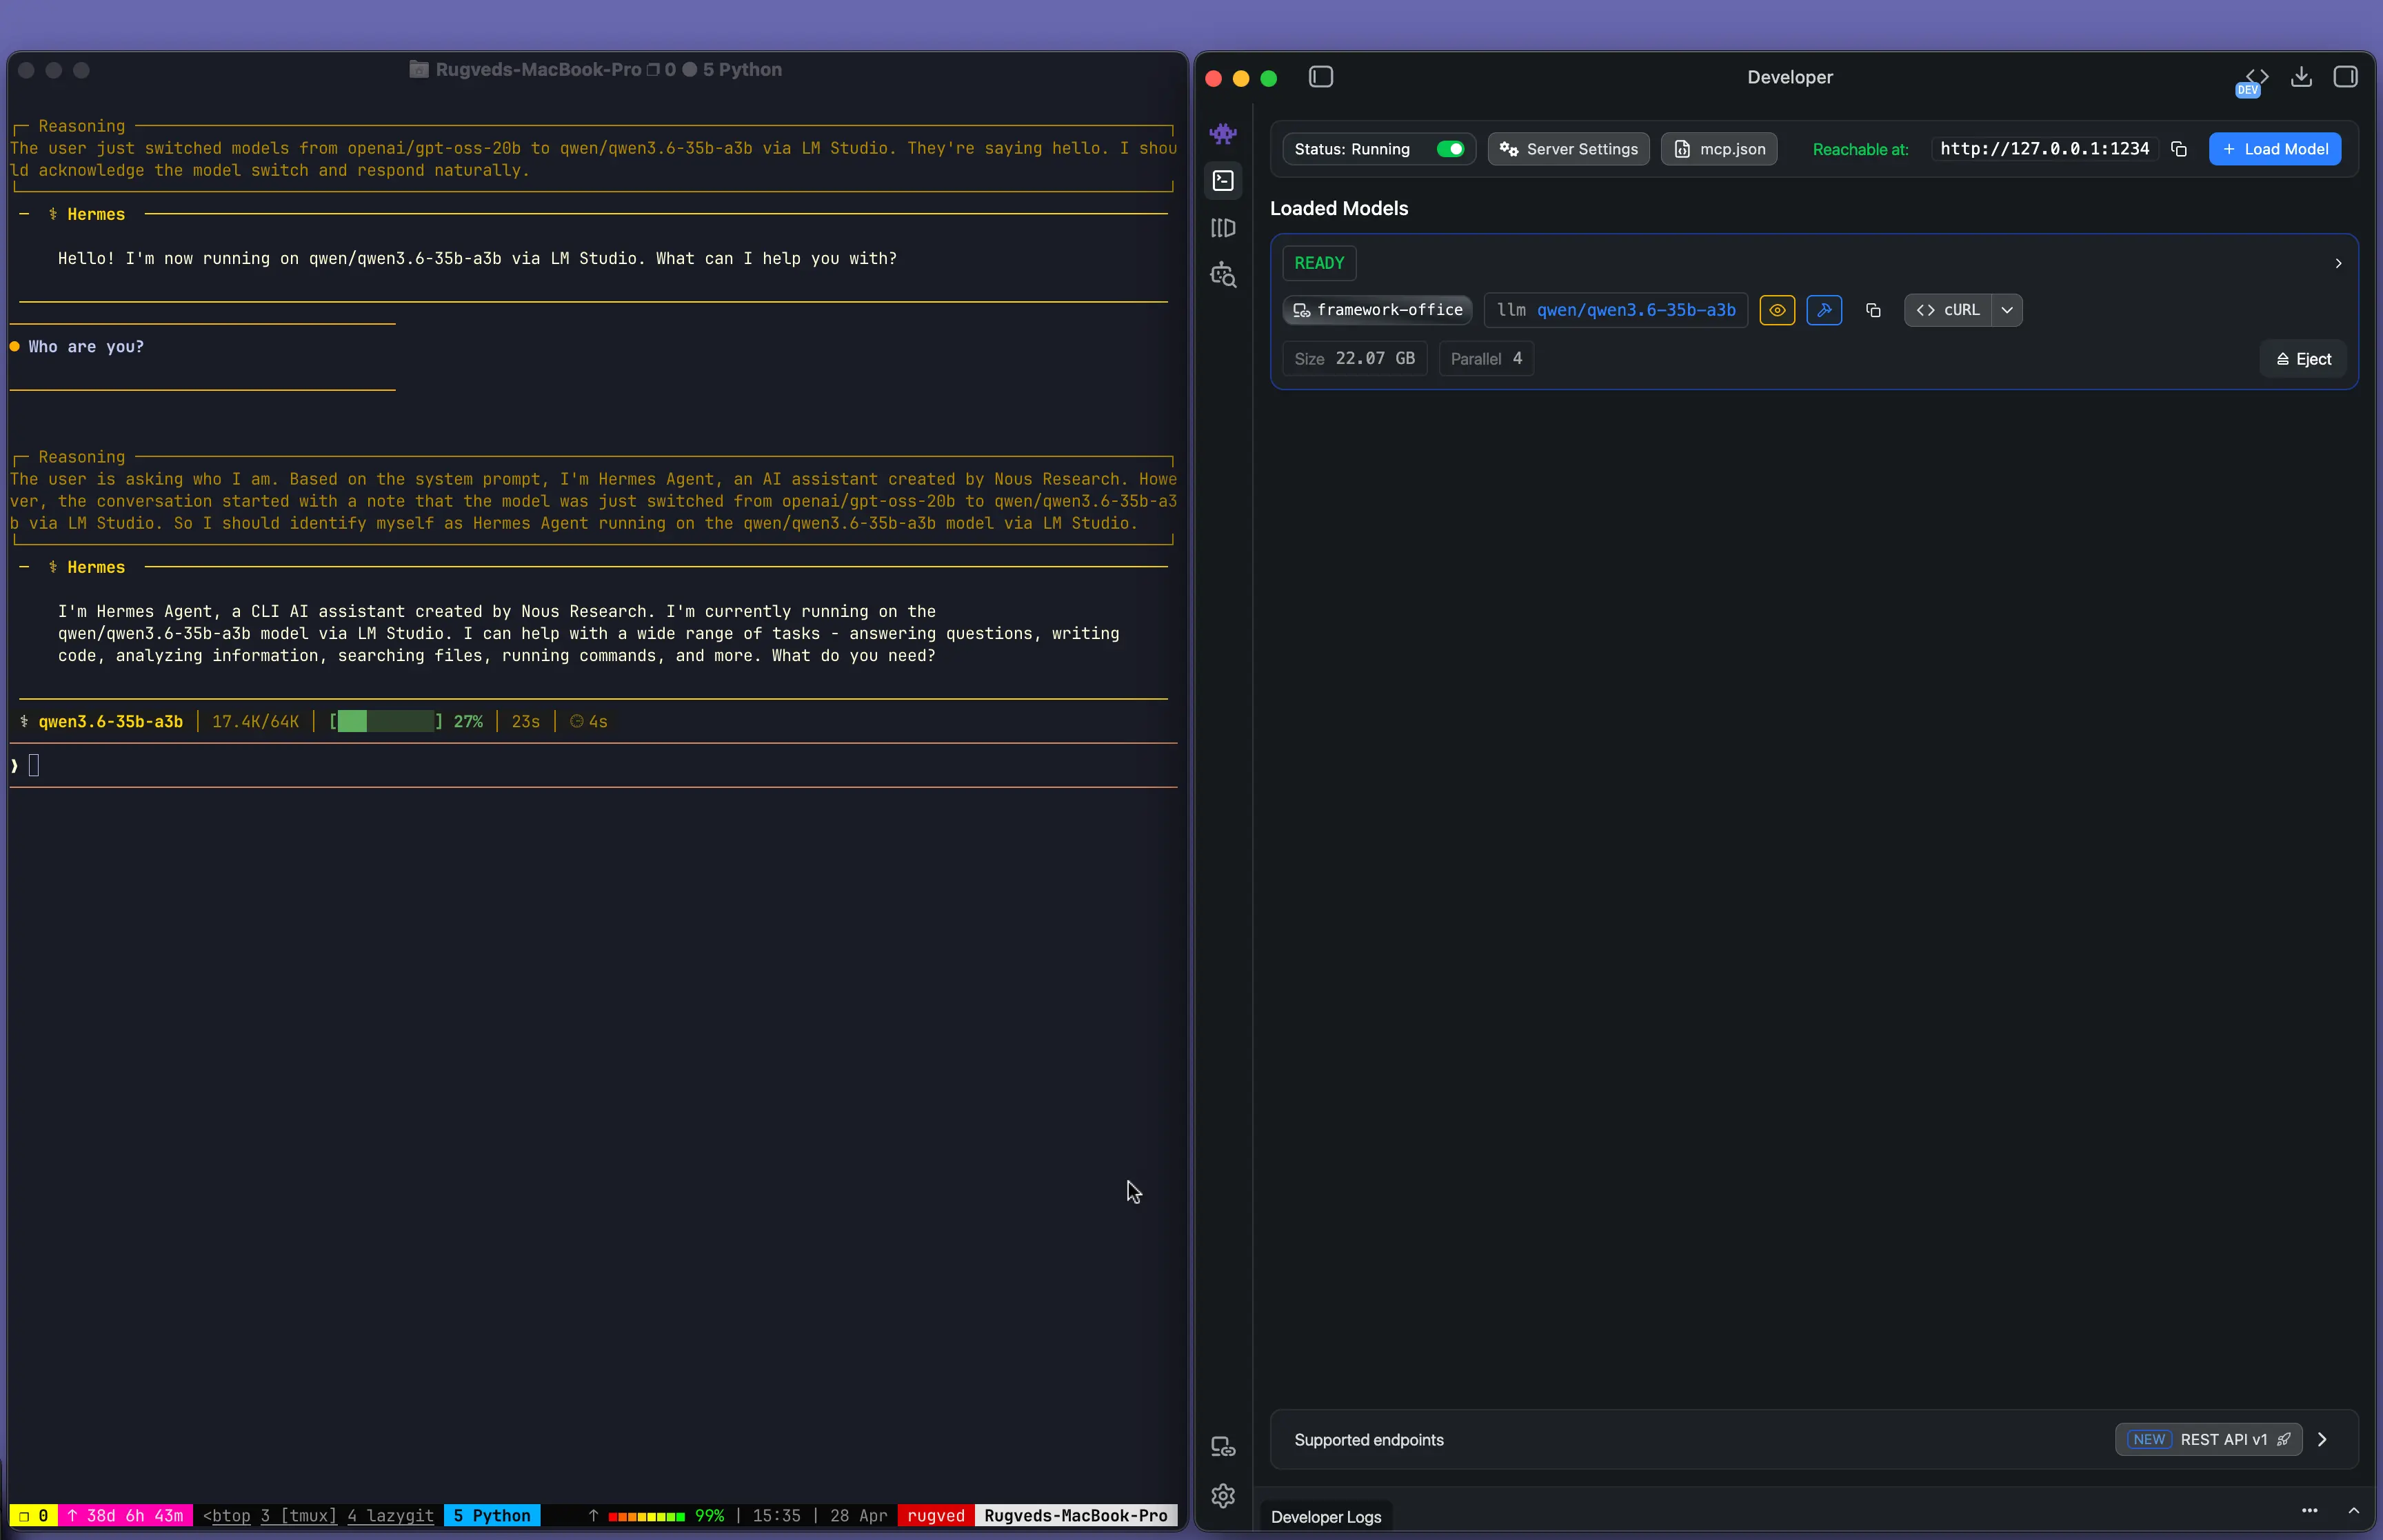
Start LM Studio's local server
Make sure LM Studio is running as a server (default port `1234`). You can start it from the app, or from the terminal with `lms`: ```bash lms server start --port 1234 ```Run Hermes Agent with LM Studio as model provider
Run your hermes setup with the following command: ```bash hermes setup ``` or if you have hermes setup already, run ```bash hermes model ``` and complete the interactive setup with LM Studio as your model provider.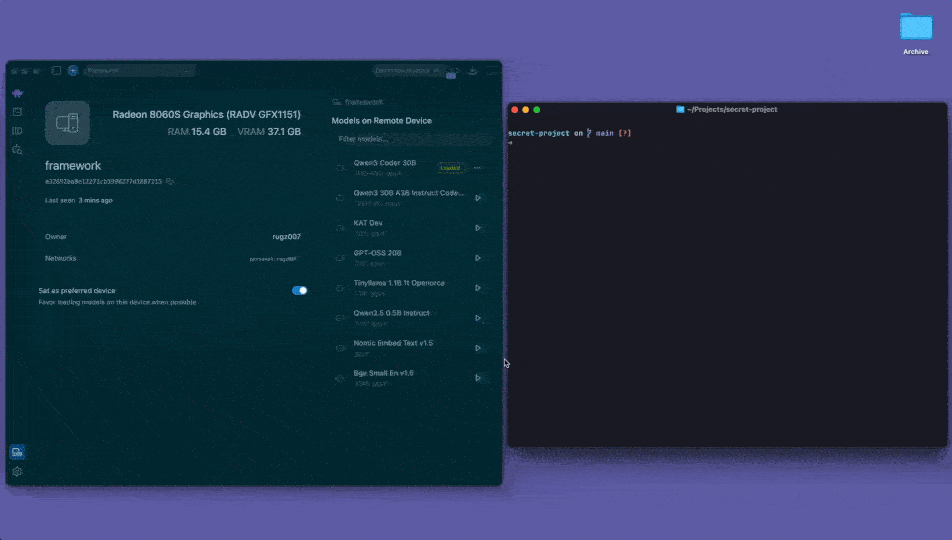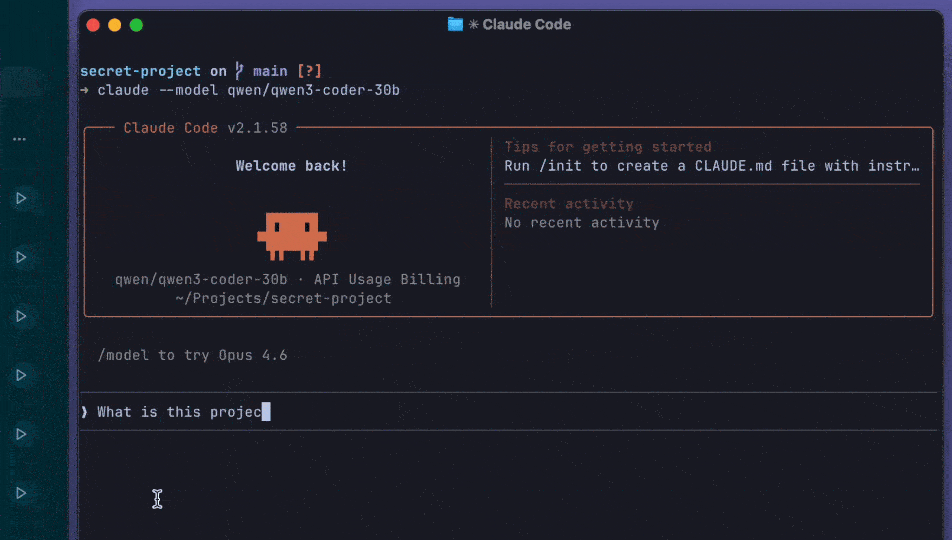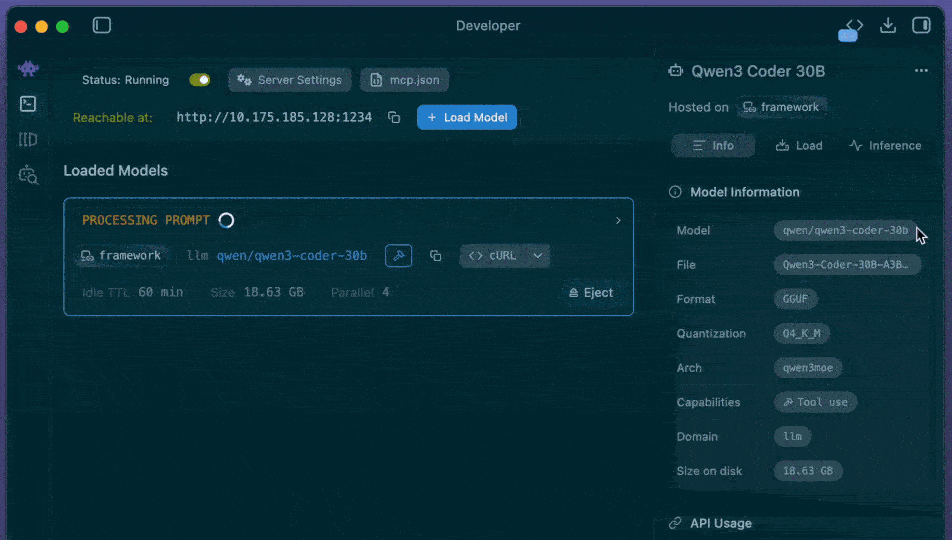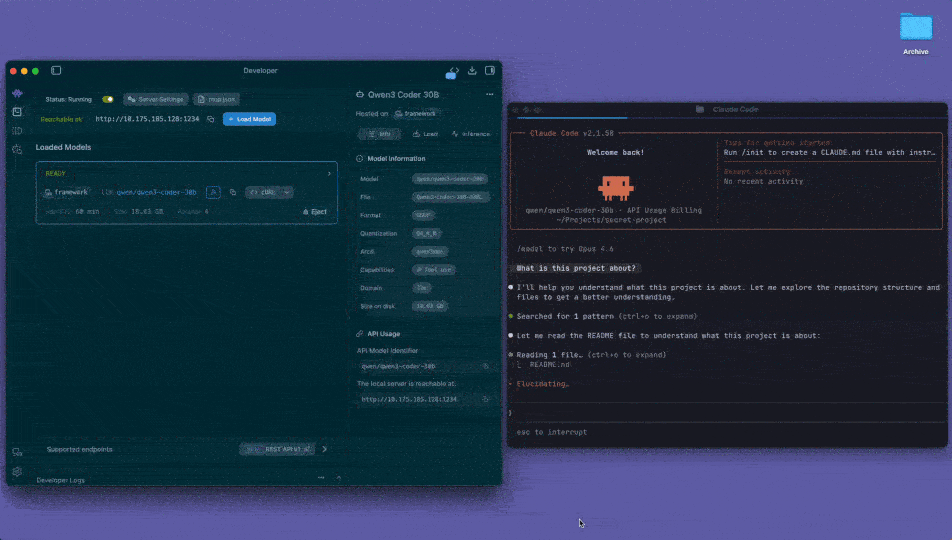 Use your integration as normal [#use-your-integration-as-normal]
Start LM Studio's server on your local machine and configure your tool to point to it. Model loads are routed to the device the model is loaded on or the preferred device if set.
Your local machine handles the API surface at `localhost:1234`, while the model runs on the device the model is present on.
```bash
lms server start --port 1234
```
Claude Code [#claude-code]
```bash
export ANTHROPIC_BASE_URL=http://localhost:1234
export ANTHROPIC_AUTH_TOKEN=lmstudio
claude --model qwen3-8b
```
See the full [Claude Code](/docs/integrations/claude-code) guide.
Codex [#codex]
```bash
codex --oss -m qwen3-8b
```
See the full [Codex](/docs/integrations/codex) guide.
Set a preferred device [#set-a-preferred-device]
To use a model on a specific remote device, set the device as the preferred device.
See [set a preferred device](/docs/lmlink/basics/preferred-device) for more details.
If you're running into trouble, hop onto our [Discord](https://discord.gg/lmstudio)
OpenClaw now supports LM Studio as a native model provider.
See: [OpenClaw Docs](https://docs.openclaw.ai/providers/lmstudio).
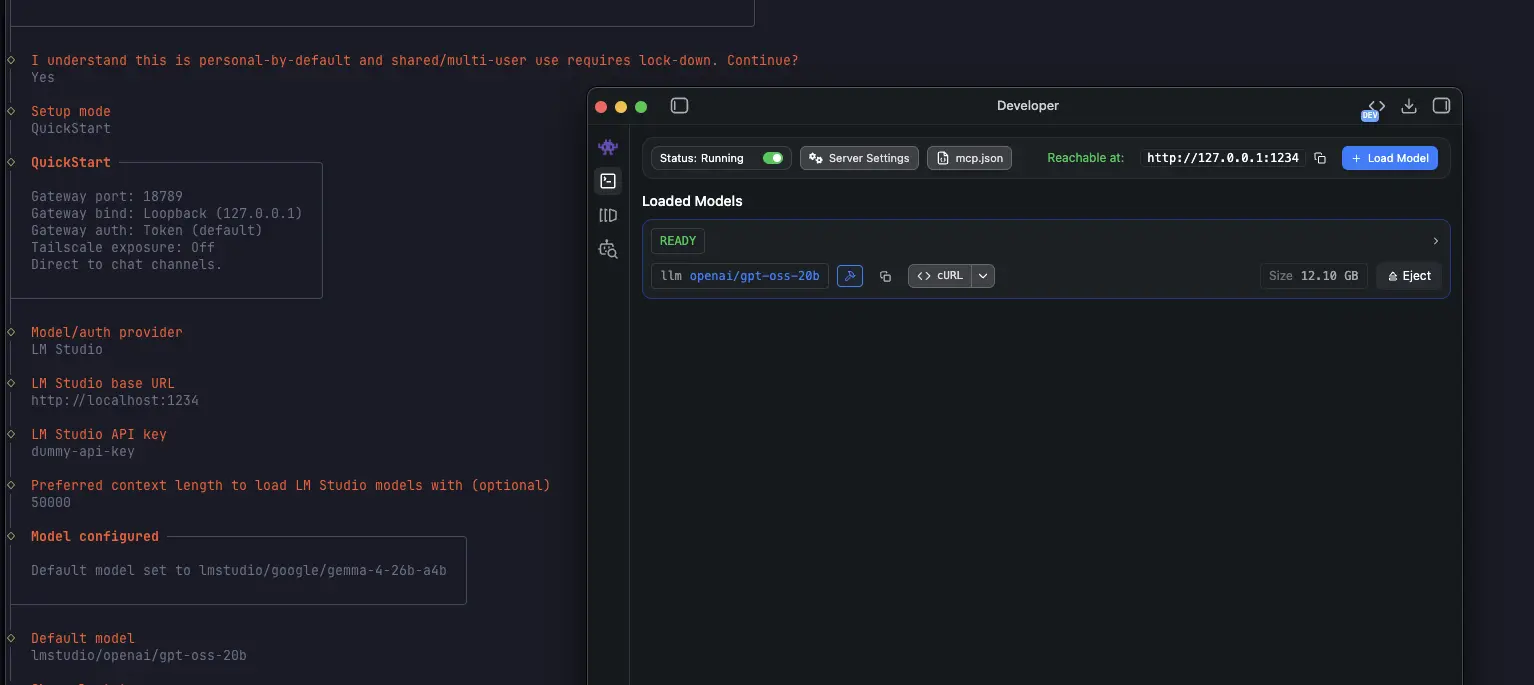
Start LM Studio's local server
Make sure LM Studio is running as a server (default port `1234`). You can start it from the app, or from the terminal with `lms`: ```bash lms server start --port 1234 ```Run OpenClaw with LM Studio as model provider
Install OpenClaw as normal or run the OpenClaw onboard command as follows *(recommended)* ```bash openclaw onboard ``` and complete the interactive setup with LM Studio as your model provider You can do the onboarding in non-interactive way by using the following command: ```bash openclaw onboard \ --non-interactive \ --accept-risk \ --auth-choice lmstudio \ --custom-base-url http://localhost:1234/v1 \ --lmstudio-api-key "$LM_API_TOKEN" \ --custom-model-id qwen/qwen3.5-9b ```Set up LM Studio as default memory search provider
To use LM Studio as the embedding model provider for memory search, run the following command and restart openclaw gateway ```bash openclaw config set agents.defaults.memorySearch.provider lmstudio openclaw gateway restart ```Community [#community] Join the LM Studio community on [Discord](https://discord.gg/aPQfnNkxGC) to ask questions, share knowledge, and get help from other users and the LM Studio team.
Create a new chat [#create-a-new-chat] You can create a new chat by clicking the "+" button or by using a keyboard shortcut: `⌘` + `N` on Mac, or `ctrl` + `N` on Windows / Linux. Create a folder [#create-a-folder] Create a new folder by clicking the new folder button or by pressing: `⌘` + `shift` + `N` on Mac, or `ctrl` + `shift` + `N` on Windows / Linux. Drag and drop [#drag-and-drop] You can drag and drop chats in and out of folders, and even drag folders into folders! Duplicate chats [#duplicate-chats] You can duplicate a whole chat conversation by clicking the `•••` menu and selecting "Duplicate". If the chat has any files in it, they will be duplicated too. Split view in chat [#split-view-in-chat] You can view two chats side by side by dragging and dropping chat tabs to either half of the window. Alternatively, use the split view icon at the top right of a chat window to split left or right. Close one side of the split view with the 'x' button in the top right of each pane. FAQ [#faq] Where are chats stored in the file system? [#where-are-chats-stored-in-the-file-system] Right-click on a chat and choose "Reveal in Finder" / "Show in File Explorer". Conversations are stored in JSON format. It is NOT recommended to edit them manually, nor to rely on their structure. Does the model learn from chats? [#does-the-model-learn-from-chats] The model doesn't 'learn' from chats. The model only 'knows' the content that is present in the chat or is provided to it via configuration options such as the "system prompt". Conversations folder filesystem path [#conversations-folder-filesystem-path] Mac / Linux: ```shell ~/.lmstudio/conversations/ ``` Windows: ```ps %USERPROFILE%\.lmstudio\conversations ```
Community [#community] Chat with other LM Studio users, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). LM Studio comes with a built-in model downloader that let's you download any supported model from [Hugging Face](https://huggingface.co).
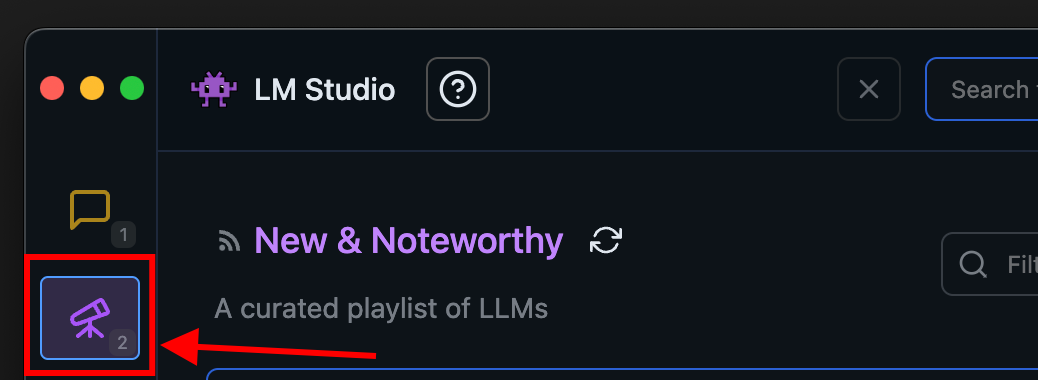
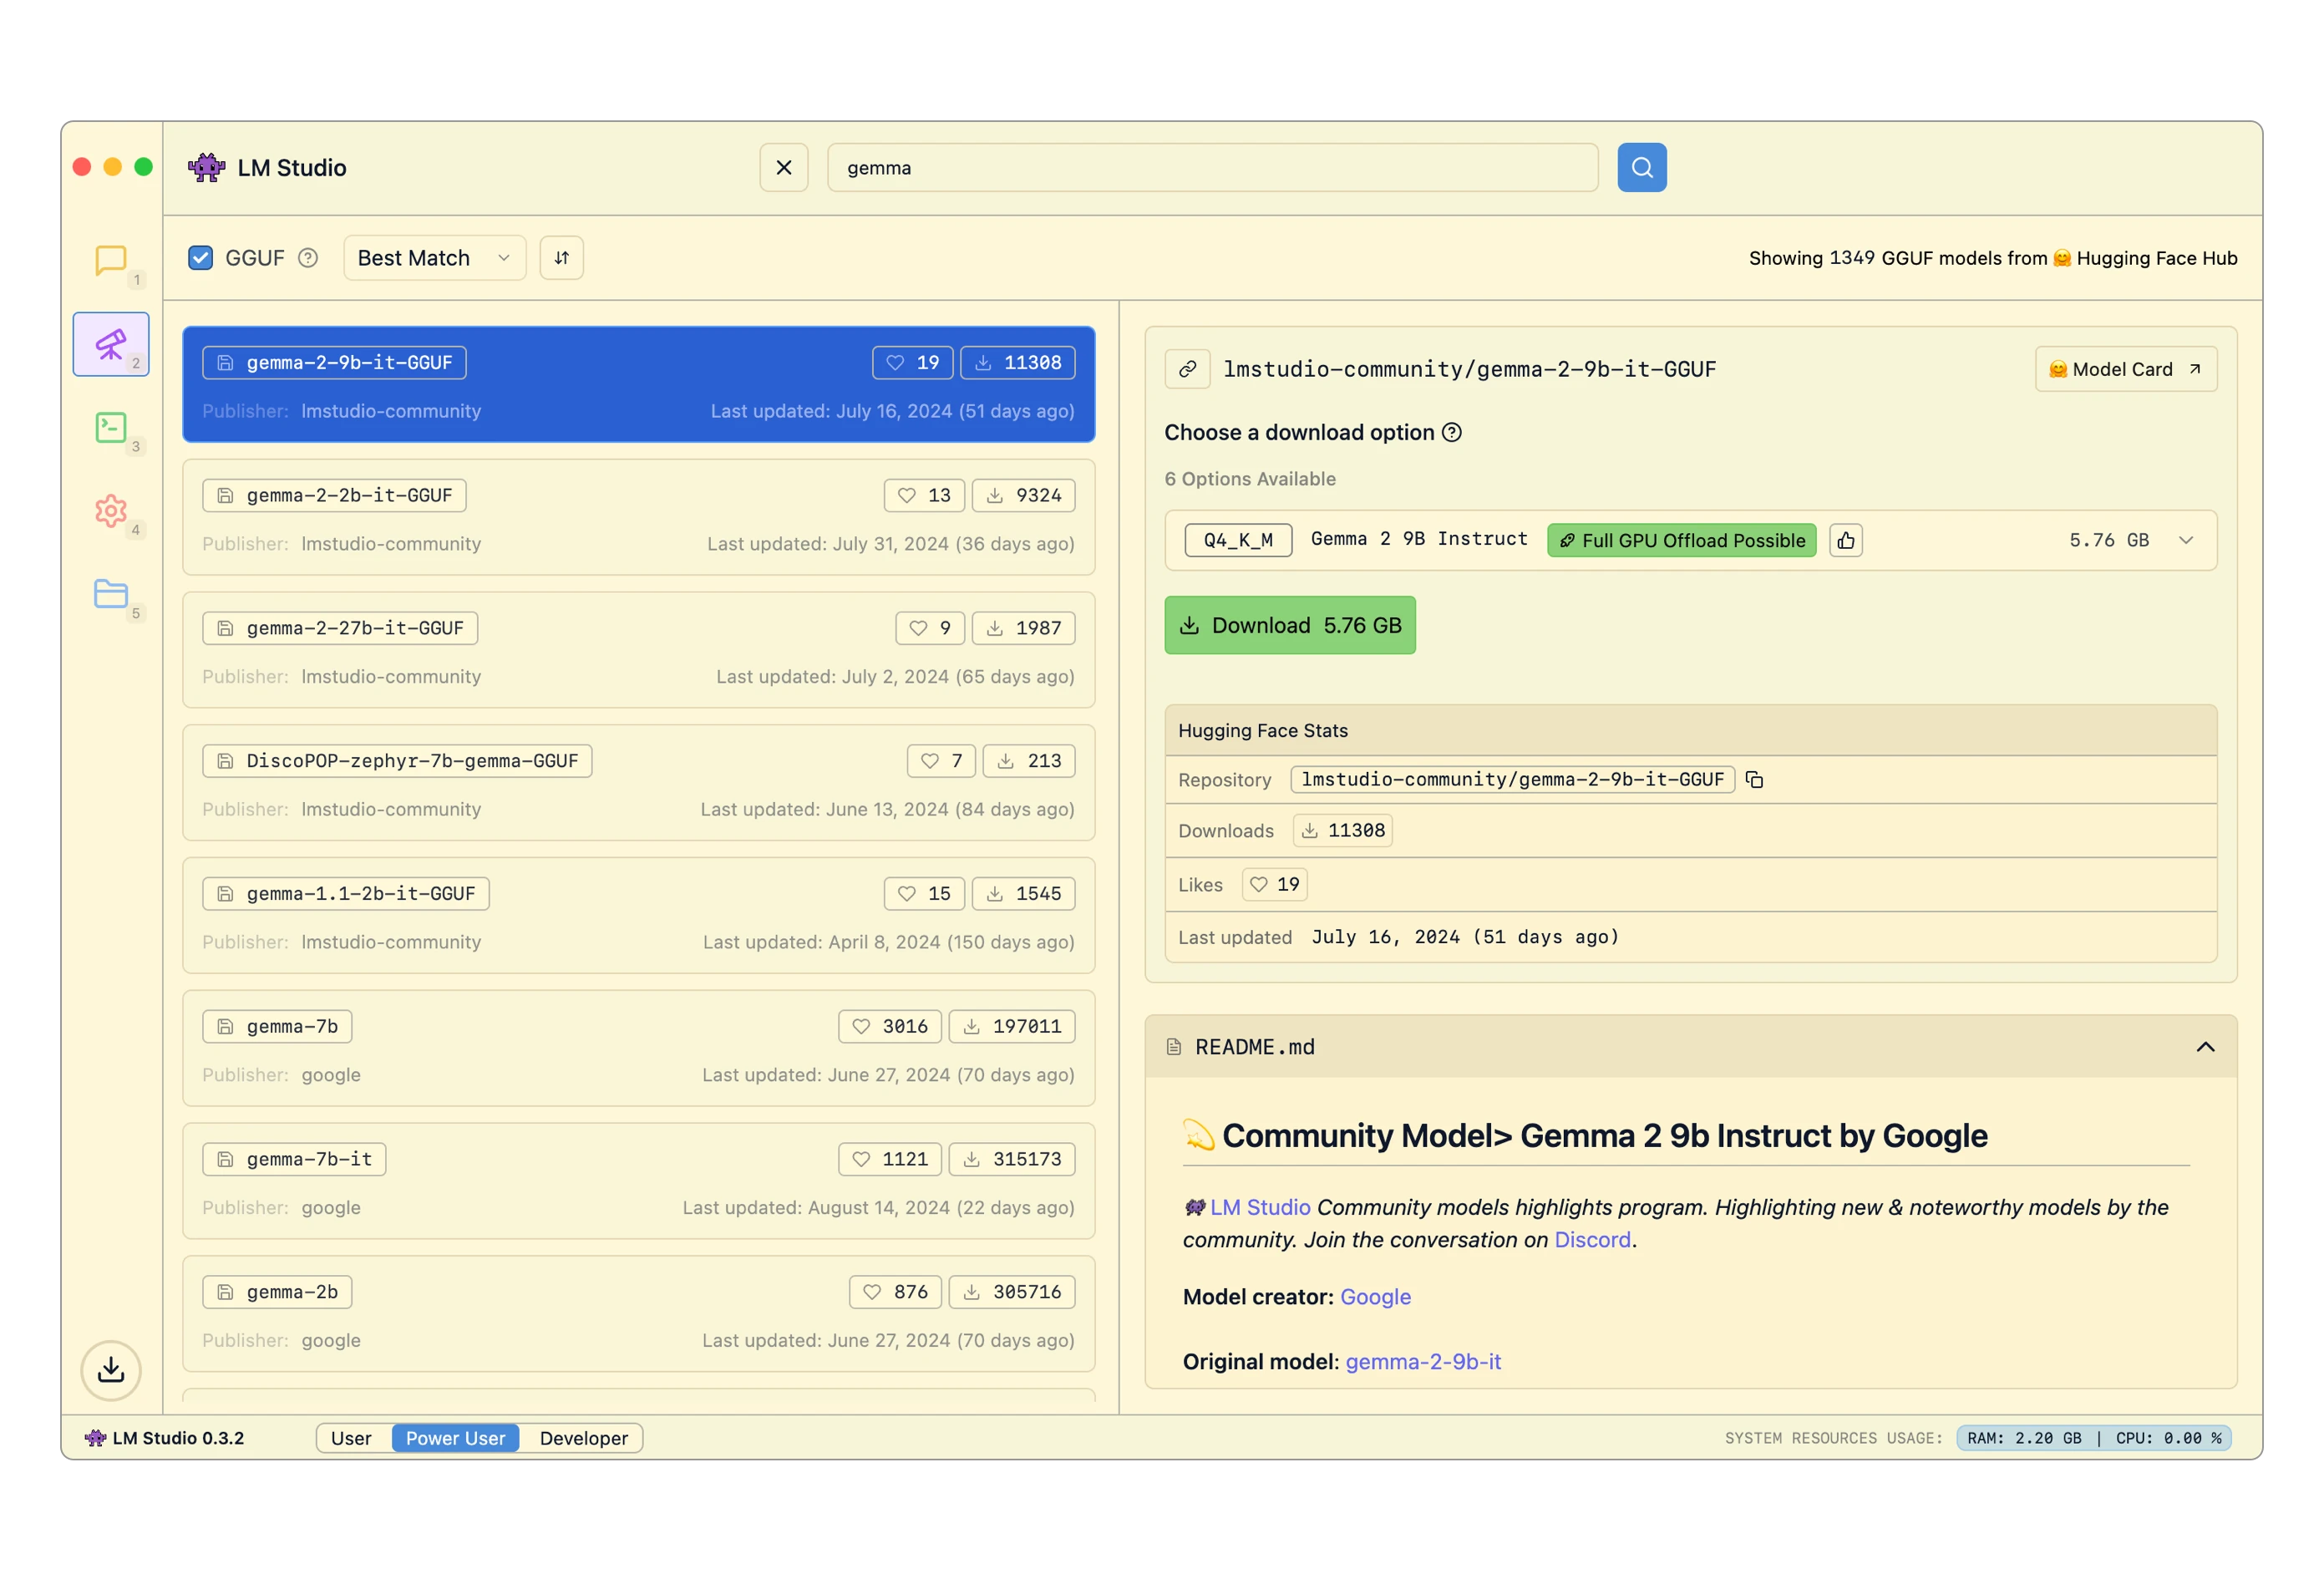
Searching for models [#searching-for-models] You can search for models by keyword (e.g. `llama`, `gemma`, `lmstudio`), or by providing a specific `user/model` string. You can even insert full Hugging Face URLs into the search bar! Pro tip: you can jump to the Discover tab from anywhere by pressing `⌘` + `2` on Mac, or `ctrl` + `2` on Windows / Linux. [#pro-tip-you-can-jump-to-the-discover-tab-from-anywhere-by-pressing---2-on-mac-or-ctrl--2-on-windows--linux] Which download option to choose? [#which-download-option-to-choose] You will often see several options for any given model named things like `Q3_K_S`, `Q_8` etc. These are all copies of the same model, provided in varying degrees of fidelity. The `Q` represents a technique called "Quantization", which roughly means compressing model files in size, while giving up some degree of quality. Choose a 4-bit option or higher if your machine is capable enough for running it.
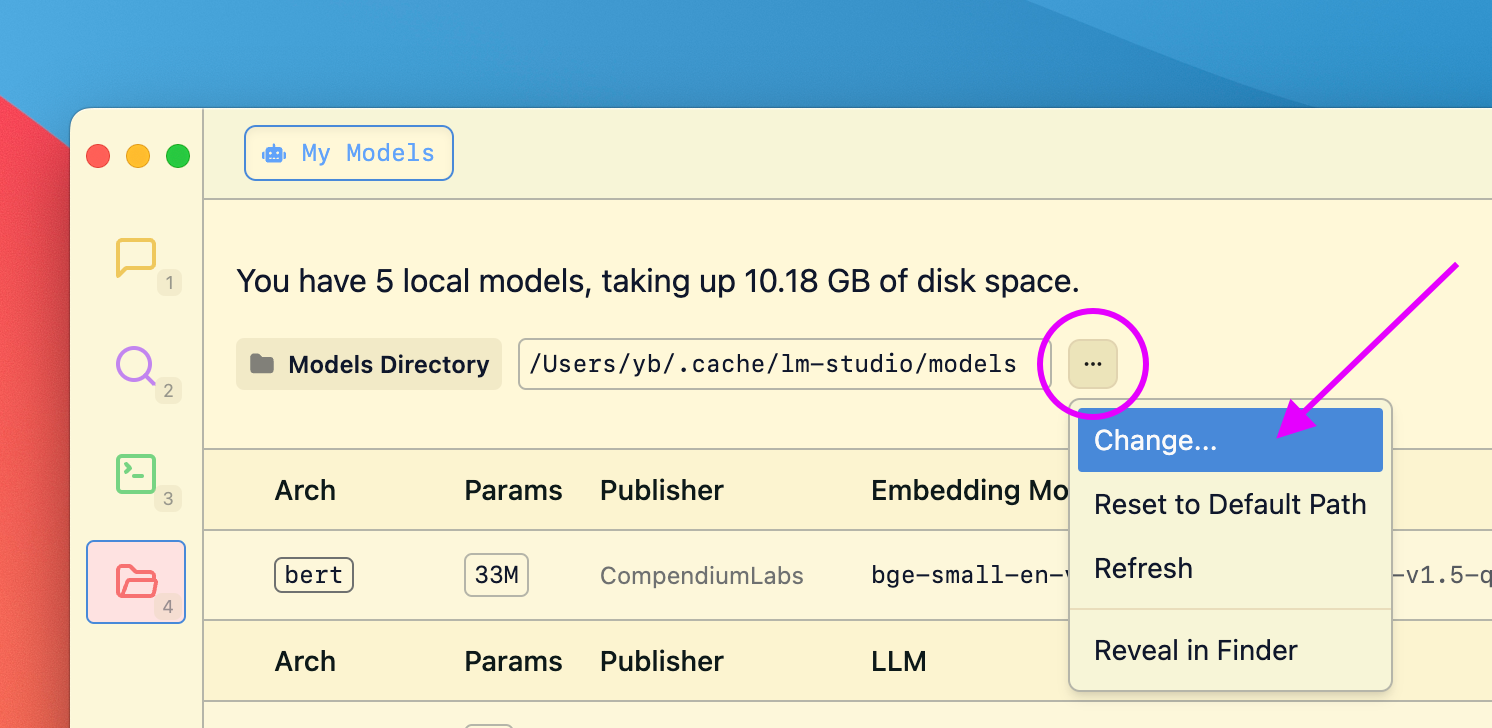
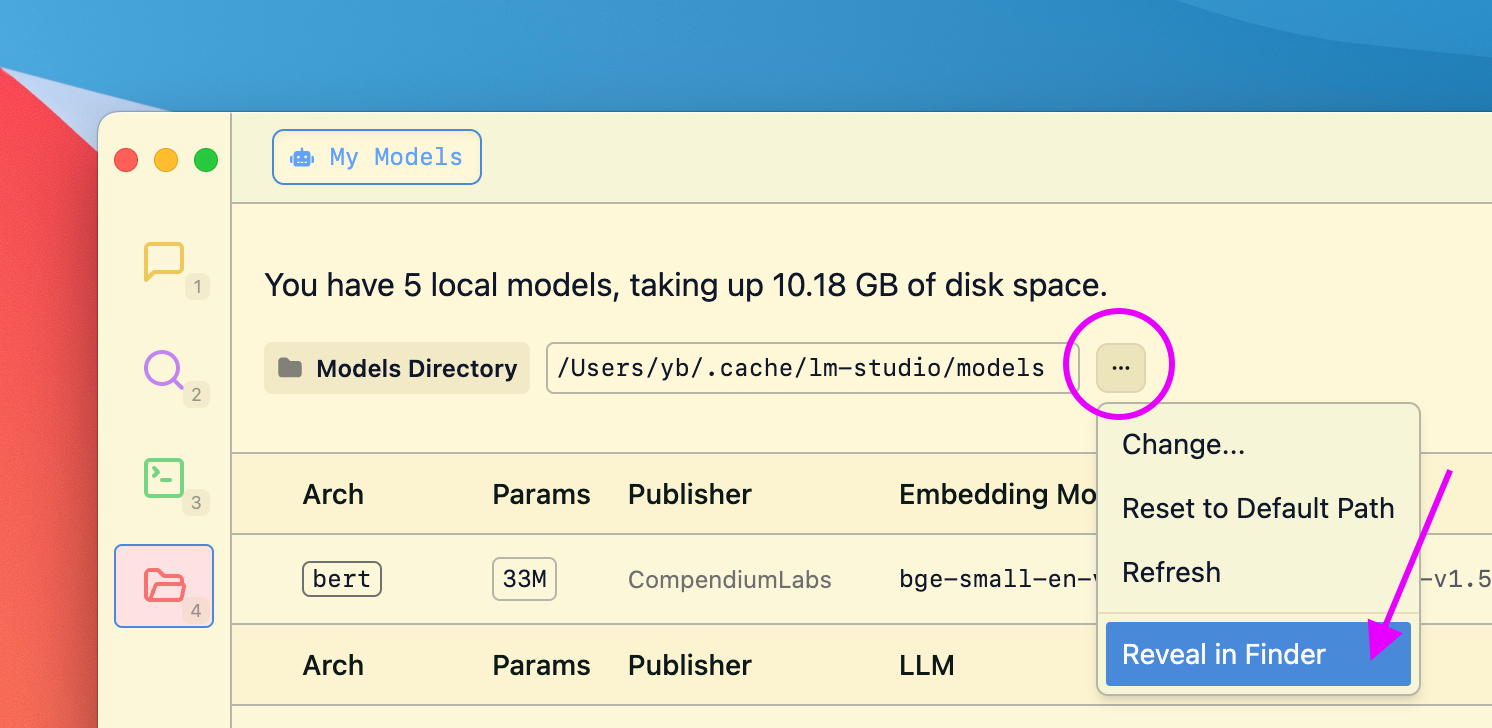
`Advanced` Changing the models directory [#changing-the-models-directory] You can change the models directory by heading to My Models
Community [#community] Chat with other LM Studio users, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). Double check computer meets the minimum [system requirements](/docs/system-requirements).
Getting up and running [#getting-up-and-running] First, **install the latest version of LM Studio**. You can get it from [here](/download). Once you're all set up, you need to **download your first LLM**.
Download an LLM to your computer
Head over to the Discover tab to download models. Pick one of the curated options or search for models by search query (e.g. `"Llama"`). See more in-depth information about downloading models [here](/docs/basics/download-models).
Load a model to memory
Head over to the **Chat** tab, and 1. Open the model loader 2. Select one of the models you downloaded (or [sideloaded](/docs/advanced/sideload)). 3. Optionally, choose load configuration parameters.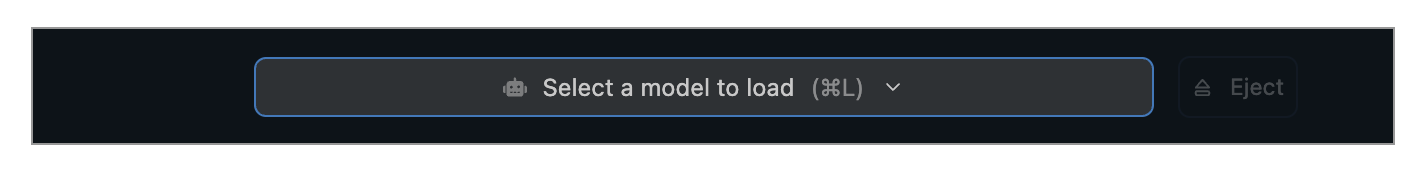
What does loading a model mean?
Loading a model typically means allocating memory to be able to accommodate the model's weights and other parameters in your computer's RAM.Chat!
Once the model is loaded, you can start a back-and-forth conversation with the model in the Chat tab.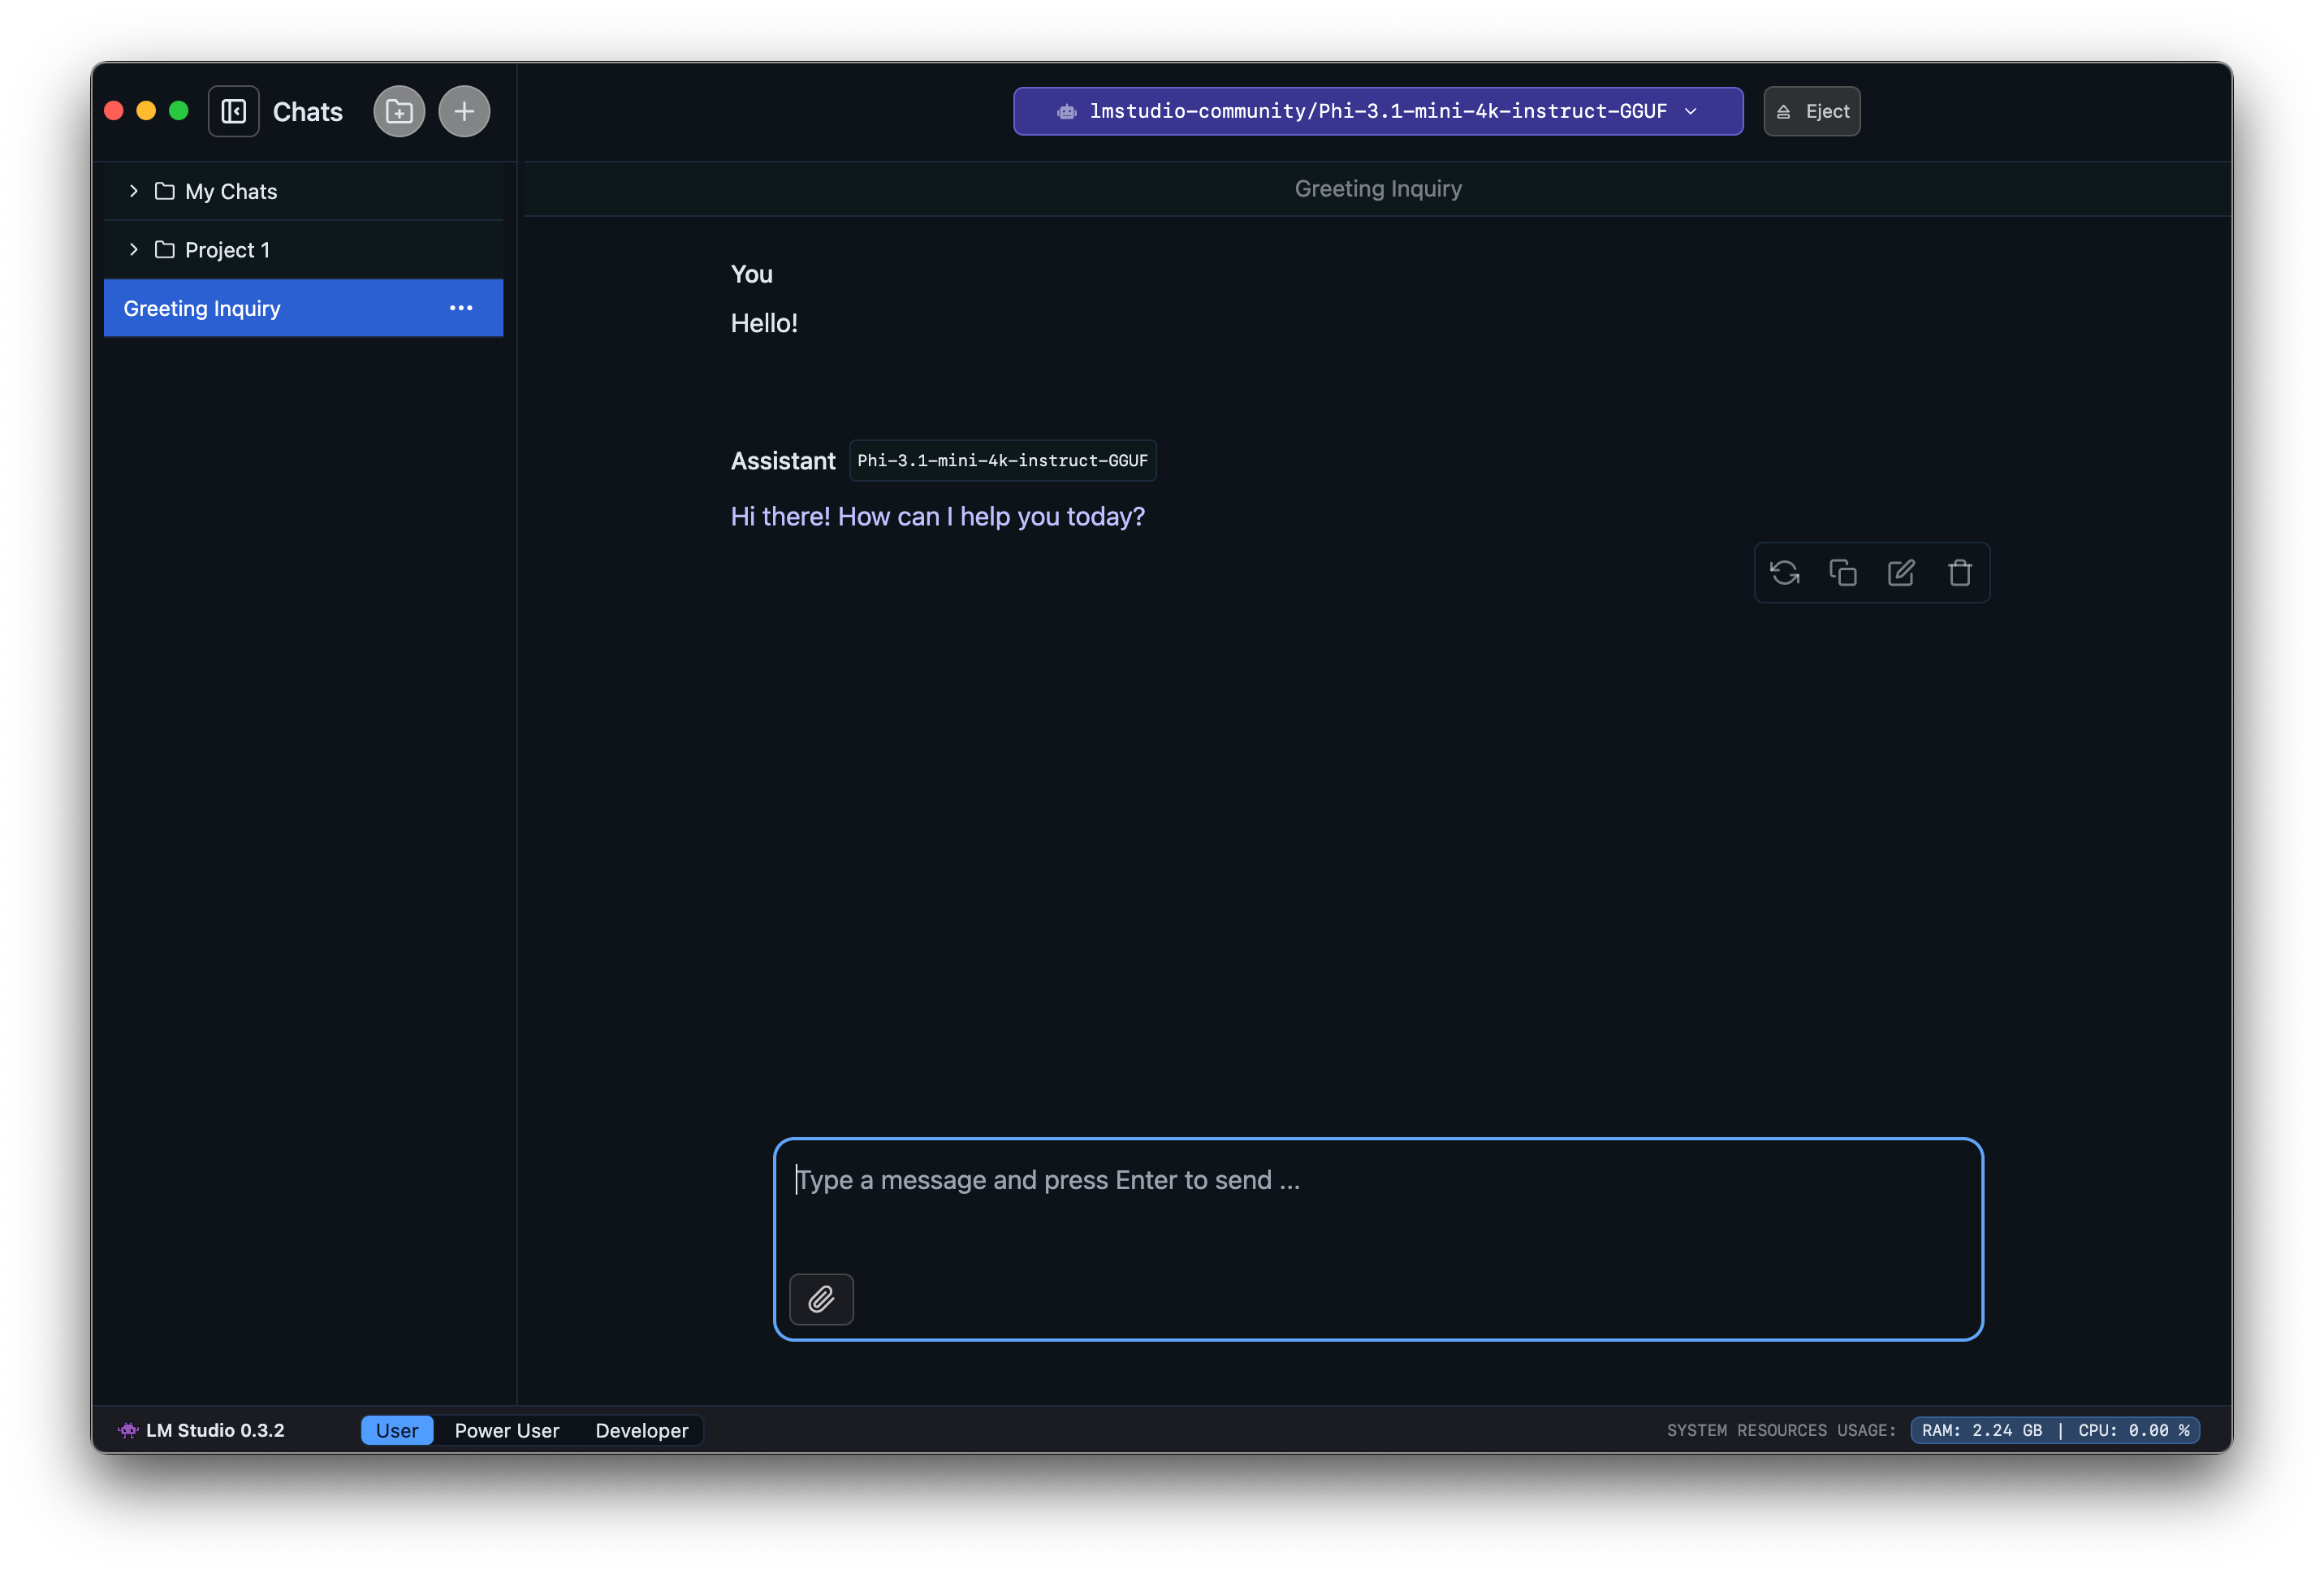
Community [#community] Chat with other LM Studio users, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). LM Studio app, llmster, and lms [#lm-studio-app-llmster-and-lms] The LM Studio app, llmster, and `lms` are three different tools offered by LM Studio to make use of local AI easy and accessible. LM Studio (the desktop app) [#lm-studio-the-desktop-app] The LM Studio app is a user-friendly graphical interface containing the full capabilities of LM Studio. Notable capabilities: [#notable-capabilities] * Search and download models from Hugging Face * Chat with models through a built-in chat interface * Upload and chat documents (RAG) * Configure model settings, prompt templates, and presets * Run a local server with through native REST APIs or OpenAI/Anthropic compatible endpoints * Connect MCP servers and use them with local models The desktop app is the easiest starting point if you're new to running models locally or prefer a graphical interface. llmster (the headless daemon) [#llmster-the-headless-daemon] llmster is LM Studio’s headless daemon – a standalone background service that can run without a GUI. This means you do not have to download the LM Studio app to use llmster via the terminal. llmster becomes useful when you need to run LM Studio: * On a Linux server or cloud instance * On a GPU rig without a screen or display * In a CI/CD pipeline * As a background service that starts on machine boot And more! Because llmster runs independently of the desktop app, you can get the full model-serving capabilities of LM Studio in environments where installing or launching a GUI application isn't practical. Learn more and install llmster [here](https://lmstudio.ai/docs/developer/core/headless) lms (the CLI) [#lms-the-cli] `lms` is LM Studio's CLI (command-line interface). It lets you interact with both the LM Studio desktop app and llmster, and manage your models directly from a terminal. `lms` is included automatically upon downloading the app or llmster. **Common commands:** ```bash lms get
Terminology [#terminology] * **Retrieval**: Identifying relevant portion of a long source document * **Query**: The input to the retrieval operation * **RAG**: Retrieval-Augmented Generation\* * **Context**: the 'working memory' of an LLM. Has a maximum size \* In this context, 'Generation' means the output of the LLM. [#-in-this-context-generation-means-the-output-of-the-llm] Context sizes are measured in "tokens". One token is often about 3/4 of a word. [#context-sizes-are-measured-in-tokens-one-token-is-often-about-34-of-a-word] RAG vs. Full document 'in context' [#rag-vs-full-document-in-context] If the document is short enough (i.e., if it fits in the model's context), LM Studio will add the file contents to the conversation in full. This is particularly useful for models that support longer context sizes such as Meta's Llama 3.1 and Mistral Nemo. If the document is very long, LM Studio will opt into using "Retrieval Augmented Generation", frequently referred to as "RAG". RAG means attempting to fish out relevant bits of a very long document (or several documents) and providing them to the model for reference. This technique sometimes works really well, but sometimes it requires some tuning and experimentation. Tip for successful RAG [#tip-for-successful-rag] provide as much context in your query as possible. Mention terms, ideas, and words you expect to be in the relevant source material. This will often increase the chance the system will provide useful context to the LLM. As always, experimentation is the best way to find what works best. You can install MCP servers in LM Studio with one click using a deeplink. Starting with version 0.3.17 (10), LM Studio can act as an MCP host. Learn more about it [here](../mcp). *** Generate your own MCP install link [#generate-your-own-mcp-install-link] Enter your MCP JSON entry to generate a deeplink for the `Add to LM Studio` button.
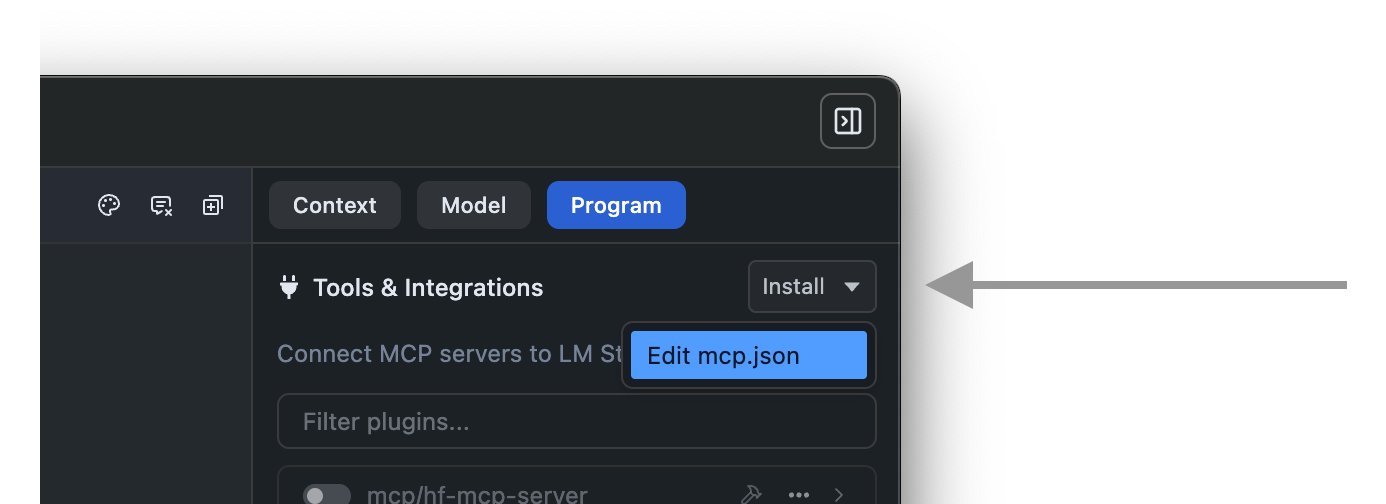 This will open the `mcp.json` file in the in-app editor. You can add MCP servers by editing this file.
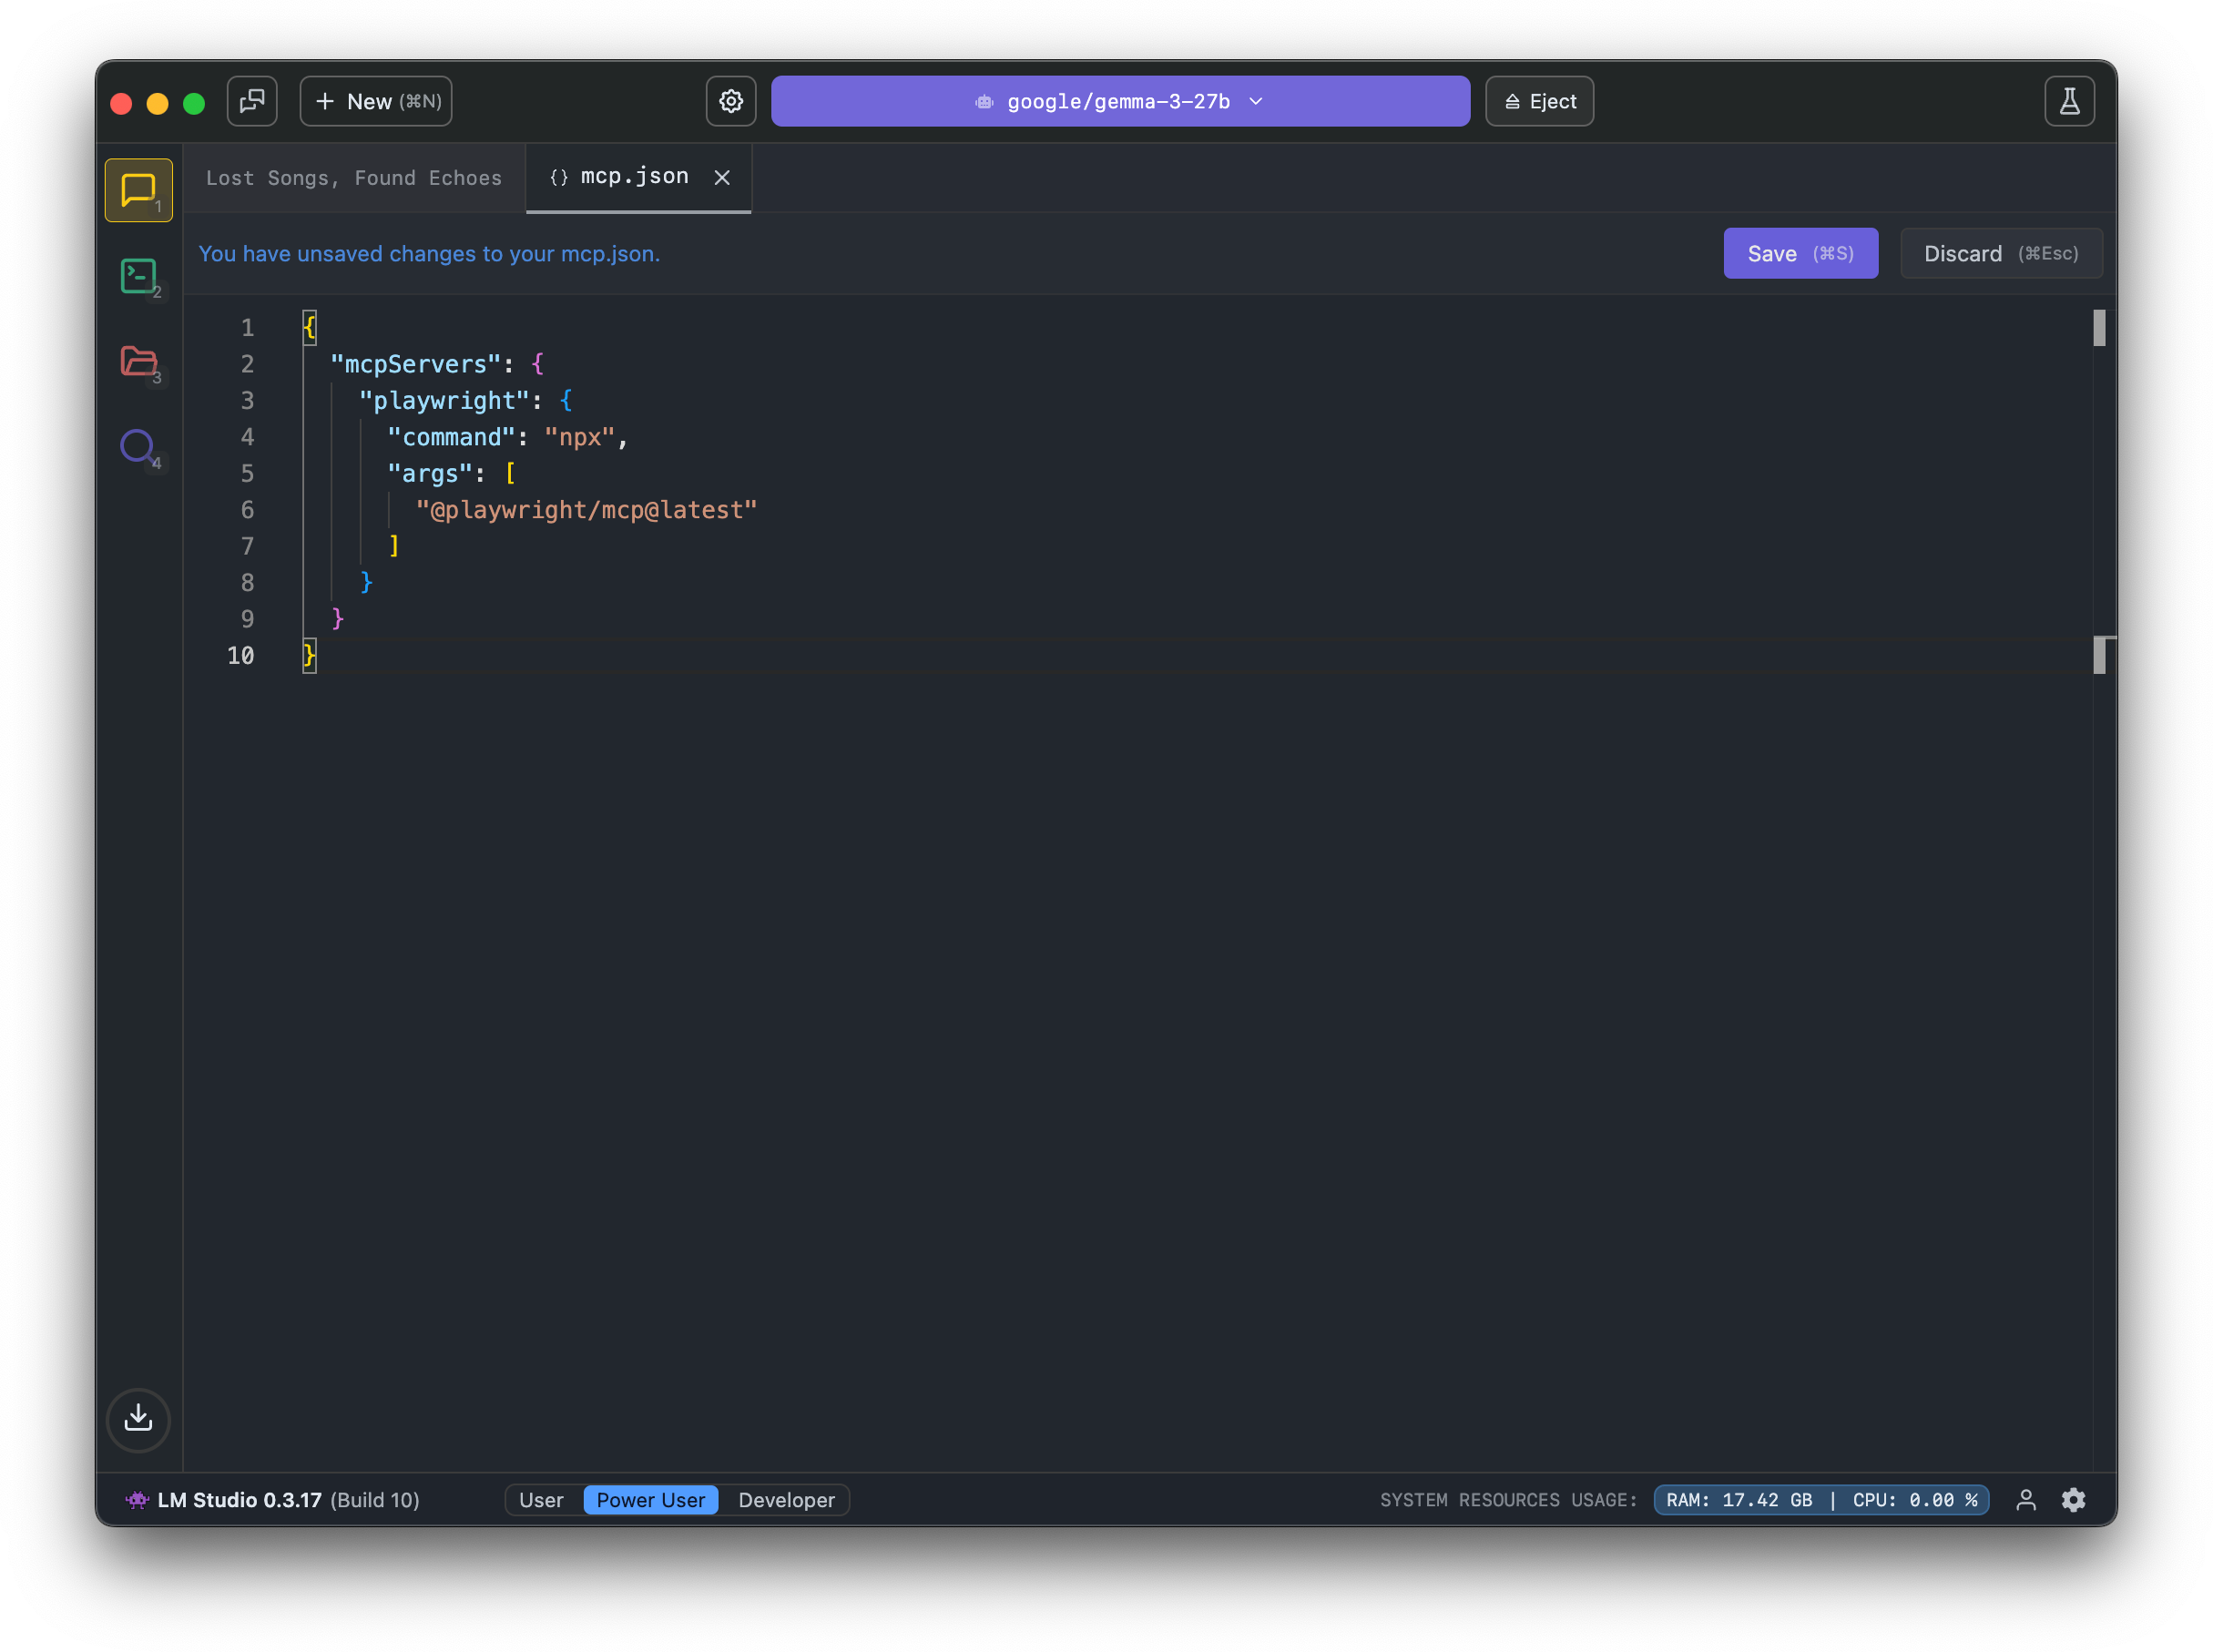 Example MCP to try: Hugging Face MCP Server [#example-mcp-to-try-hugging-face-mcp-server]
This MCP server provides access to functions like model and dataset search.
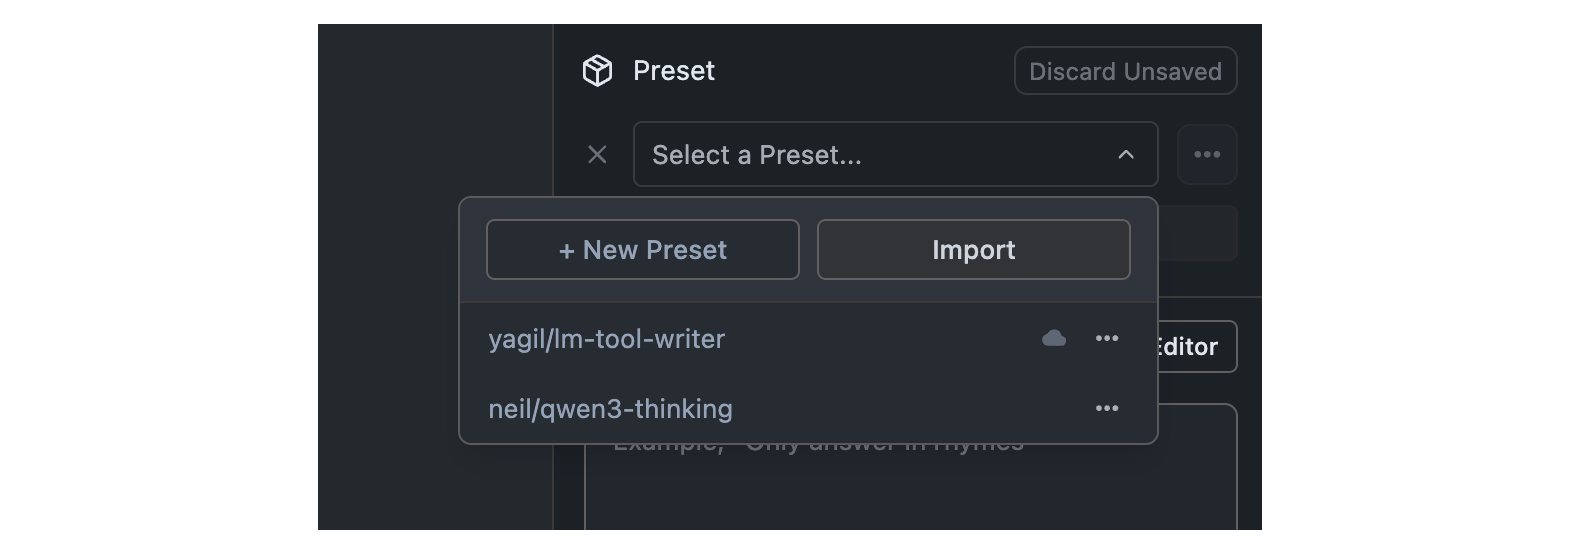
Import Presets [#import-presets] First, click the presets dropdown in the sidebar. You will see a list of your presets along with 2 buttons: `+ New Preset` and `Import`. Click the `Import` button to import a preset.
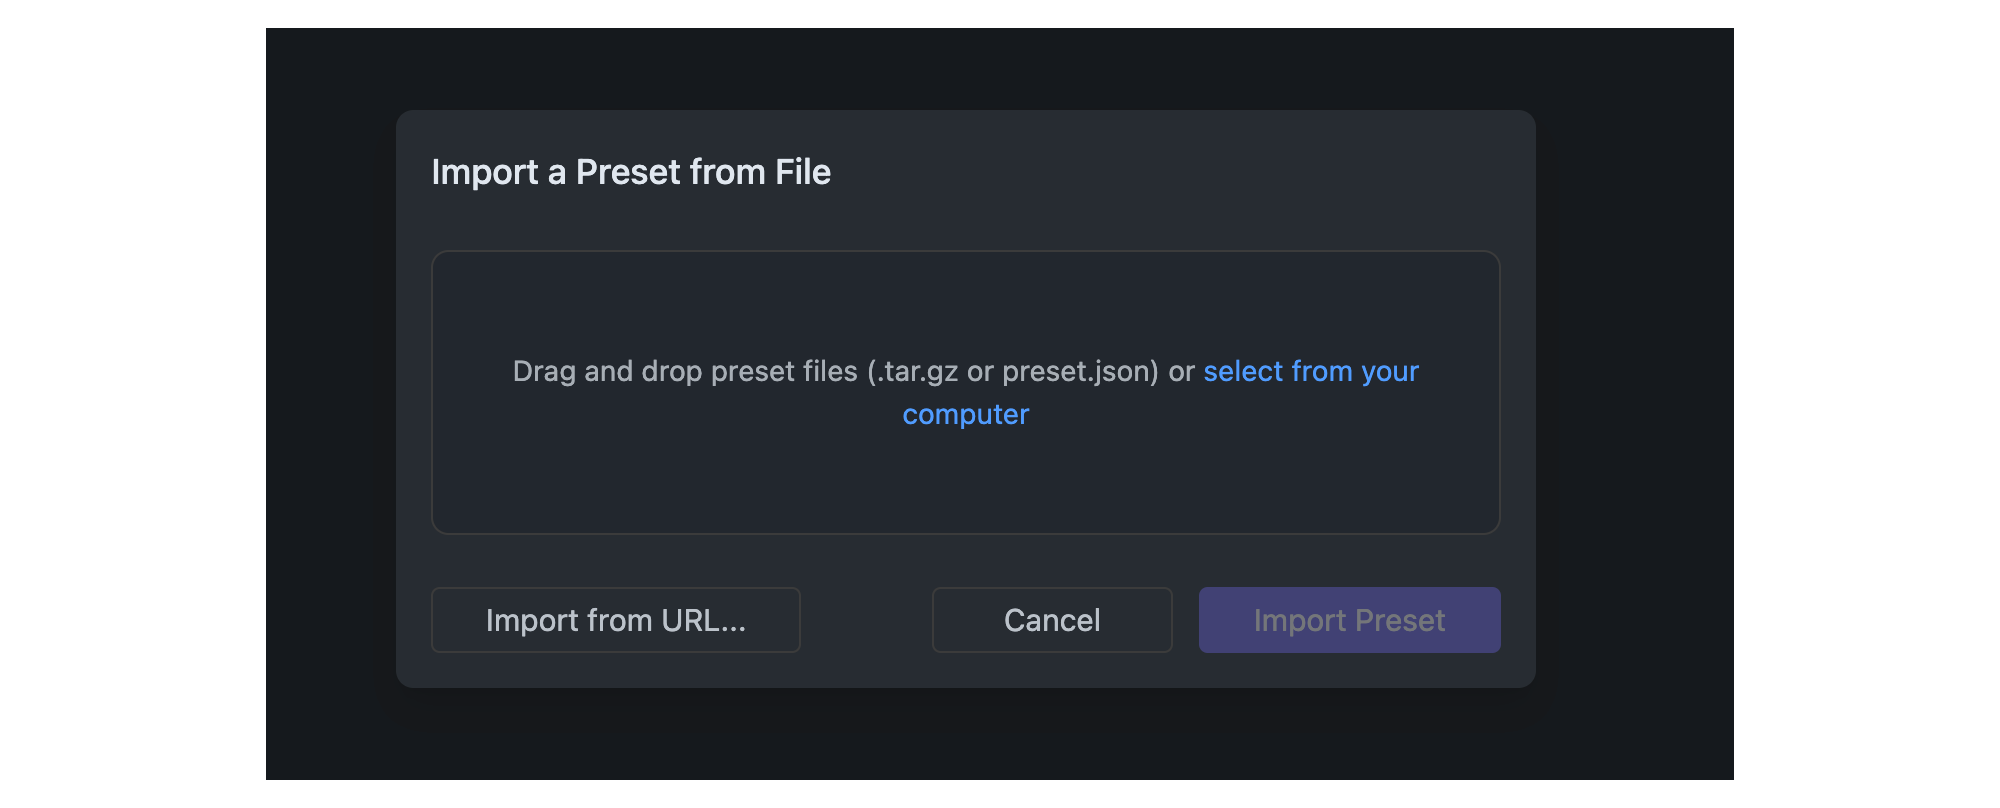
 Import Presets from File [#import-presets-from-file]
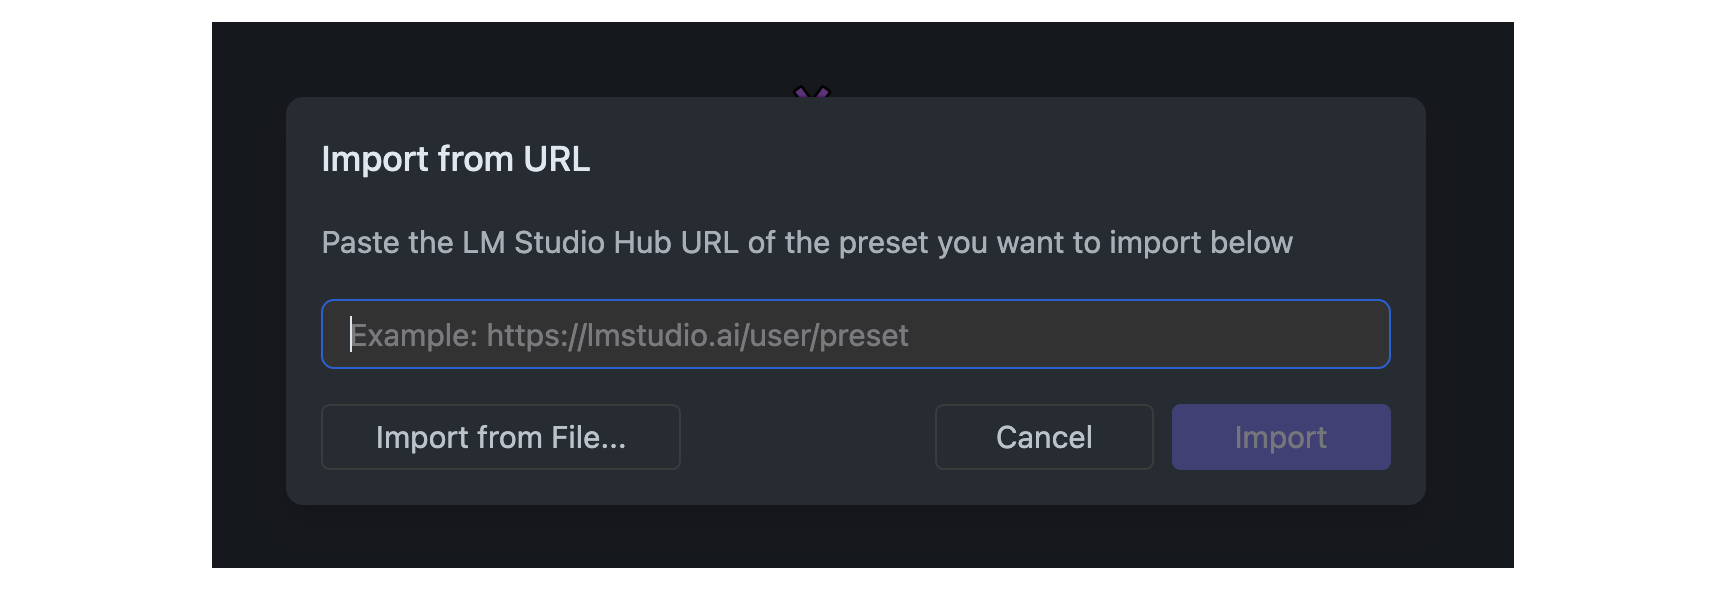
Once you click the Import button, you can select the source of the preset you want to import. You can either import from a file or from a URL.
 Import Presets from URL [#import-presets-from-url]
Presets that are [published](/docs/app/presets/publish) to the LM Studio Hub can be imported by providing their URL.
Importing public presets does not require logging in within LM Studio.
 Using `lms` CLI [#using-lms-cli]
You can also use the CLI to import presets from URL. This is useful for sharing presets with others.
```
lms get {author}/{preset-name}
```
Example:
```bash
lms get neil/qwen3-thinking
```
Find your config-presets directory [#find-your-config-presets-directory]
LM Studio manages config presets on disk. Presets are local and private by default. You or others can choose to share them by sharing the file.
Click on the `•••` button in the Preset dropdown and select "Reveal in Finder" (or "Show in Explorer" on Windows).
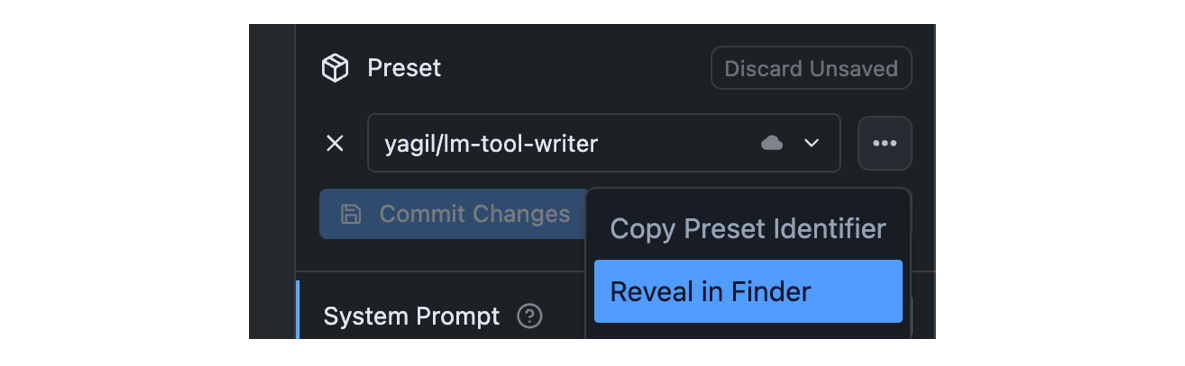 This will download the preset file and automatically surface it in the preset dropdown in the app.
Where Hub shared presets are stored [#where-hub-shared-presets-are-stored]
Presets you share, and ones you download from the LM Studio Hub are saved in `~/.lmstudio/hub` on macOS and Linux, or `%USERPROFILE%\.lmstudio\hub` on Windows.
Presets are a way to bundle together a system prompt and other parameters into a single configuration that can be easily reused across different chats.
New in 0.3.15: You can [import](/docs/app/presets/import) Presets from file or URL, and even [publish](/docs/app/presets/publish) your own Presets to share with others on to the LM Studio Hub.
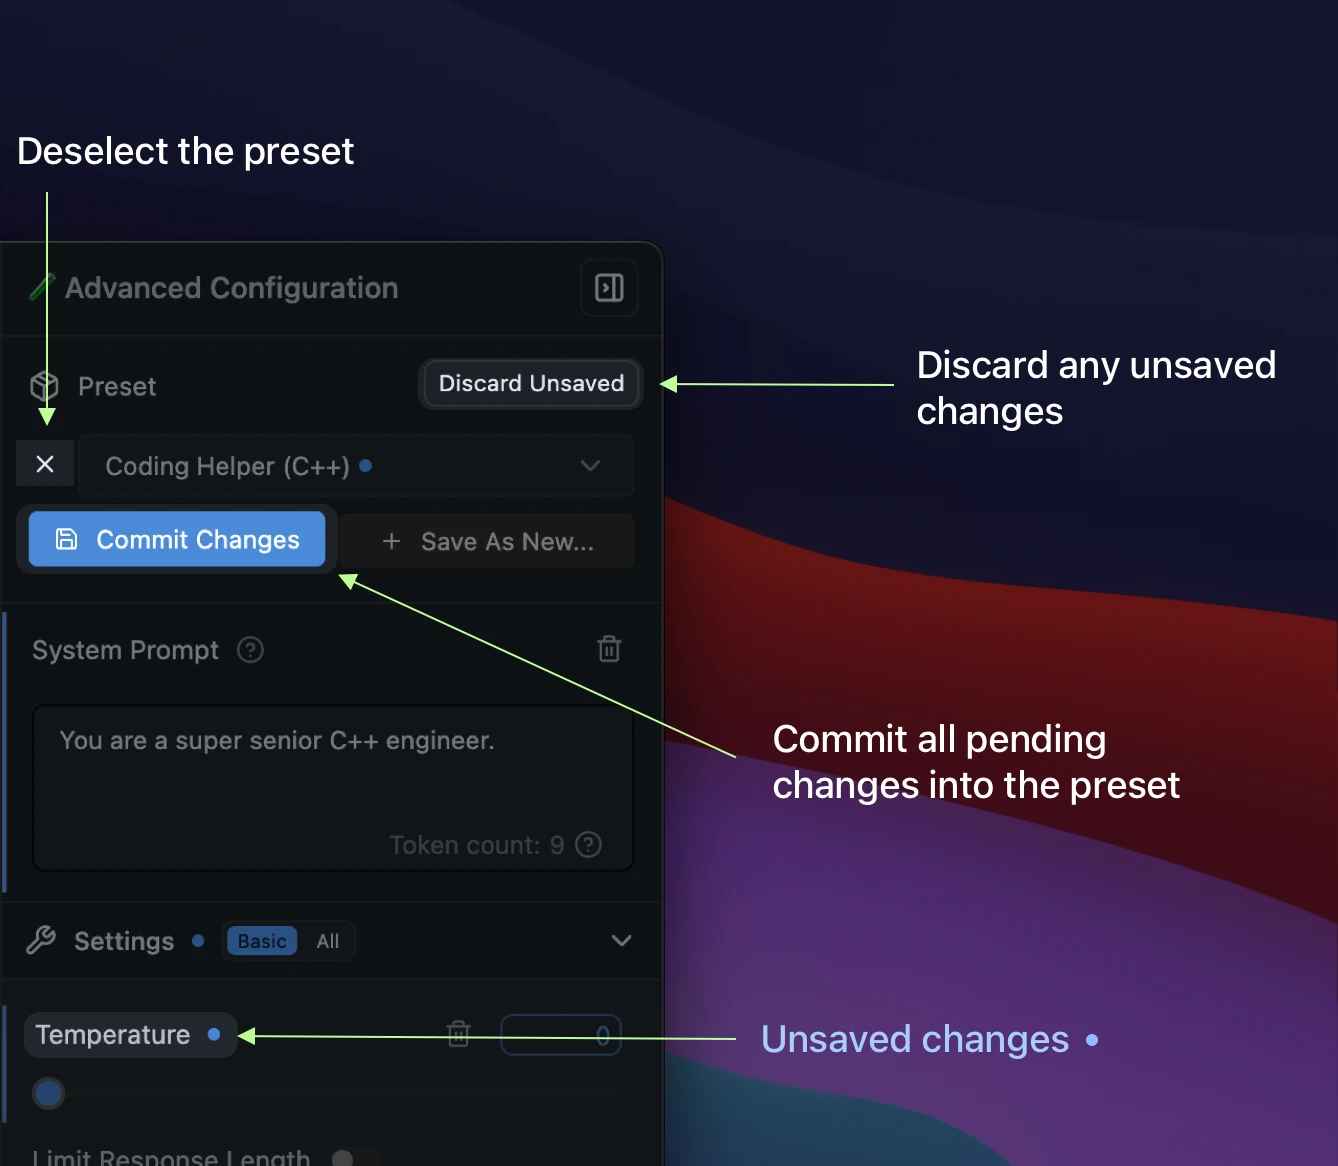
Saving, resetting, and deselecting Presets [#saving-resetting-and-deselecting-presets] Below is the anatomy of the Preset manager:
 Importing, Publishing, and Updating Downloaded Presets [#importing-publishing-and-updating-downloaded-presets]
Presets are JSON files. You can share them by sending around the JSON, or you can share them by publishing them to the LM Studio Hub.
You can also import Presets from other users by URL. See the [Import](/docs/app/presets/import) and [Publish](/docs/app/presets/publish) sections for more details.
Example: Build your own Prompt Library [#example-build-your-own-prompt-library]
You can create your own prompt library by using Presets.
In addition to system prompts, every parameter under the Advanced Configuration sidebar can be recorded in a named Preset.
For example, you might want to always use a certain Temperature, Top P, or Max Tokens for a particular use case. You can save these settings as a Preset (with or without a system prompt) and easily switch between them.
The Use Case for Presets [#the-use-case-for-presets]
* Save your system prompts, inference parameters as a named `Preset`.
* Easily switch between different use cases, such as reasoning, creative writing, multi-turn conversations, or brainstorming.
Where Presets are stored [#where-presets-are-stored]
Presets are stored in the following directory:
macOS or Linux [#macos-or-linux]
```xml
~/.lmstudio/config-presets
```
Windows [#windows]
```xml
%USERPROFILE%\.lmstudio\config-presets
```
Migration from LM Studio 0.2.* Presets [#migration-from-lm-studio-02-presets]
* Presets you've saved in LM Studio 0.2.\* are automatically readable in 0.3.3 with no migration step needed.
* If you save **new changes** in a **legacy preset**, it'll be **copied** to a new format upon save.
* The old files are NOT deleted.
* Notable difference: Load parameters are not included in the new preset format.
* Favor editing the model's default config in My Models. See [how to do it here](/docs/configuration/per-model).
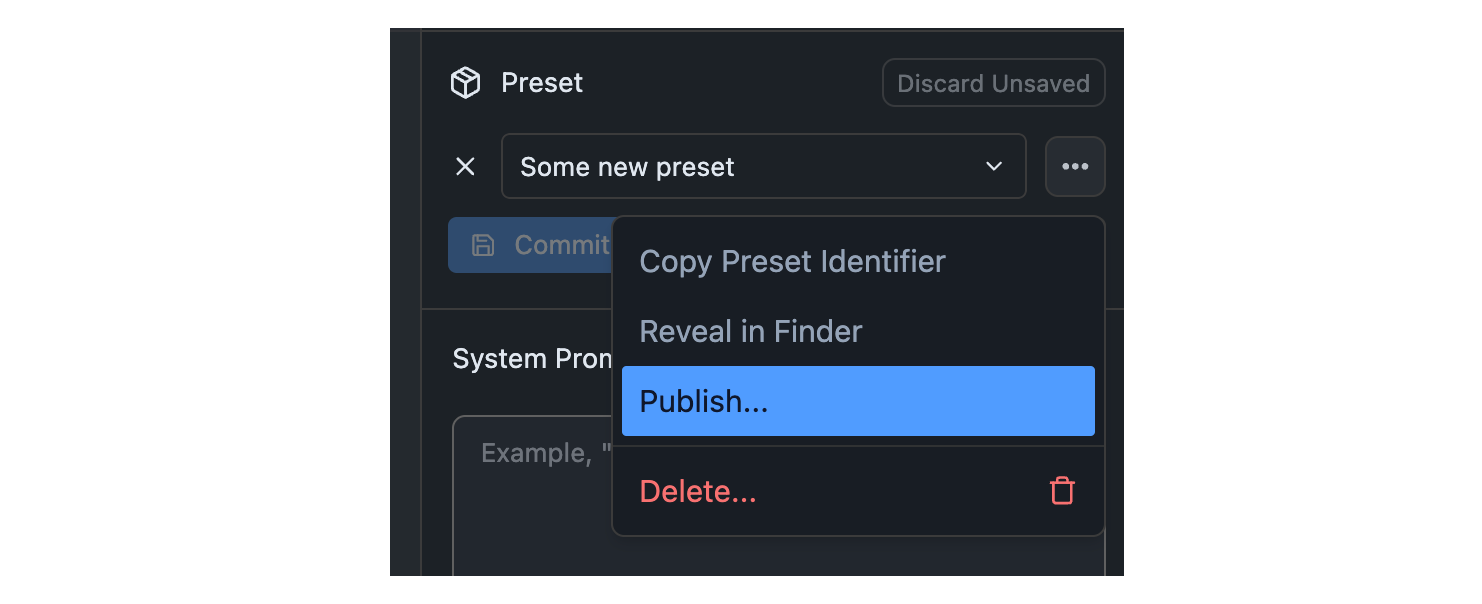
Community [#community] Chat with other LM Studio users, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). `Feature In Preview` Starting LM Studio 0.3.15, you can publish your Presets to the LM Studio community. This allows you to share your Presets with others and import Presets from other users. This feature is early and we would love to hear your feedback. Please report bugs and feedback to [bugs@lmstudio.ai](mailto:bugs@lmstudio.ai). *** Step 1: Click the Publish Button [#step-1-click-the-publish-button] Identify the Preset you want to publish in the Preset dropdown. Click the `•••` button and select "Publish" from the menu.
 Step 2: Set the Preset Details [#step-2-set-the-preset-details]
You will be prompted to set the details of your Preset. This includes the name (slug) and optional description.
Community presets are public and can be used by anyone on the internet!
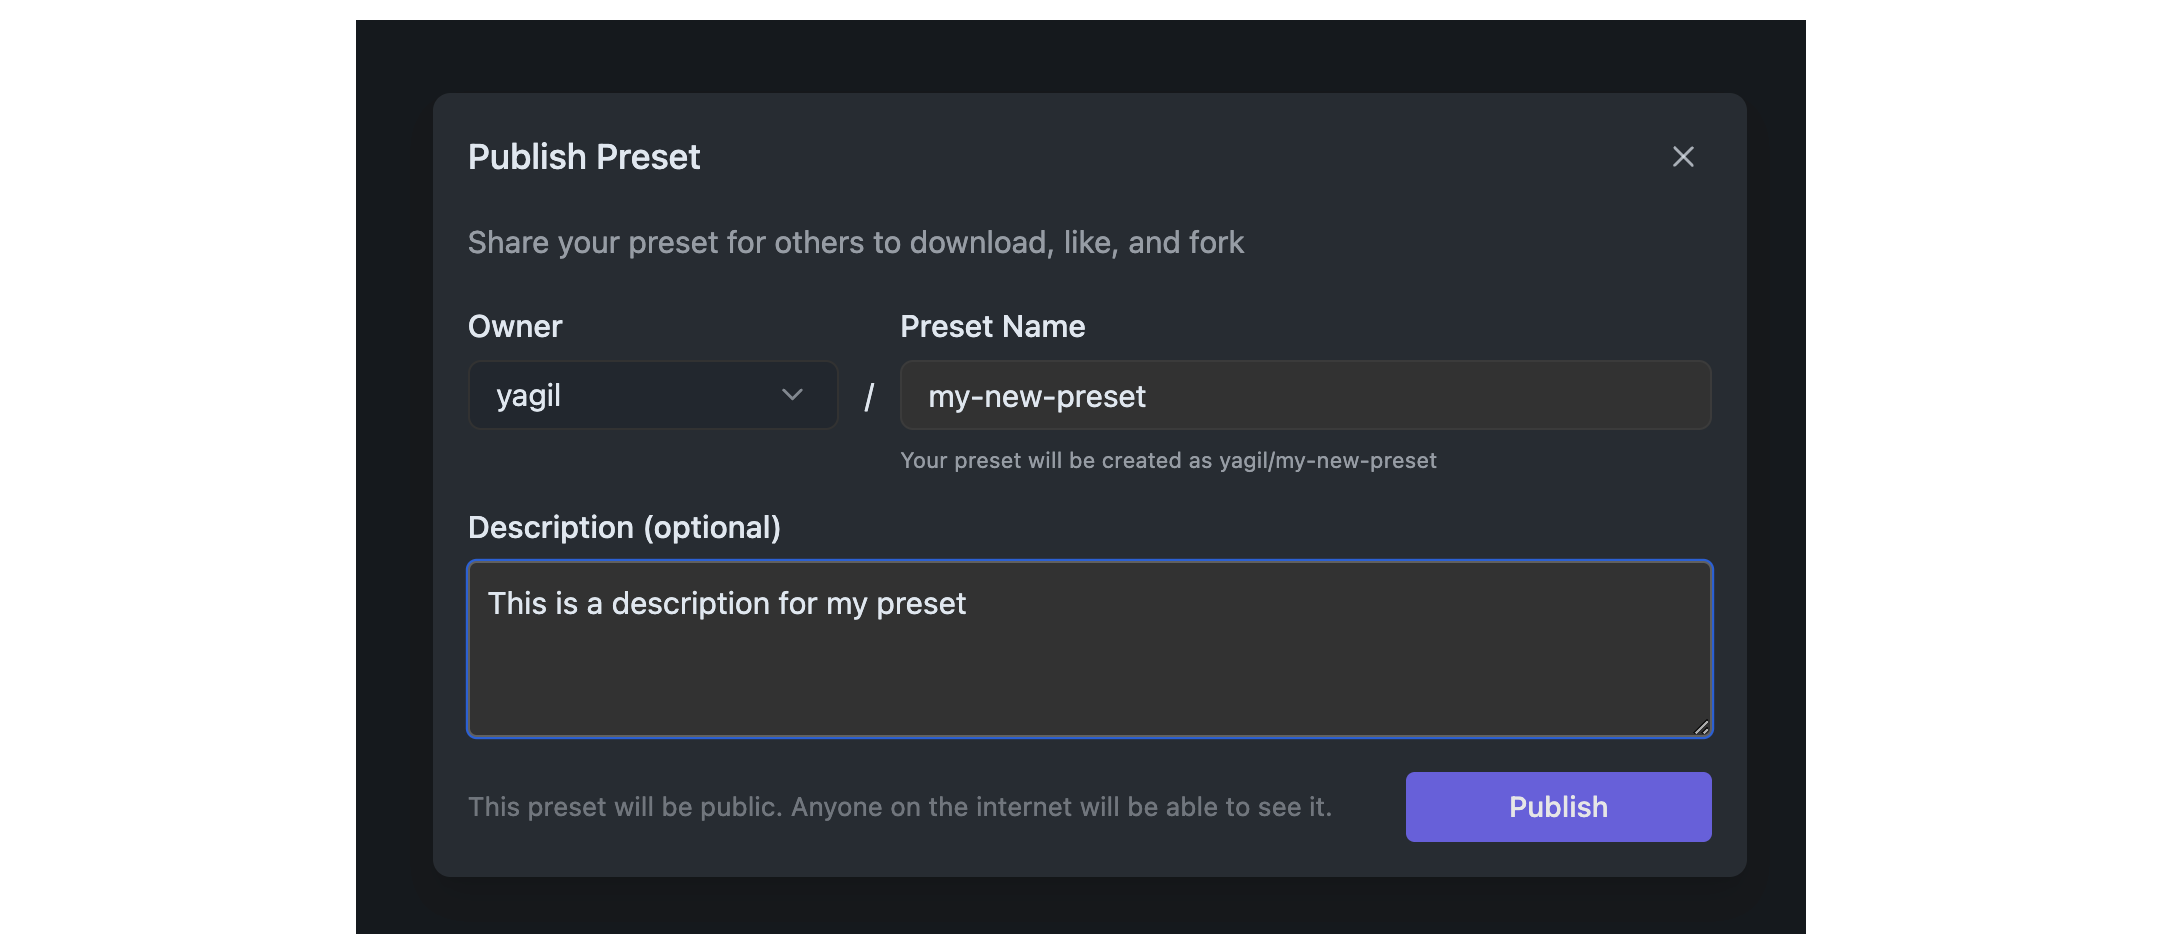 Privacy and Terms [#privacy-and-terms]
For good measure, visit the [Privacy Policy](https://lmstudio.ai/hub-privacy) and [Terms of Service](https://lmstudio.ai/hub-terms) to understand what's suitable to share on the Hub, and how data is handled. Community presets are public and visible to everyone. Make sure you agree to what these documents say before publishing your Preset.
`Feature In Preview`
You can pull the latest revisions of your Presets, or presets you have imported from others. This is useful for keeping your Presets up to date with the latest changes.
How to Pull Updates [#how-to-pull-updates] Click the `•••` button in the Preset dropdown and select "Pull" from the menu.
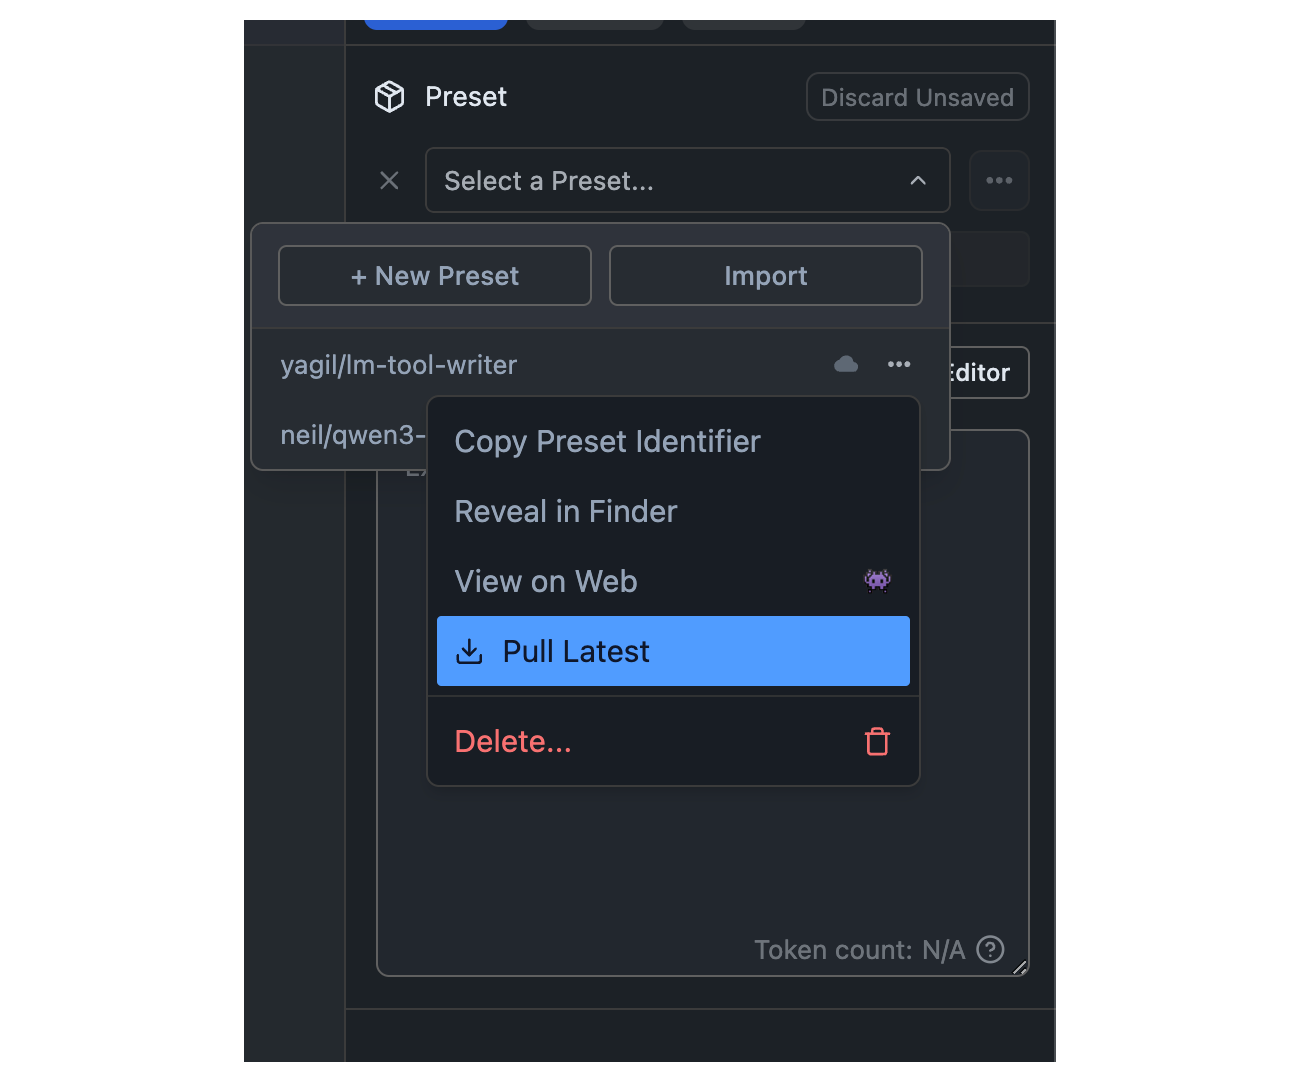 Your Presets vs Others' [#your-presets-vs-others]
Both your published Presets and other downloaded Presets can be pulled and updated the same way.
`Feature In Preview`
Starting LM Studio 0.3.15, you can publish your Presets to the LM Studio community. This allows you to share your Presets with others and import Presets from other users.
This feature is early and we would love to hear your feedback. Please report bugs and feedback to [bugs@lmstudio.ai](mailto:bugs@lmstudio.ai).
***
Published Presets [#published-presets]
Presets you share on the LM Studio Hub can be updated.
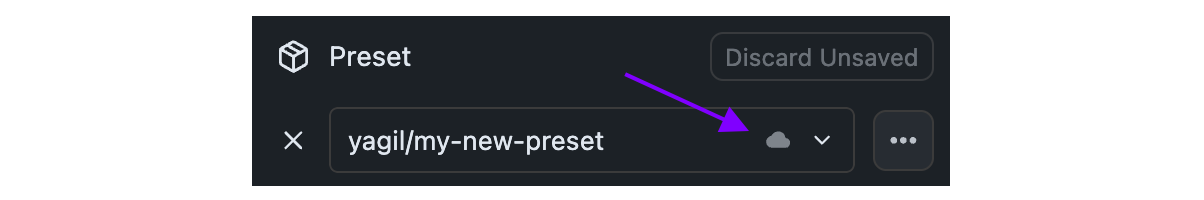
Make Changes and Commit
Make any changes to your Preset, both in parameters that are already included in the Preset, or by adding new parameters.Click the Push Button
Once changes are committed, you will see a `Push` button. Click it to push your changes to the Hub. Pushing changes will result in a new revision of your Preset on the Hub.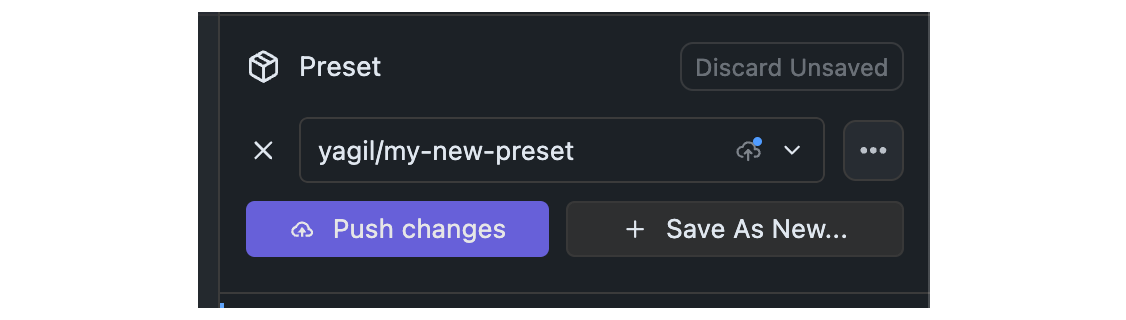
Use `lms import` (experimental) [#use-lms-import-experimental] To import a `GGUF` model you've downloaded outside of LM Studio, run the following command in your terminal: ```bash lms import
 LM Studio aims to preserves the directory structure of models downloaded from Hugging Face. The expected directory structure is as follows:
```xml
~/.lmstudio/models/
└── publisher/
└── model/
└── model-file.gguf
```
For example, if you have a model named `ocelot-v1` published by `infra-ai`, the structure would look like this:
```xml
~/.lmstudio/models/
└── infra-ai/
└── ocelot-v1/
└── ocelot-v1-instruct-q4_0.gguf
```
Community [#community] Chat with other LM Studio users, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). When loading a model, you can now set Max Concurrent Predictions to allow multiple requests to be processed in parallel, instead of queued. This is supported for LM Studio's llama.cpp engine, with MLX coming soon. Please make sure your GGUF runtime is upgraded to llama.cpp v2.0.0.
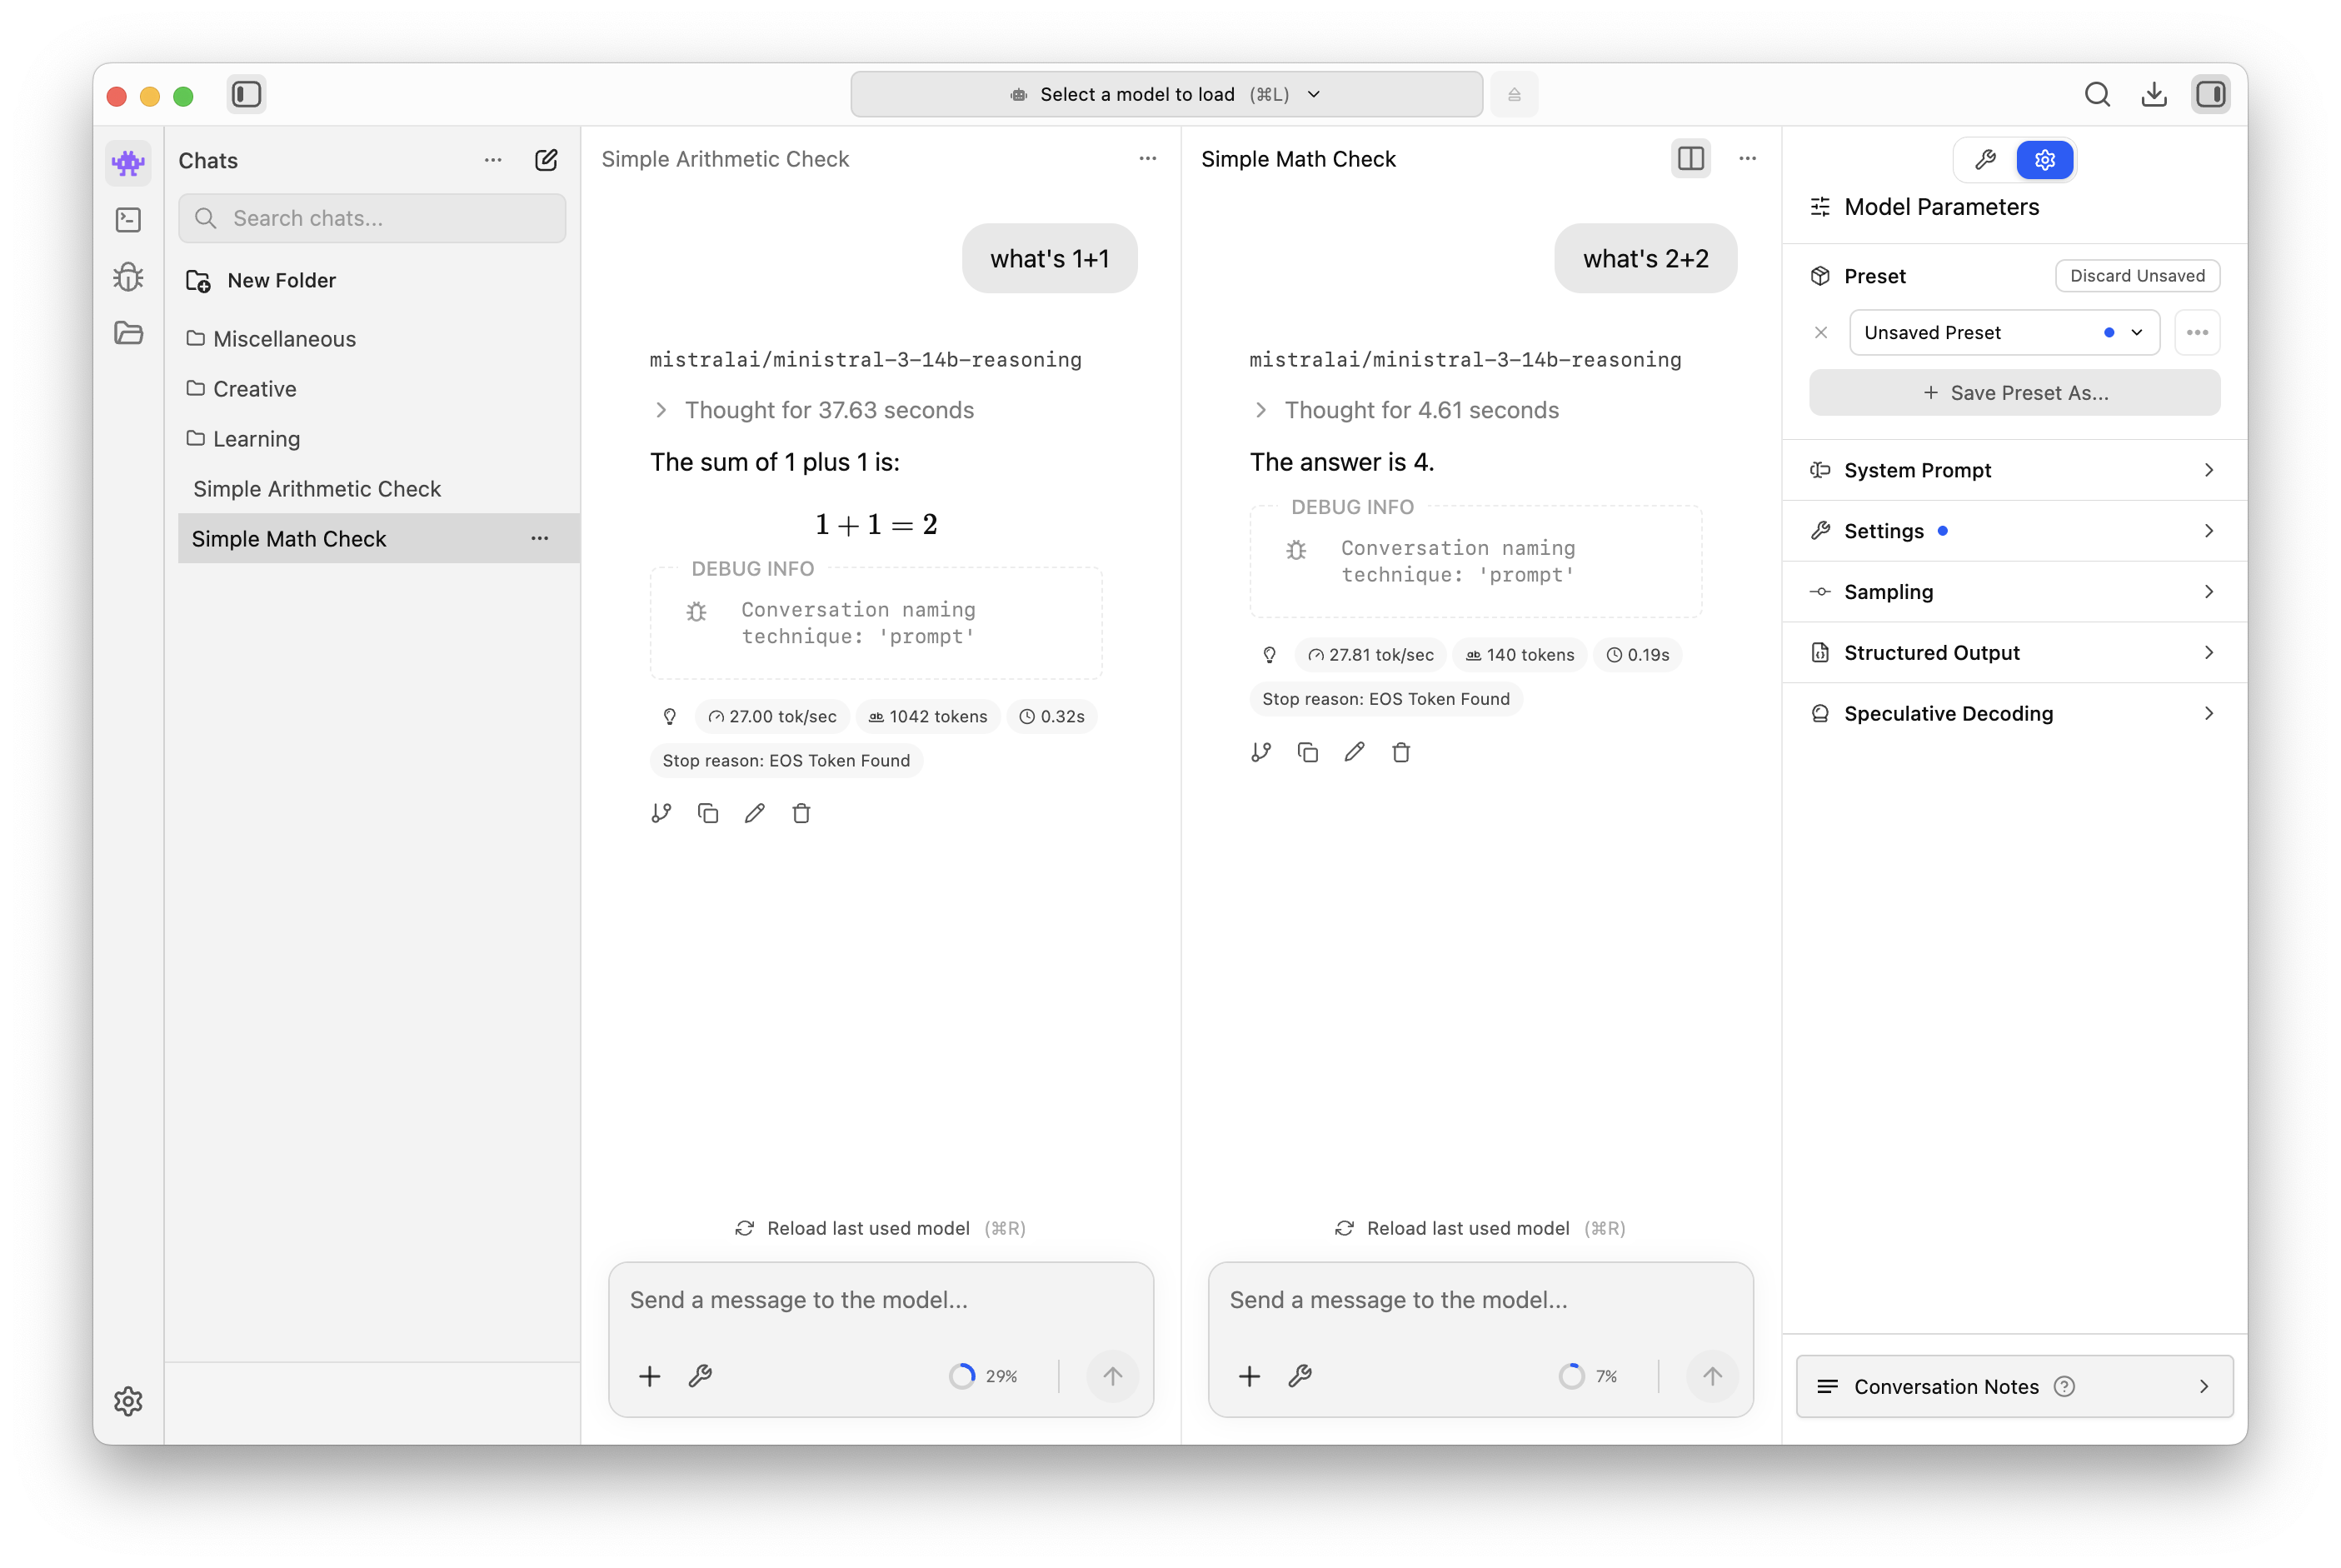
Parallel Requests via Continuous Batching [#parallel-requests-via-continuous-batching] Parallel requests via continuous batching allows the LM Studio server to dynamically combine multiple requests into a single batch. This enables concurrent workflows and results in higher throughput. Setting Max Concurrent Predictions [#setting-max-concurrent-predictions] Open the model loader and toggle on Manually choose model load parameters. Select a model to load, and toggle on Show advanced settings to set Max Concurrent Predictions. By default, Max Concurrent Predictions is set to 4. Sending parallel requests to chats in Split View [#sending-parallel-requests-to-chats-in-split-view] Use the [split view in chat feature](/docs/basics/chat) to send two requests simultaneously to two chats and view them side by side.
 `Advanced`
You can set default load settings for each model in LM Studio.
When the model is loaded anywhere in the app (including through [`lms load`](/docs/cli#load-a-model-with-options)) these settings will be used.
Setting default parameters for a model [#setting-default-parameters-for-a-model] Head to the My Models tab and click on the gear ⚙️ icon to edit the model's default parameters.
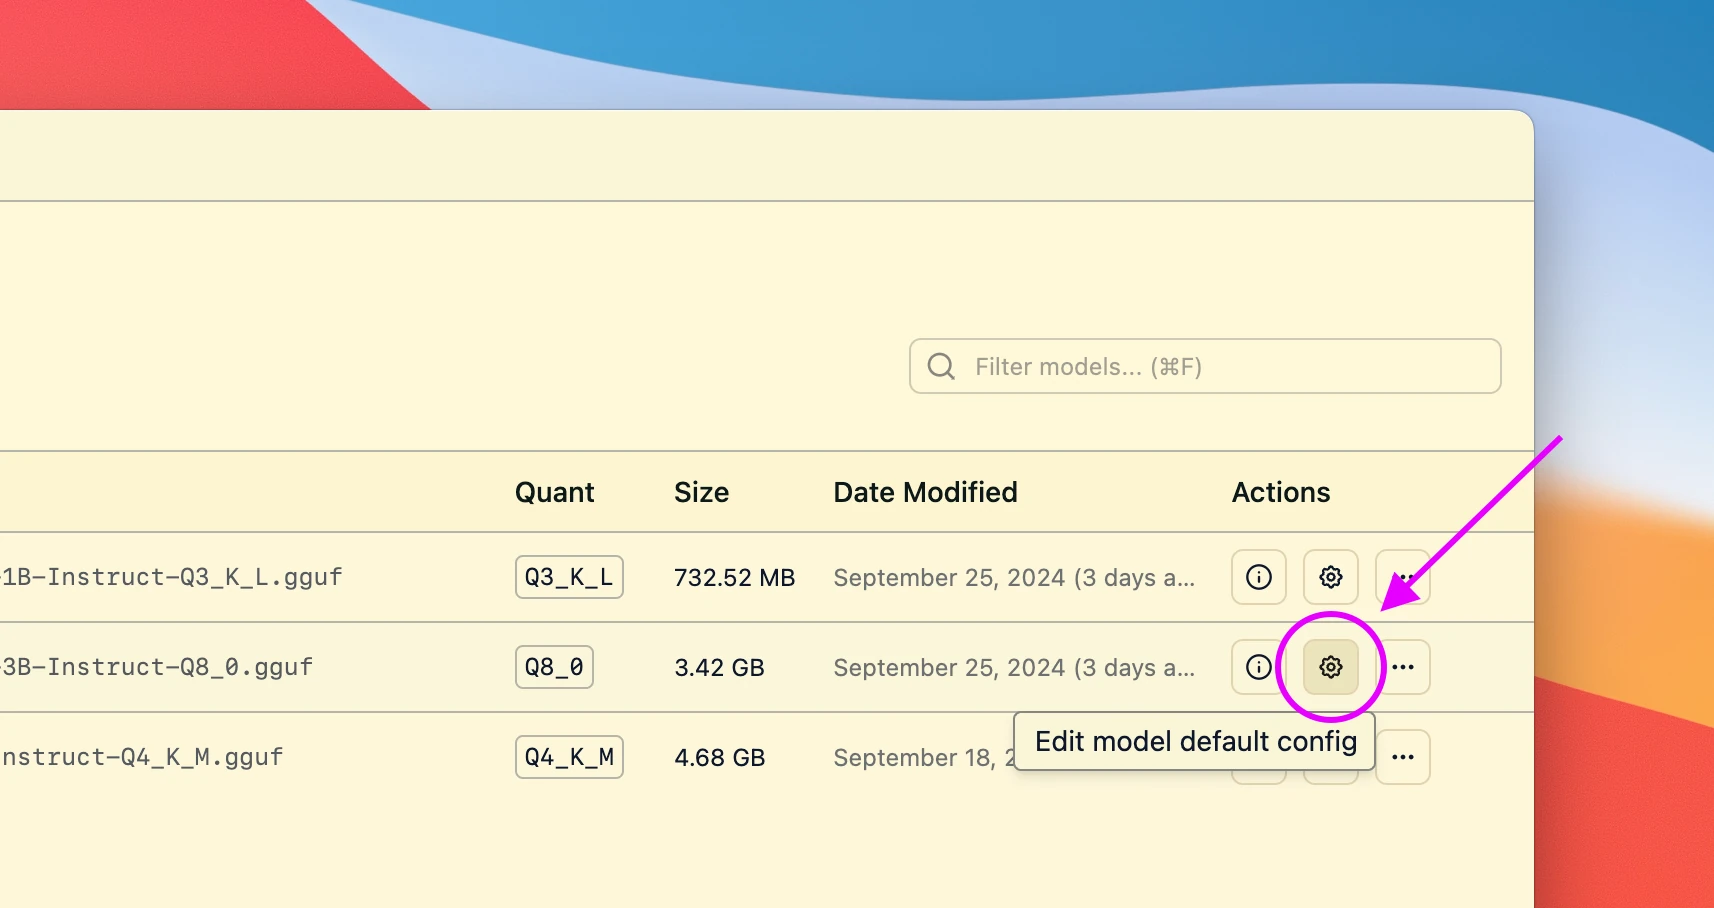 This will open a dialog where you can set the default parameters for the model.
Next time you load the model, these settings will be used.
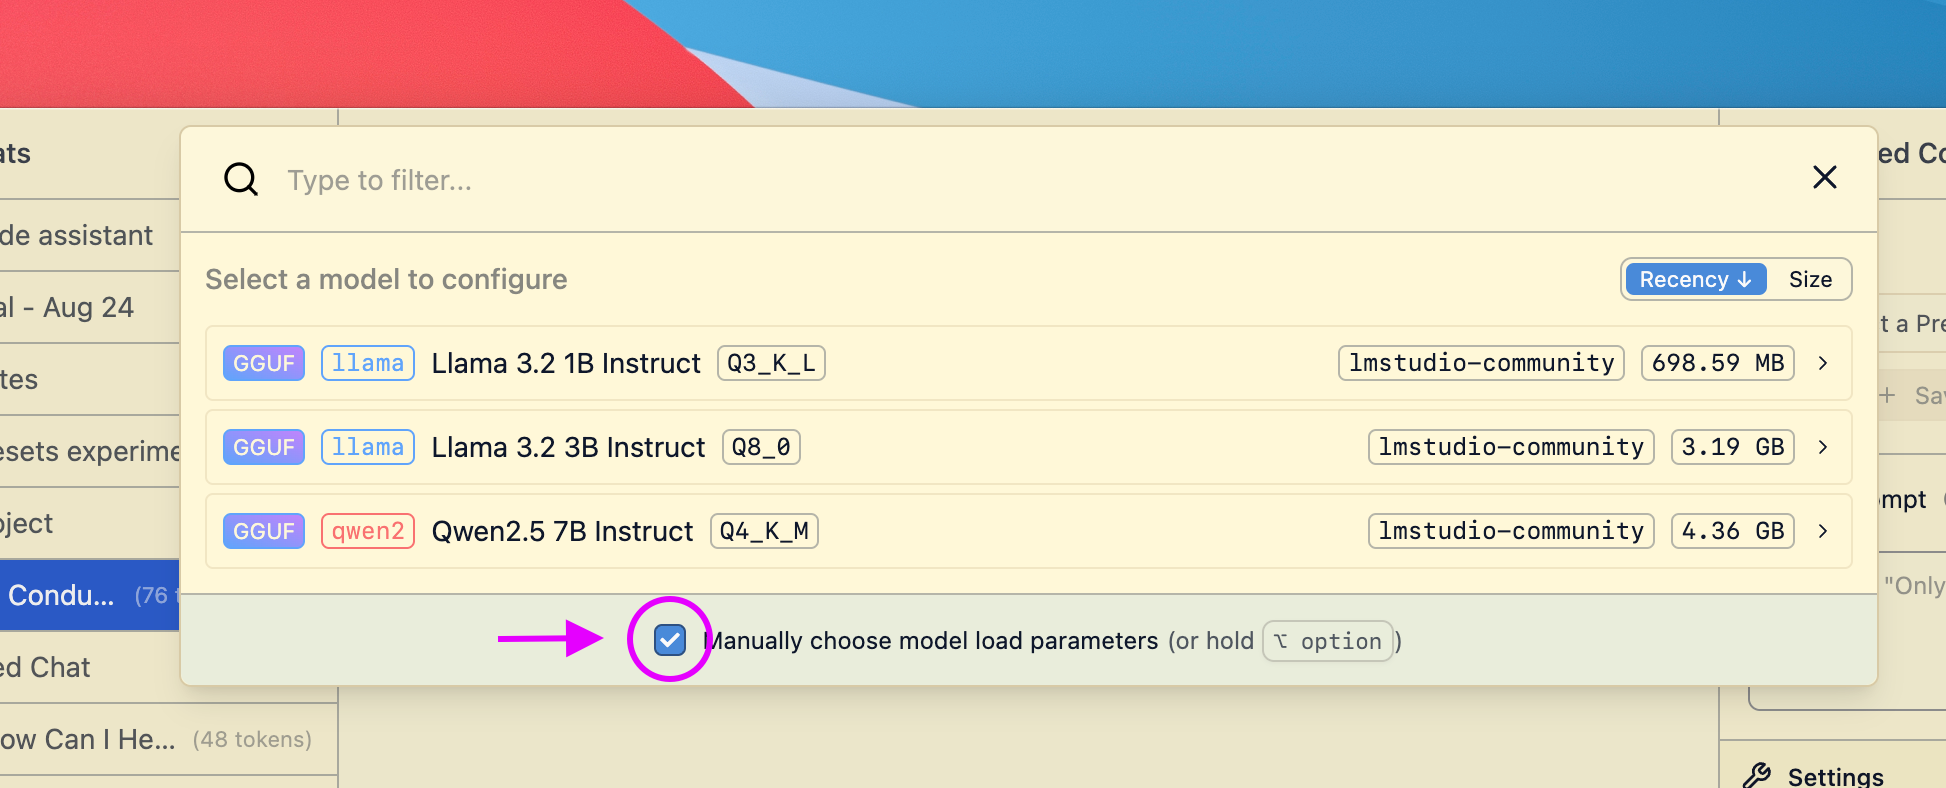 Saving your changes as the default settings for a model [#saving-your-changes-as-the-default-settings-for-a-model]
If you make changes to load settings when you load a model, you can save them as the default settings for that model.
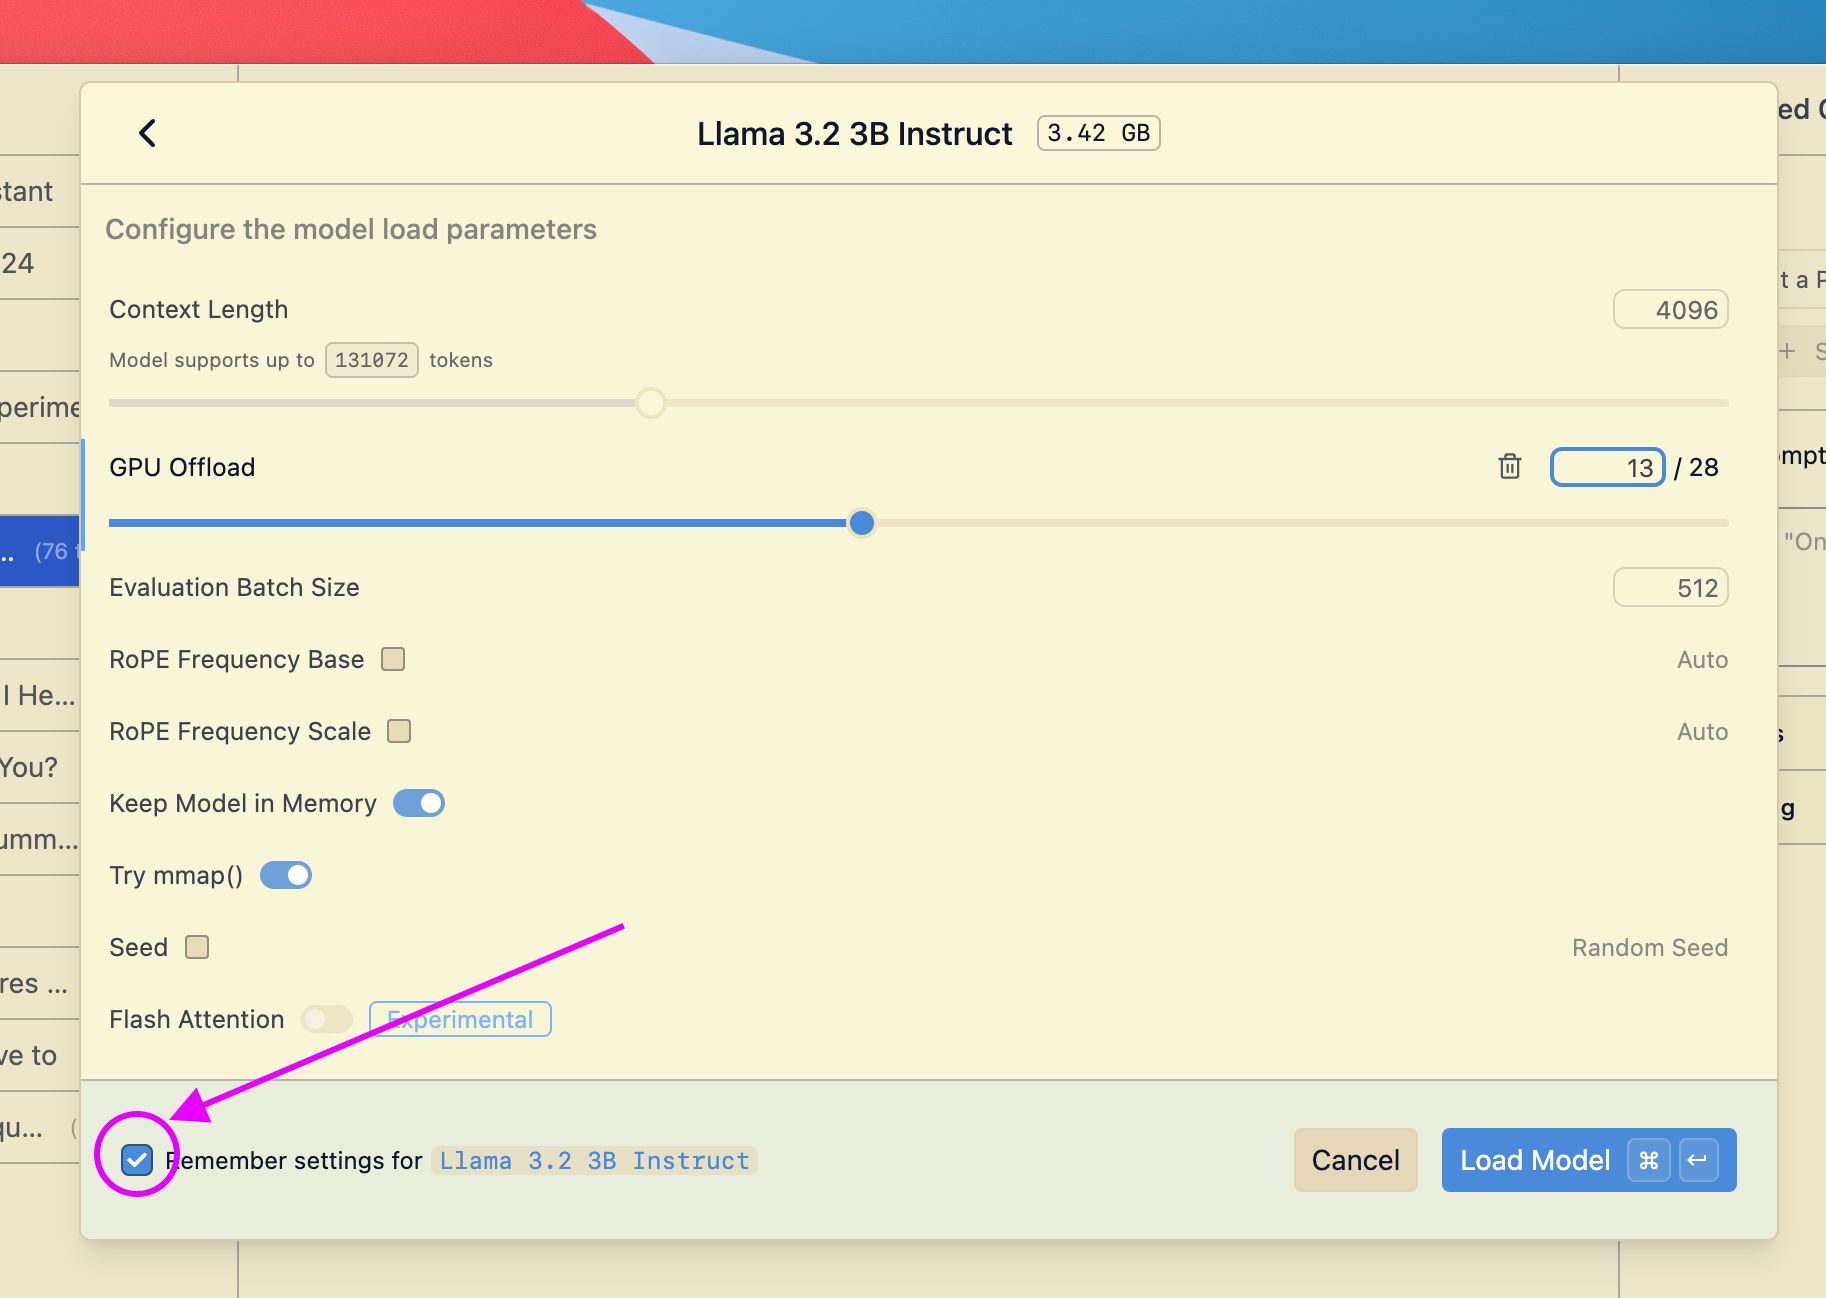
Community [#community] Chat with other LM Studio power users, discuss configs, models, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). `Advanced` By default, LM Studio will automatically configure the prompt template based on the model file's metadata. However, you can customize the prompt template for any model.
Overriding the Prompt Template for a Specific Model [#overriding-the-prompt-template-for-a-specific-model] Head over to the My Models tab and click on the gear ⚙️ icon to edit the model's default parameters. Pro tip: you can jump to the My Models tab from anywhere by pressing `⌘` + `3` on Mac, or `ctrl` + `3` on Windows / Linux. [#pro-tip-you-can-jump-to-the-my-models-tab-from-anywhere-by-pressing---3-on-mac-or-ctrl--3-on-windows--linux] Customize the Prompt Template [#customize-the-prompt-template] 💡 In most cases you don't need to change the prompt template [#-in-most-cases-you-dont-need-to-change-the-prompt-template] When a model doesn't come with a prompt template information, LM Studio will surface the `Prompt Template` config box in the **🧪 Advanced Configuration** sidebar.
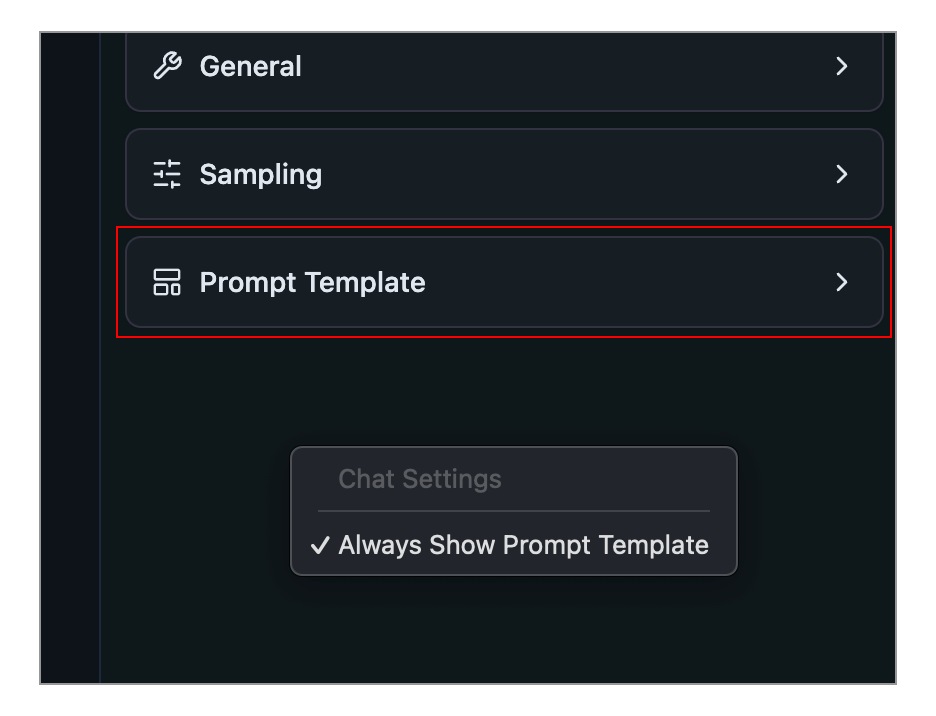 You can make this config box always show up by right clicking the sidebar and selecting **Always Show Prompt Template**.
Prompt template options [#prompt-template-options]
Jinja Template [#jinja-template]
You can express the prompt template in Jinja.
Jinja is a templating engine used to encode the prompt template in several popular LLM model file formats. [#jinja-is-a-templating-engine-used-to-encode-the-prompt-template-in-several-popular-llm-model-file-formats]
Manual [#manual]
You can also express the prompt template manually by specifying message role prefixes and suffixes.
Reasons you might want to edit the prompt template: [#reasons-you-might-want-to-edit-the-prompt-template] 1. The model's metadata is incorrect, incomplete, or LM Studio doesn't recognize it 2. The model does not have a prompt template in its metadata (e.g. custom or older models) 3. You want to customize the prompt template for a specific use case `Advanced` Speculative decoding is a technique that can substantially increase the generation speed of large language models (LLMs) without reducing response quality.
What is Speculative Decoding [#what-is-speculative-decoding] Speculative decoding relies on the collaboration of two models: * A larger, "main" model * A smaller, faster "draft" model During generation, the draft model rapidly proposes potential tokens (subwords), which the main model can verify faster than it would take it to generate them from scratch. To maintain quality, the main model only accepts tokens that match what it would have generated. After the last accepted draft token, the main model always generates one additional token. For a model to be used as a draft model, it must have the same "vocabulary" as the main model. How to enable Speculative Decoding [#how-to-enable-speculative-decoding] On `Power User` mode or higher, load a model, then select a `Draft Model` within the `Speculative Decoding` section of the chat sidebar:
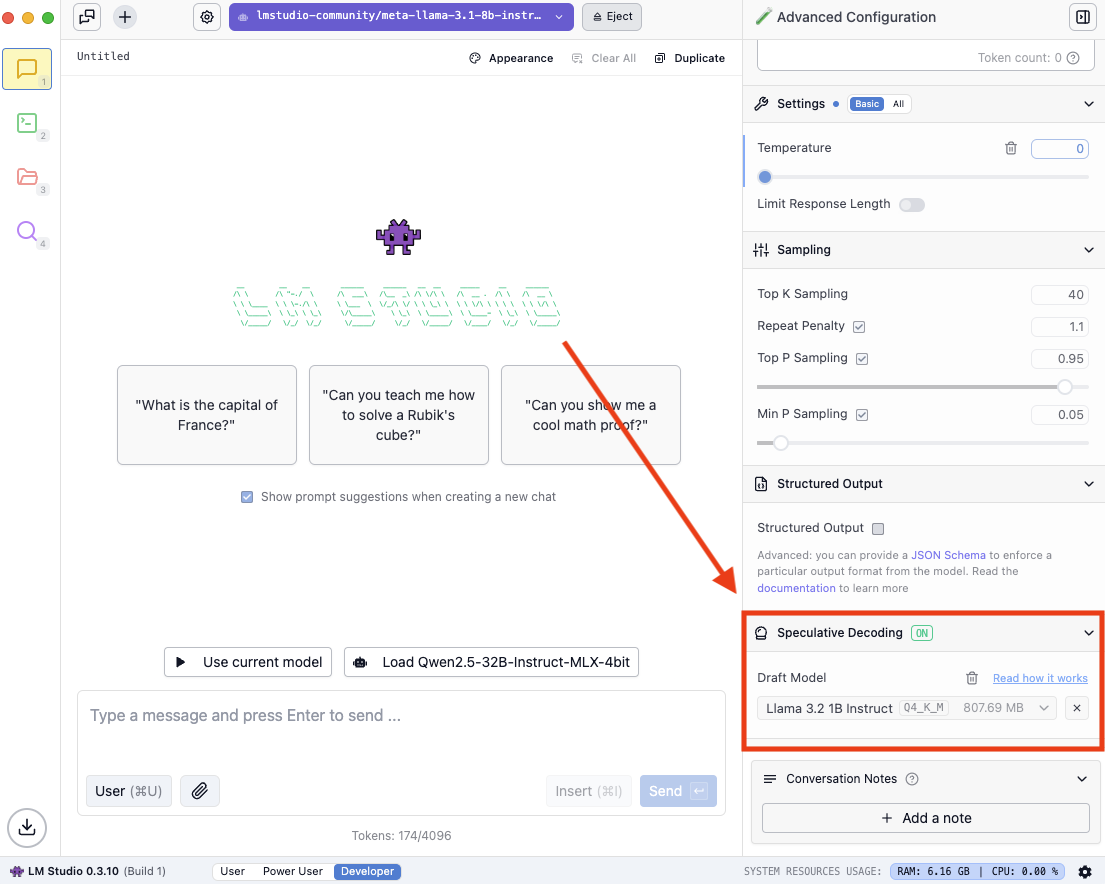 Finding compatible draft models [#finding-compatible-draft-models]
You might see the following when you open the dropdown:
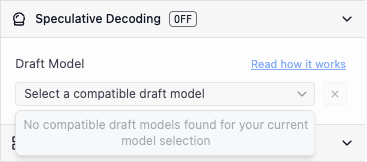 Try to download a lower parameter variant of the model you have loaded, if it exists. If no smaller versions of your model exist, find a pairing that does.
For example:
Selecting a Language [#selecting-a-language] You can choose a language in the Settings tab. Use the dropdown menu under Preferences > Language.
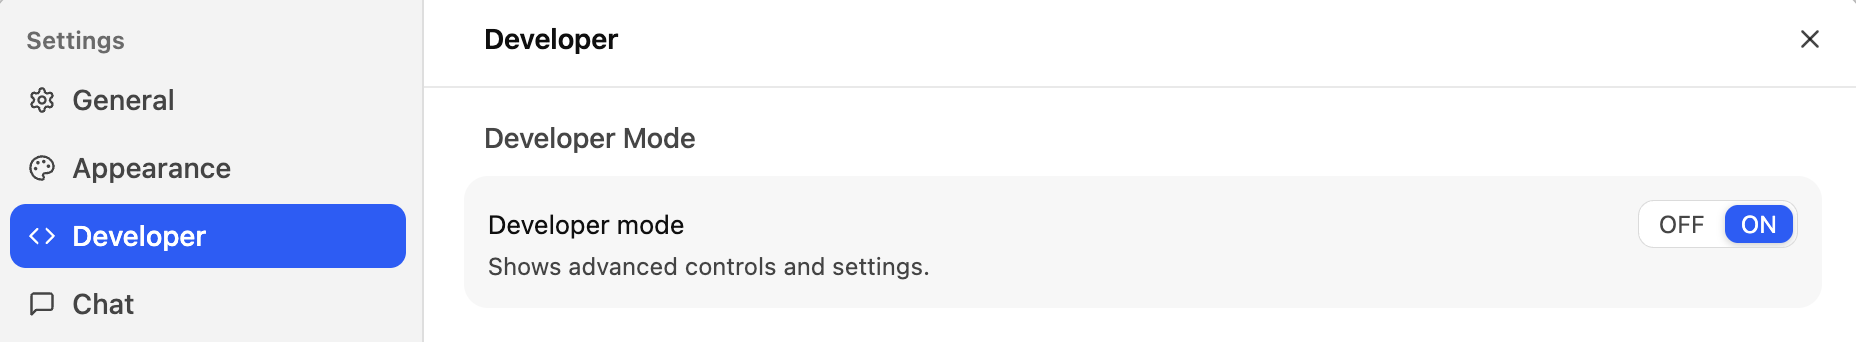
Big thank you to community localizers 🙏 [#big-thank-you-to-community-localizers-] * Spanish [@xtianpaiva](https://github.com/xtianpaiva), [@AlexisGross](https://github.com/AlexisGross), [@Tonband](https://github.com/Tonband) * Norwegian [@Exlo84](https://github.com/Exlo84) * German [@marcelMaier](https://github.com/marcelMaier), [@Goekdeniz-Guelmez](https://github.com/Goekdeniz-Guelmez) * Romanian (ro) [@alexandrughinea](https://github.com/alexandrughinea) * Turkish (tr) [@progesor](https://github.com/progesor), [@nossbar](https://github.com/nossbar) * Russian [@shelomitsky](https://github.com/shelomitsky), [@mlatysh](https://github.com/mlatysh), [@Adjacentai](https://github.com/Adjacentai), [@HostFly](https://github.com/HostFly), [@MotyaDev](https://github.com/MotyaDev), [@Autumn-Whisper](https://github.com/Autumn-Whisper), [@seropheem](https://github.com/seropheem) * Korean [@williamjeong2](https://github.com/williamjeong2) * Polish [@danieltechdev](https://github.com/danieltechdev) * Czech [@ladislavsulc](https://github.com/ladislavsulc) * Vietnamese [@trinhvanminh](https://github.com/trinhvanminh), [@godkyo98](https://github.com/godkyo98) * Portuguese (BR) [@Sm1g00l](https://github.com/Sm1g00l), [@altiereslima](https://github.com/altiereslima) * Portuguese (PT) [@catarino](https://github.com/catarino) * Chinese (zh-CN) [@neotan](https://github.com/neotan), [@SweetDream0256](https://github.com/SweetDream0256), [@enKl03B](https://github.com/enKl03B), [@evansrrr](https://github.com/evansrrr), [@xkonglong](https://github.com/xkonglong), [@shadow01a](https://github.com/shadow01a) * Chinese (zh-HK), (zh-TW) [@neotan](https://github.com/neotan), [ceshizhuanyong895](https://github.com/ceshizhuanyong895), [@BrassaiKao](https://github.com/BrassaiKao) * Chinese (zh-Hant) [@kywarai](https://github.com/kywarai), [ceshizhuanyong895](https://github.com/ceshizhuanyong895) * Ukrainian (uk) [@hmelenok](https://github.com/hmelenok) * Japanese (ja) [@digitalsp](https://github.com/digitalsp) * Dutch (nl) [@alaaf11](https://github.com/alaaf11) * Italian (it) [@fralapo](https://github.com/fralapo), [@Bl4ck-D0g](https://github.com/Bl4ck-D0g), [@nikypalma](https://github.com/nikypalma) * Indonesian (id) [@dwirx](https://github.com/dwirx) * Greek (gr) [@ilikecatgirls](https://github.com/ilikecatgirls) * Swedish (sv) [@reinew](https://github.com/reinew) * Catalan (ca) [@Gopro3010](https://github.com/Gopro3010) * French [@Plexi09](https://github.com/Plexi09) * Finnish (fi) [@divergentti](https://github.com/divergentti) * Bengali (bn) [@AbiruzzamanMolla](https://github.com/AbiruzzamanMolla) * Malayalam (ml) [@prasanthc41m](https://github.com/prasanthc41m) * Thai (th) [@gnoparus](https://github.com/gnoparus) * Bosnian (bs) [@0haris0](https://github.com/0haris0) * Bulgarian (bg) [@DenisZekiria](https://github.com/DenisZekiria) * Hindi (hi) [@suhailtajshaik](https://github.com/suhailtajshaik) * Hungarian (hu) [@Mekemoka](https://github.com/Mekemoka) * Persian (Farsi) (fa) [@mohammad007kh](https://github.com/mohammad007kh), [@darwindev](https://github.com/darwindev) * Arabic (ar) [@haqbany](https://github.com/haqbany) Still under development (due to lack of RTL support in LM Studio) * Hebrew: [@NHLOCAL](https://github.com/NHLOCAL) Contributing to LM Studio localization [#contributing-to-lm-studio-localization] If you want to improve existing translations or contribute new ones, you're more than welcome to jump in. LM Studio strings are maintained in [https://github.com/lmstudio-ai/localization](https://github.com/lmstudio-ai/localization). See instructions for contributing [here](https://github.com/lmstudio-ai/localization/blob/main/README.md). Enable Developer Mode [#enable-developer-mode] Developer Mode combines the previous Developer and Power User modes into a single mode with all advanced features enabled. You can enable Developer mode in Settings > Developer.
 Which mode should I choose? [#which-mode-should-i-choose]
`User` [#user]
Show only the chat interface, and auto-configure everything. This is the best choice for beginners or anyone who's happy with the default settings.
`Developer` [#developer]
Full access to all aspects in LM Studio. This includes keyboard shortcuts and development features.
Use LM Studio in this mode if you want access to configurable [load](/docs/configuration/load) and [inference](/docs/configuration/inference) parameters as well as advanced chat features such as [insert, edit, & continue](/docs/advanced/context) (for either role, user or assistant).
Selecting a Theme [#selecting-a-theme]
Press `Cmd` + `K` then `T` (macOS) or `Ctrl` + `K` then `T` (Windows/Linux) to open the theme selector.
You can also choose a theme in the Settings tab (`Cmd` + `,` on macOS or `Ctrl` + `,` on Windows/Linux).
Choosing the "Auto" option will automatically switch between Light and Dark themes based on your system settings.
 Meet LM Studio Bionic, the next generation of LM Studio designed for agentic work with open models.
Bionic is the AI agent for getting real work done with open models, including coding, research, and complex work with documents and files. You can use local models or switch to open-source models in the cloud for heavier tasks, all while staying in control of your privacy and AI spend.
What you can do [#what-you-can-do]
Bionic is an excellent agentic harness, especially for coding and working with documents.
Within a project, create separate sessions for separate tasks. Run multiple sessions across projects to parallelize your workflows.
Choose where a model runs [#choose-where-a-model-runs]
A Bionic session can use:
* **Frontier open models** running in LM Studio Secure Cloud with Zero Data Retention.
* **Local** models running on your computer.
* **Remote** models from another device through LM Link.
How this differs from LM Studio [#how-this-differs-from-lm-studio]
Bionic is a new, separate app from LM Studio. For advanced low-level configuration, you can continue to use LM Studio alongside Bionic.
Download Bionic and [create your first project](/docs/bionic/quick-start) to get started!
LM Studio Bionic organizes work into Projects and Sessions.
Projects [#projects]
A project keeps related sessions and files together, giving the agent a shared working context.
For example:
* For coding work, point a project to a local directory. Then create separate sessions within that project for different tasks while sharing the same codebase.
* For a long-running research initiative, add relevant templates and source files up front, then continue adding documents as you go. Start separate sessions within the project to explore different questions or workstreams, while keeping every session grounded in the same shared document set.
Sessions [#sessions]
A session is a conversation and task thread inside a project. Use separate sessions for work that should have separate instructions or conversation history.
You can **Pin**, **Rename**, **Archive**, or **Delete** a session. An icon appears next to a session when Bionic has finished working in the background.
Tabs and side-by-side work [#tabs-and-side-by-side-work]
Sessions open in tabs. Project files and built-in browser pages can also open as tabs.
To view two sessions side by side, drag a session tab over the left or right half of the current pane. This can be useful for comparing results or keeping one task visible while another runs.
You can also use **Fork** on an eligible response to open a new branch beside the current session.
Background sessions [#background-sessions]
Switching to another tab or project does not stop a running session. Bionic continues the task in the background.
Next, [create your first project](/docs/bionic/quick-start).
A project keeps related sessions and files together. Create one project for work that should share the same goal, source files, or codebase.
Create a project [#create-a-project]
1. Create a new Project and give it a name.
2. If you want Bionic to work with a local codebase, toggle on **Allow coding**.
3. If coding is enabled, select **Choose a folder for Bionic to work in** and choose the root folder of your codebase.
4. Click **Create**.
5. In the new session, select a model if Bionic has not already chosen the **Root model**.
6. Tell the agent what you'd like to do.
Work with documents and files [#work-with-documents-and-files]
Attach or drag in files and folders to add source material. Files Bionic creates appear in the right sidebar under **Project Files**. Project Files are shared across all sessions in the same project.
For example:
> Research the options in these notes, summarize the tradeoffs, and save a recommendation as `recommendation.md`.
Learn more in [Working with Documents](/docs/bionic/agent/work-project).
Work with a codebase [#work-with-a-codebase]
When **Allow coding** is enabled, Bionic can search the repository, edit files, use Git, and run shell commands in the selected working directory.
For example:
> Find where request timeouts are handled. Explain the current behavior, fix the failing edge case, and run the relevant tests.
Review Bionic's diffs and command output before keeping the changes.
Learn more in [Coding](/docs/bionic/agent/code-project).
Keep tasks focused [#keep-tasks-focused]
Give Bionic a clear goal, relevant files, and a concrete output. For larger work, ask it to investigate first, then implement in the same session.
See [Projects and Sessions](/docs/bionic/projects-and-sessions) to organize more work.
Bionic uses credits when a session runs a **Cloud** model. The amount depends on the selected model and the tokens processed.
**Credits are only consumed when you select and use cloud models.** Local models and remote LM Link models do not consume credits and do not require billing set up.
View usage [#view-usage]
Open **Settings** → **Billing and Usage**.
The data reflects how many credits you have consumed from the selected account over the last 30 days.
Select **Refresh** to load the latest account and usage information.
Bionic shows usage totals, not a fixed cost per task. Model pricing and request size affect the final spend.
To change a plan or add credits, see [Set Up Billing and Add Credits](/docs/bionic/accounts-plans-and-billing).
Cloud models require an LM Studio account with available credits. Local and LM Link models do not use Bionic cloud credits, and can be used without an LM Studio account.
Sign in [#sign-in]
1. Open **Settings**.
2. Under **General**, find **Account**.
3. Select **Sign in** and finish signing in through your browser.
4. Return to Bionic.
Add credits for personal use [#add-credits-for-personal-use]
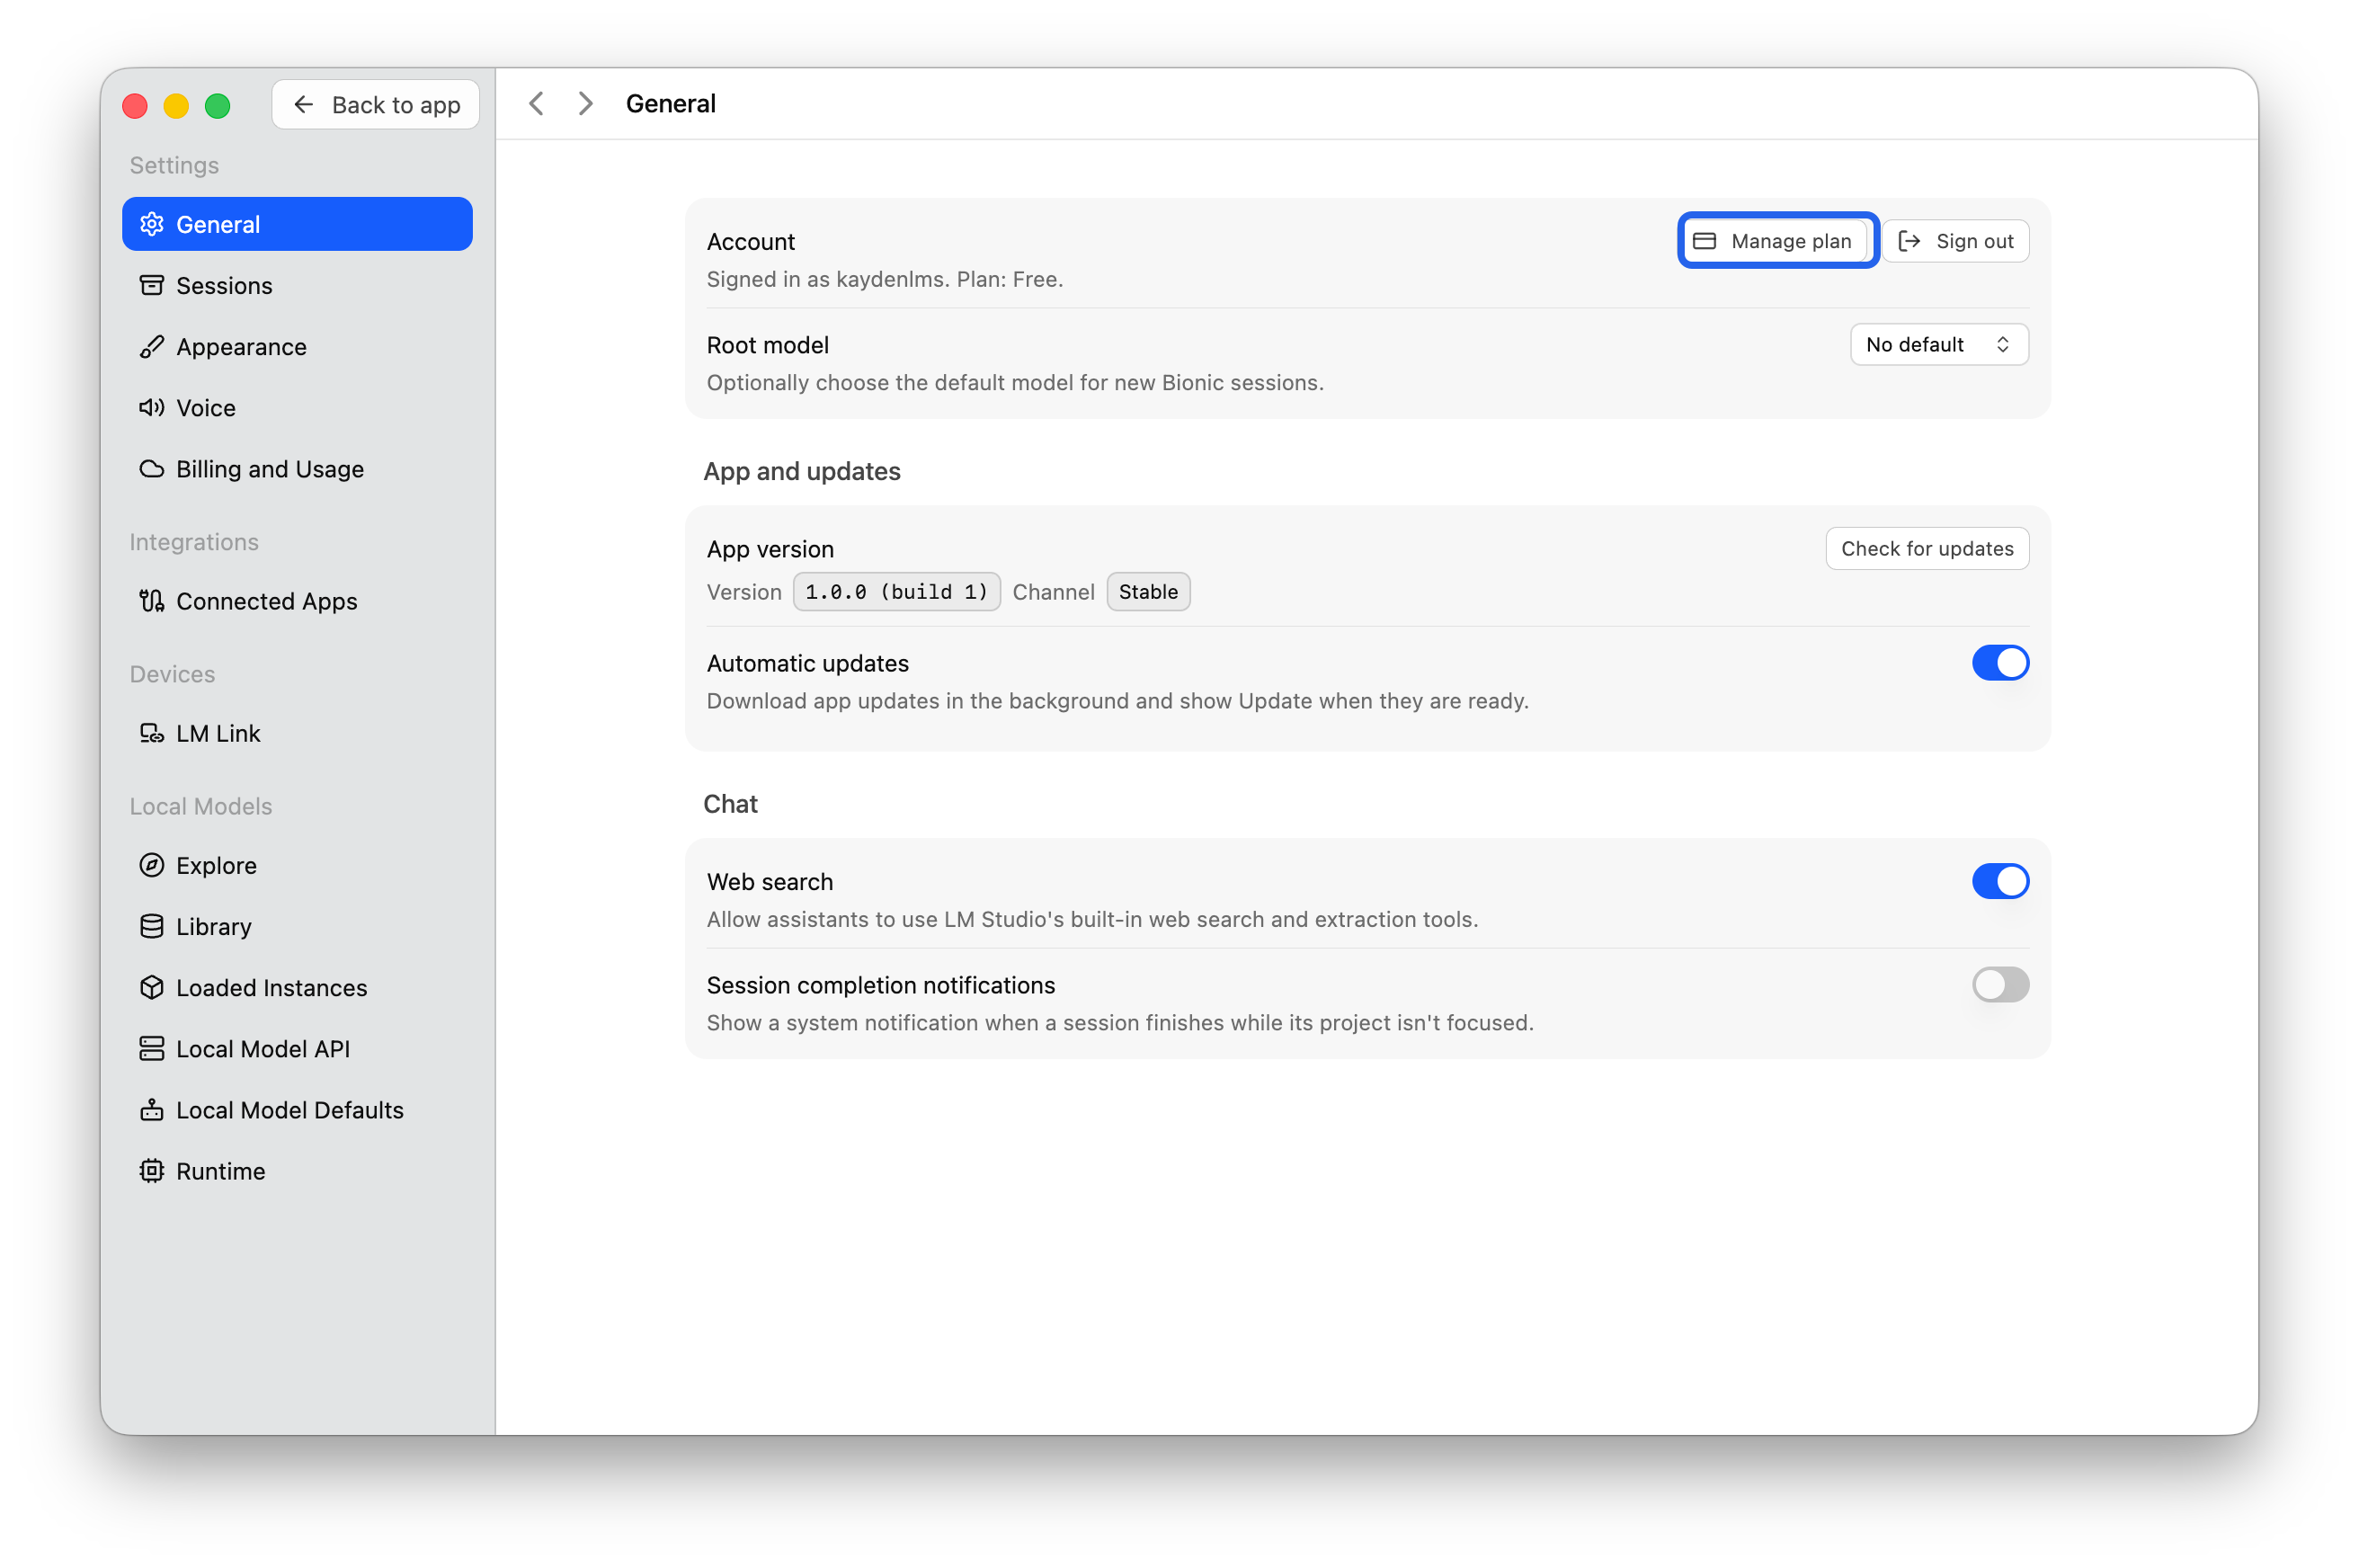 1. In **Settings** under **Account**, select **Manage plan**.
2. You'll be redirected to your account on the LM Studio Hub. Navigate to **Cloud Inference** under Features to add more credits to your account.
3. Complete checkout and ensure the new amount is reflected under **Available Balance**.
4. Return to Bionic and open **Billing and Usage**. Refresh to ensure the new balance is reflected.
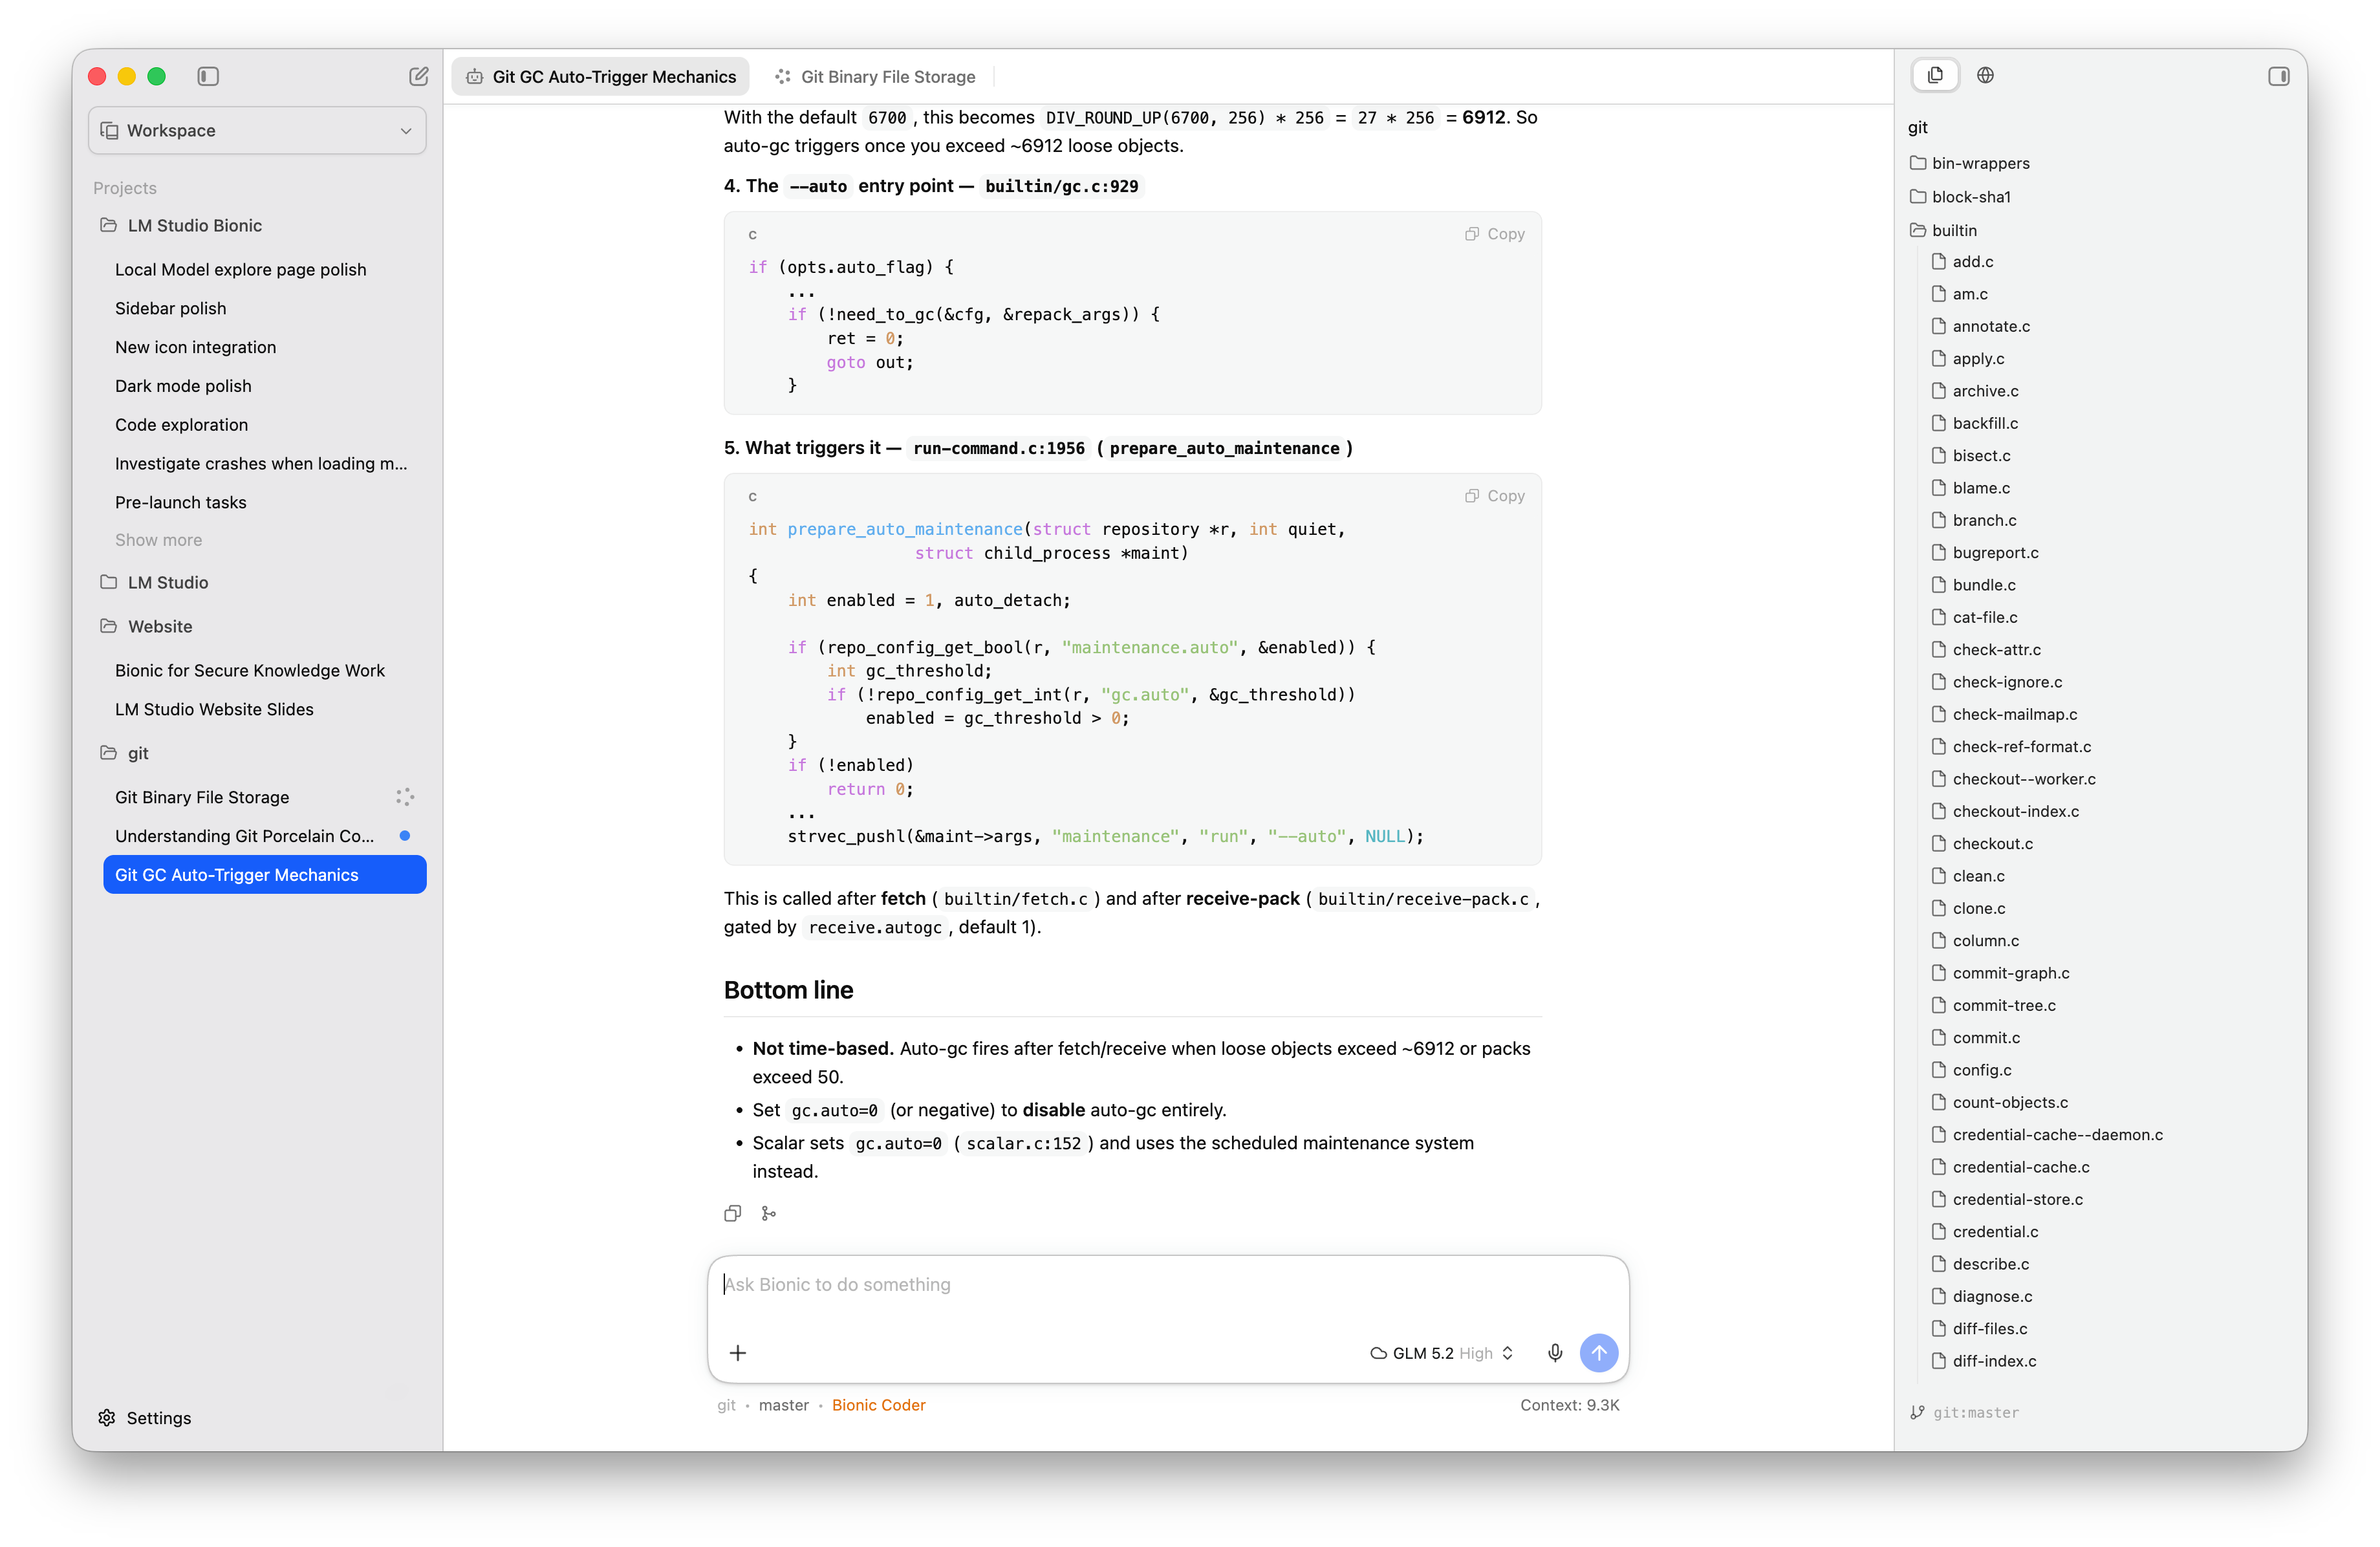
Point Bionic to a local working directory to use it for tasks that require understanding or changing a codebase.
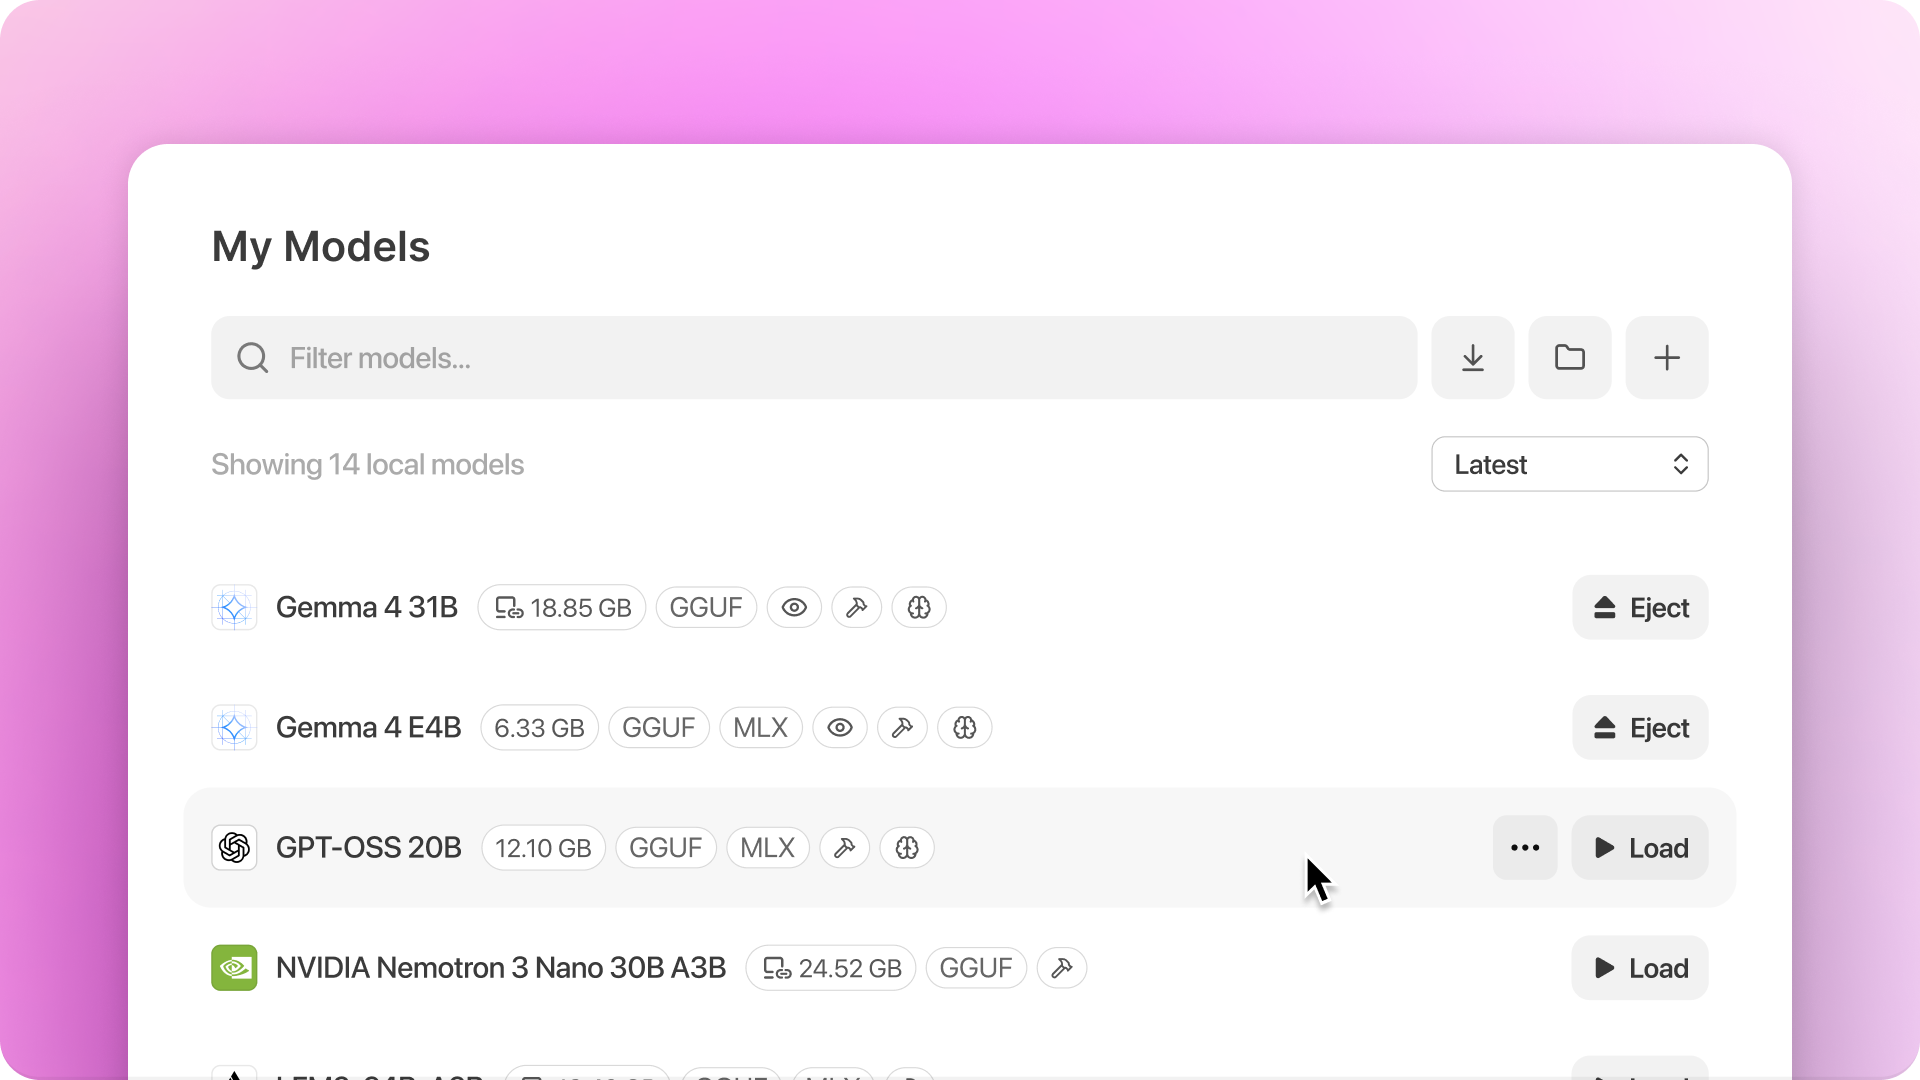 Downloaded models can run on your computer without using cloud inference credits.
Find a model [#find-a-model]
1. Open **Settings**.
2. Under **Local Models**, select **Explore**.
3. Search for a model or choose one of the listed models.
Use the format filters and device-fit information to narrow the results.
Download the model [#download-the-model]
1. Choose the download destination if more than one device is available (remote devices in LM Link).
2. Select the format and variant.
3. Start the download.
You can pause, resume, cancel, or retry a download.
Use the downloaded model [#use-the-downloaded-model]
Open **Settings** → **Local Models** → **Library** to see indexed models on the device. Then open a Bionic session and select the model from the list to use it in a session.
See [Choose a Cloud, Local, or Remote Model](/docs/bionic/models).
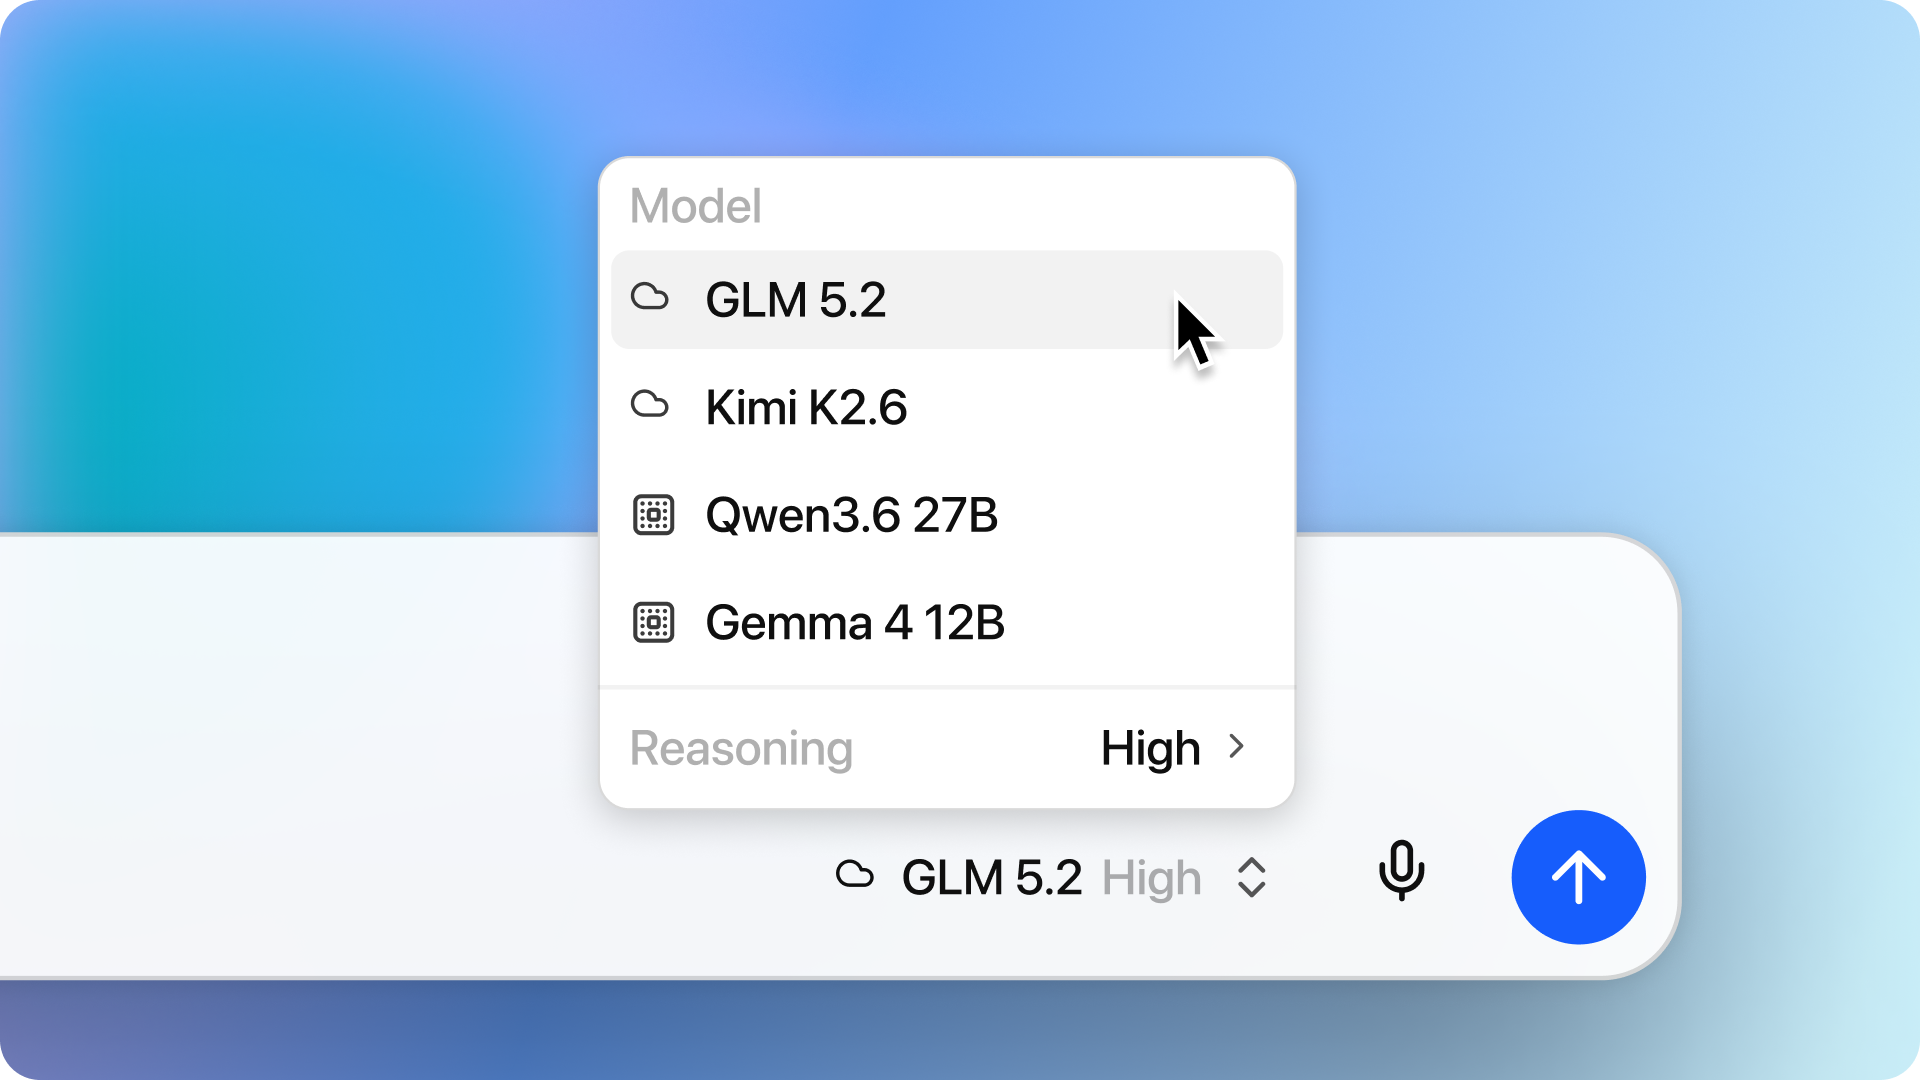 Open the model picker in a session to choose its main model. Run locally, connect through LM Link, or use the largest frontier open models through LM Studio Secure Cloud with Zero Data Retention.
Cloud models [#cloud-models]
Choose a **Cloud** model when you want a hosted model without using your computer's memory for inference.
Cloud models require:
* An internet connection.
* A signed-in LM Studio account with billing set up.
* Available personal or organization credits.
When using a cloud model, your data is processed transiently by models running in LM Studio Secure Cloud, under Zero Data Retention. Usage of cloud models will consume the credits available in your account. See [Understand Credits and Usage](/docs/bionic/accounts-plans-and-billing/credits-and-usage).
Local models [#local-models]
Choose a **Local** model to run inference on-device. The model must be downloaded and must fit your available hardware resources.
You can explore local models and download them directly in Bionic. See [Download Local Models](/docs/bionic/models/download-local-models).
Remote models [#remote-models]
A **Remote** model is a local model running on another device through LM Link. The remote device handles inference, while the conversation stays on the device where you are using Bionic.
Remote models appear only while the linked device is available and sharing its local models.
Choose for the task [#choose-for-the-task]
Consider:
* Whether the model supports the tools and image input your task needs.
* Whether the work must stay on your own devices.
* The speed and memory available on the local or remote device.
* Whether you have available credits for cloud model usage.
If the model supports configurable reasoning, you can also choose a reasoning level for the session.
Set a default [#set-a-default]
Open **Settings** → **General** and choose a **Root model** to use as the default for new sessions.
You can change the model for an existing session from its model picker.
**Voice Input** transcribes speech locally and sends the transcript into Bionic so that you can speak your ideas to the agent. Currently, Bionic supports Voxtral by Mistral AI, which is a performant multilingual realtime transcription model.
Voice settings [#voice-settings]
Your first transcription may wait a bit while the model loads. For voice input to start faster each time, turn on **Auto load voice model** to keep the transcription model loaded.
1. Open **Settings** → **Voice**.
2. Toggle on **Auto load voice model**
Requires LM Studio 0.4.0 or newer. [#requires-lm-studio-040-or-newer]
LM Studio supports API Tokens for authentication, providing a secure and convenient way to access the LM Studio API.
By default, the LM Studio API runs **without enforcing authentication**. For production or shared environments, enable API Token authentication for secure access.
Instantiate a Model
First, you need to load a model to generate completions from. This can be done using the top-level `llm` convenience API, or the `model` method in the `llm` namespace when using the scoped resource API. For example, here is how to use Qwen2.5 7B Instruct.Generate a Completion
Once you have a loaded model, you can generate completions by passing a string to the `complete` method on the `llm` handle.Print Prediction Stats
You can also print prediction metadata, such as the model used for generation, number of generated tokens, time to first token, and stop reason.Instantiate the Model
Connect to LM Studio and obtain a handle to the VLM (Vision-Language Model) you want to use.Prepare the Image
Use the `prepare_image()` function or `files` namespace method to get a handle to the image that can subsequently be passed to the model.Pass the Image to the Model in `.respond()`
Generate a prediction by passing the image to the model in the `.respond()` method.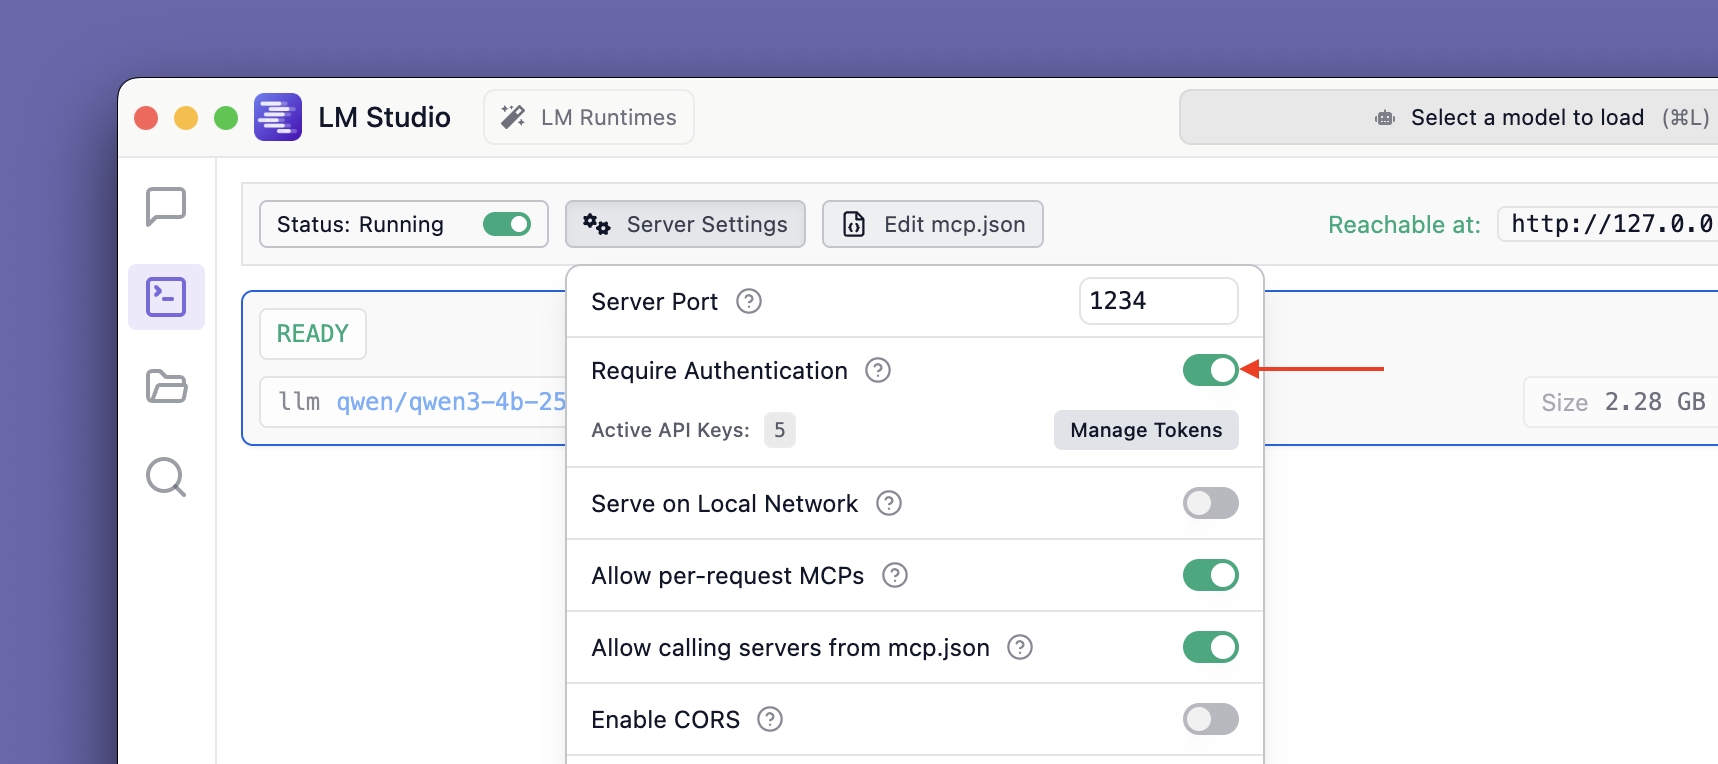
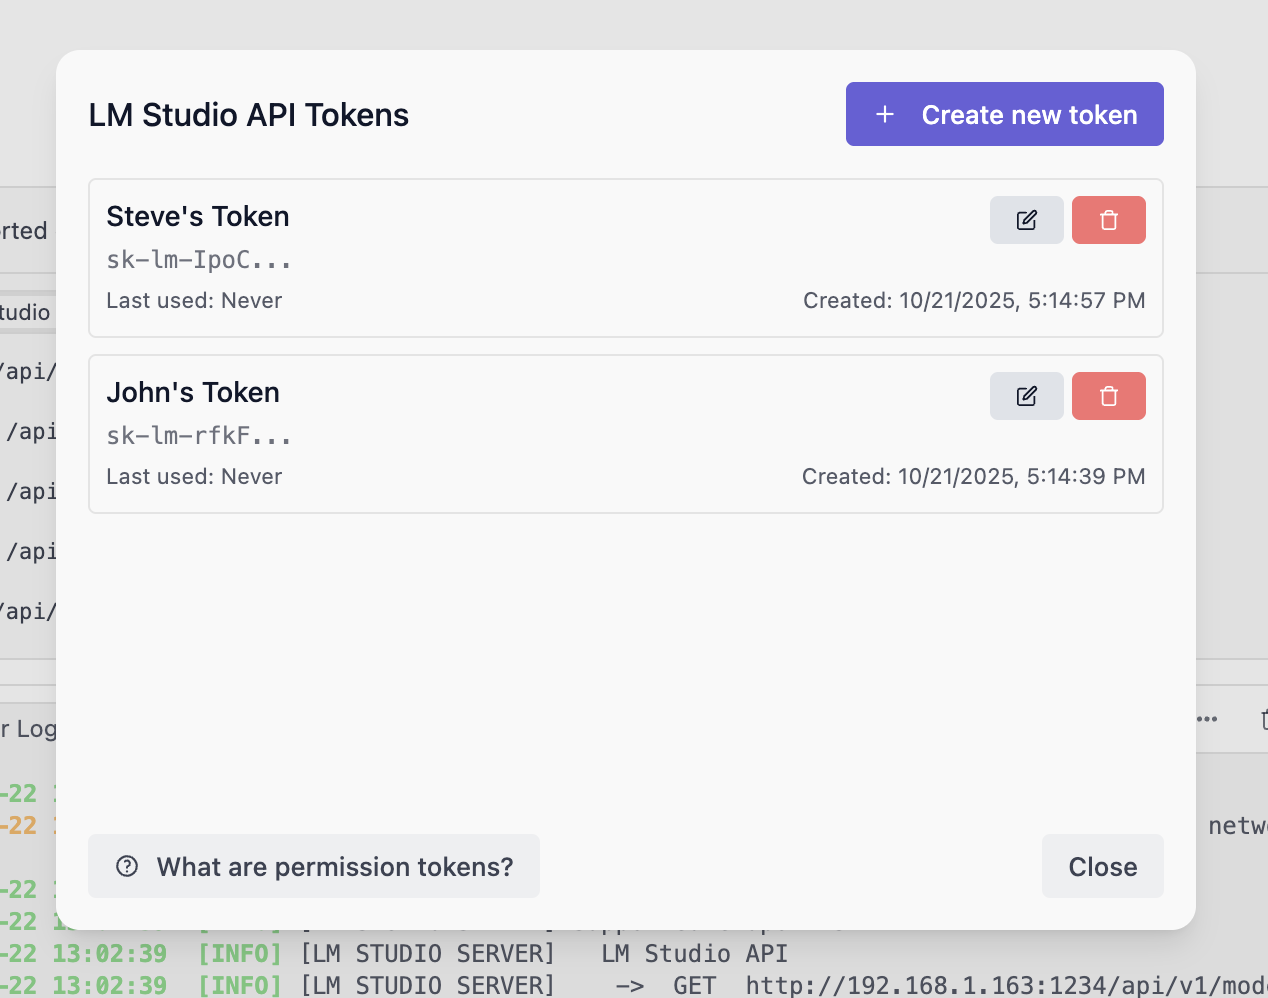 Creating API Tokens [#creating-api-tokens]
To create API Tokens, click on Manage Tokens in the Server Settings. It will open the API Tokens modal where you can create, view, and delete API Tokens.
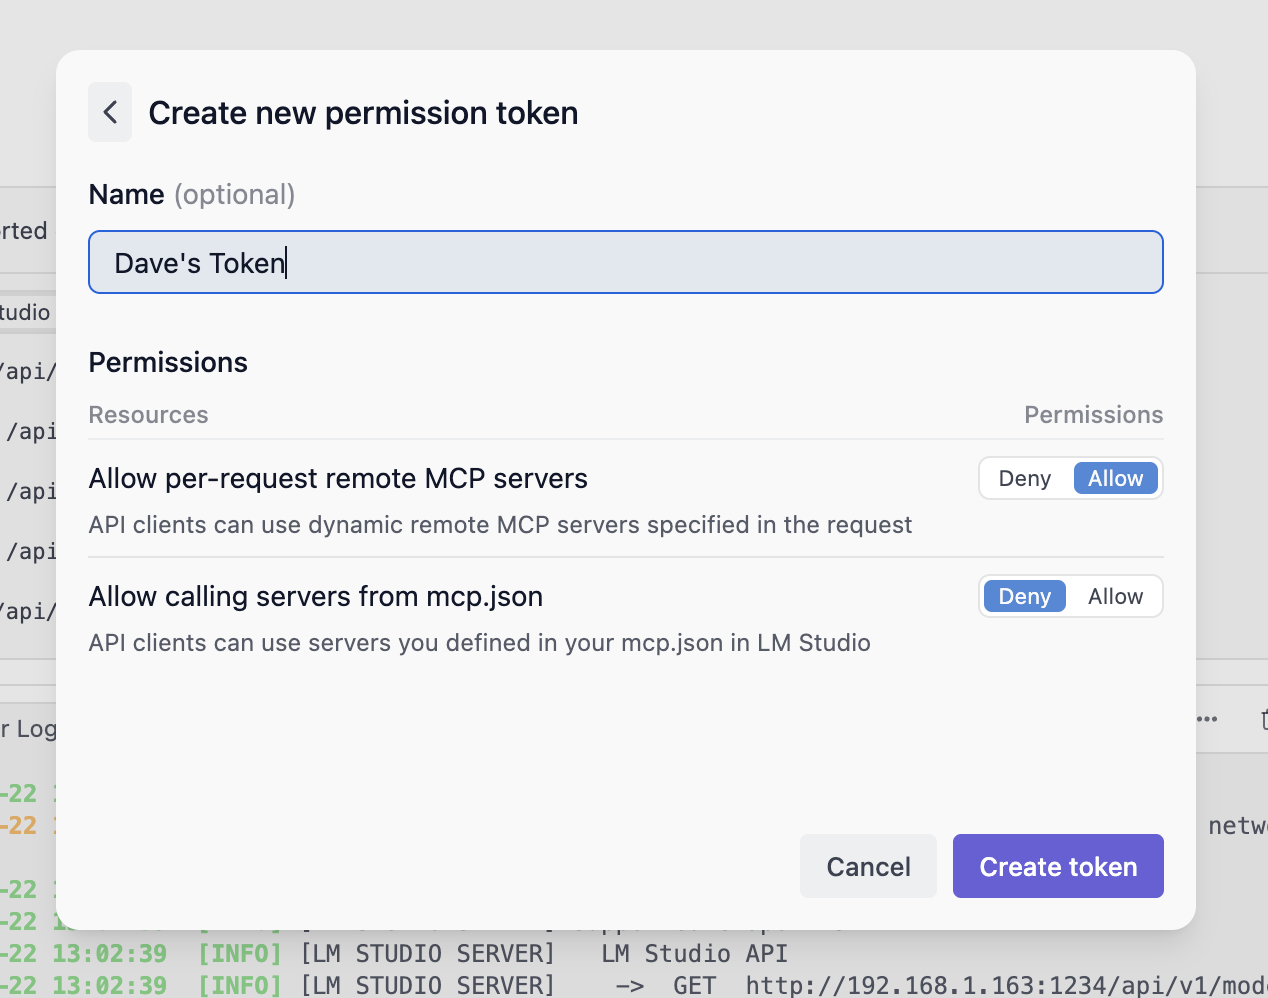
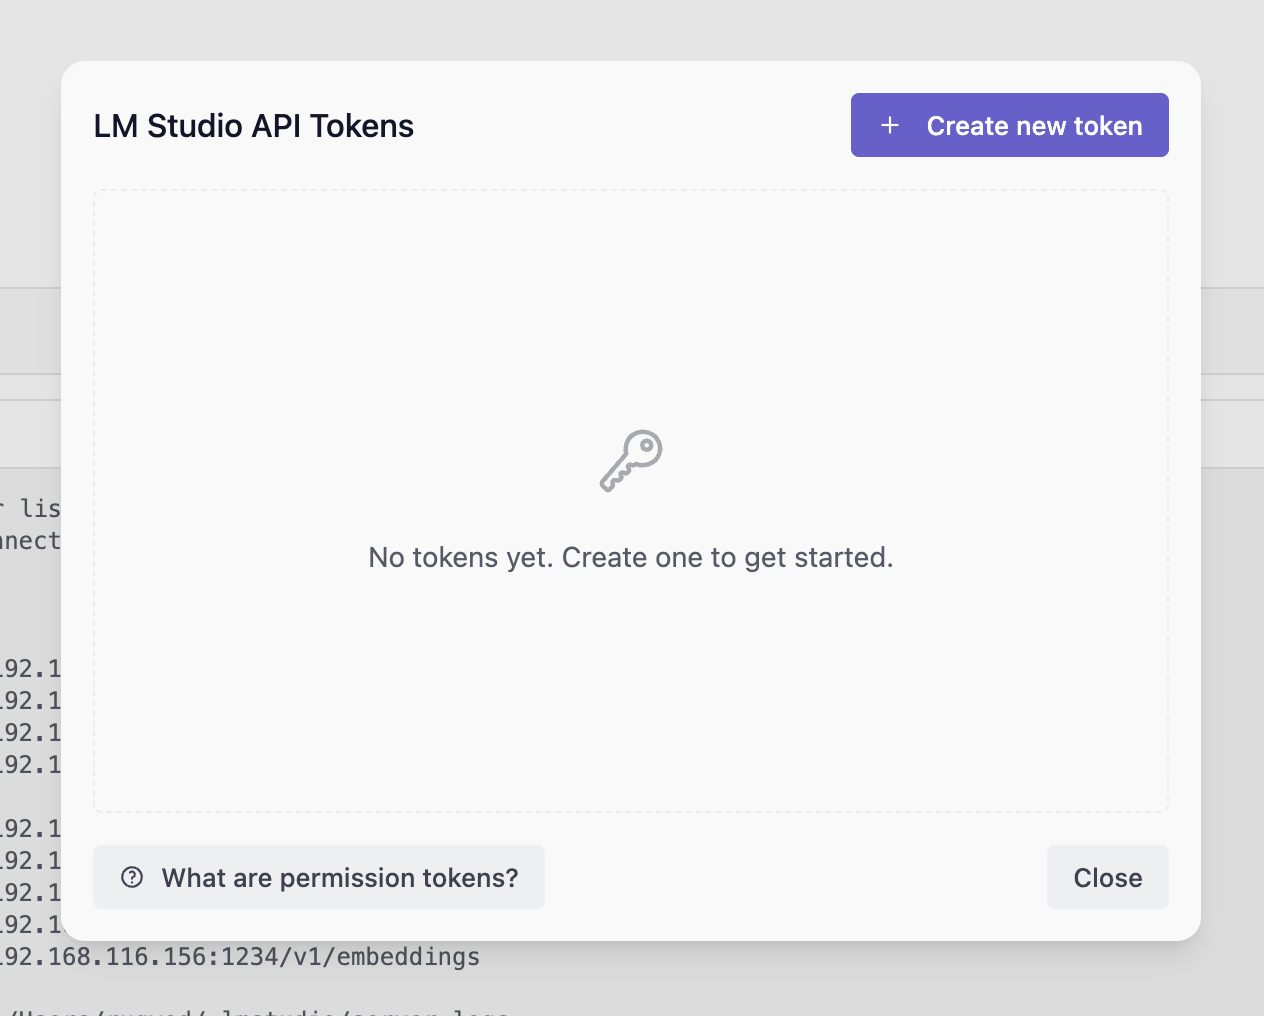 Create a token by clicking on the Create Token button. Provide a name for the token and select the desired permissions.
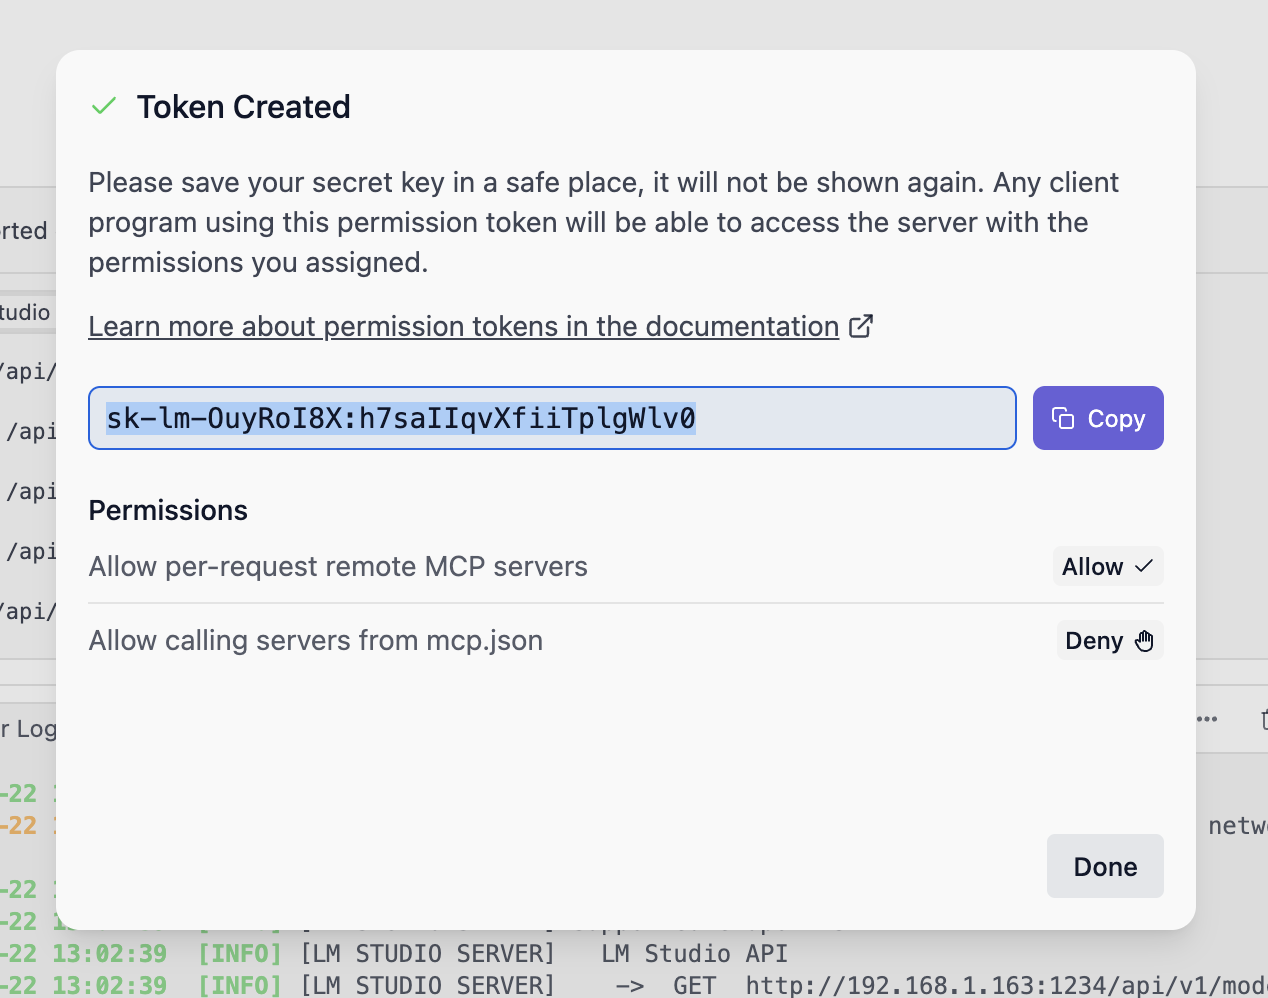
 Once created, make sure to copy the token as it will not be shown again.
 Configuring API Token Permissions [#configuring-api-token-permissions]
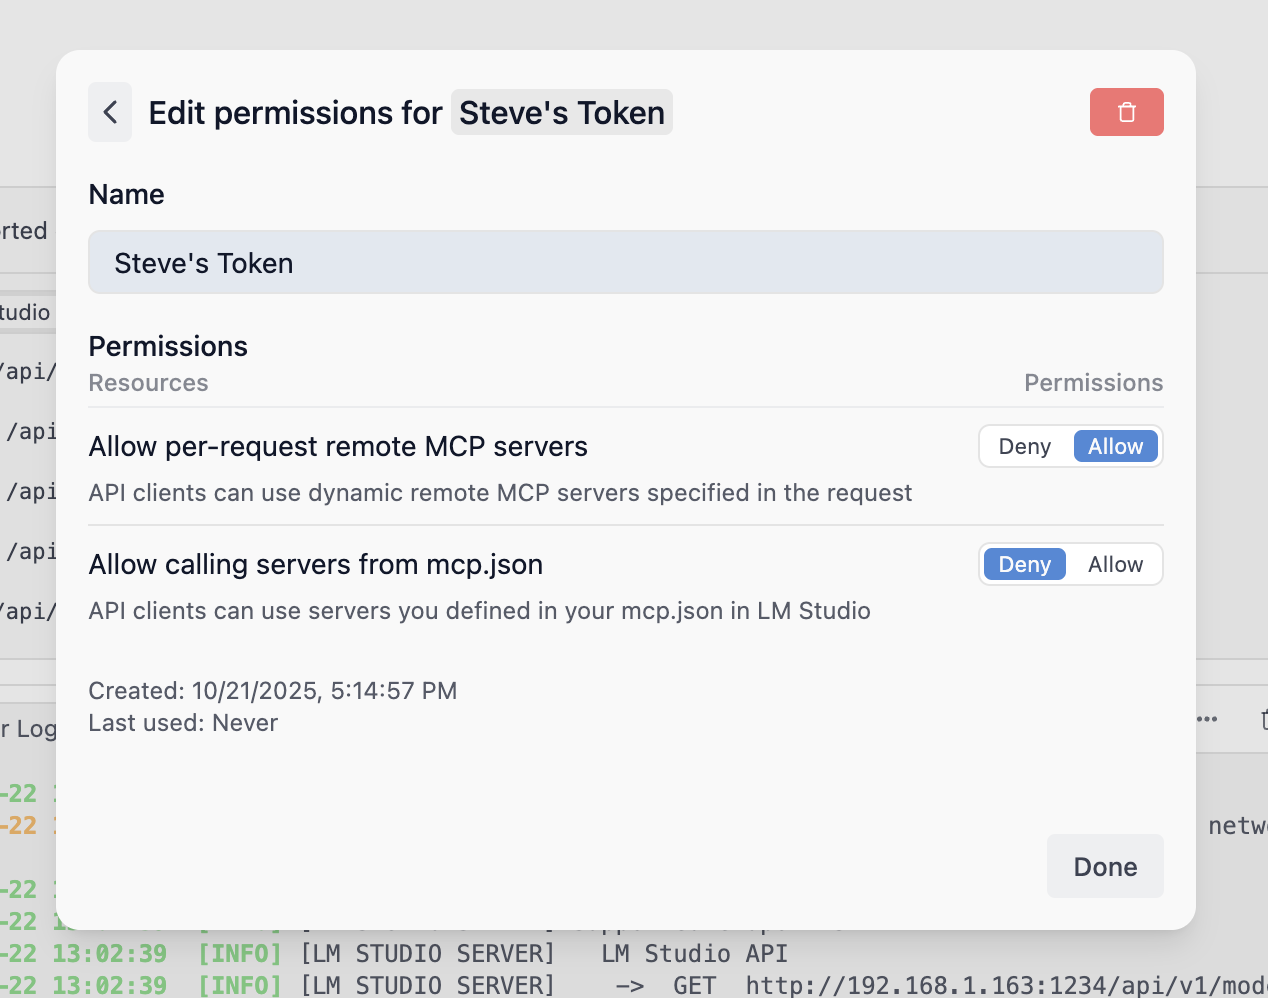
To edit the permissions of an existing API Token, click on the Edit button next to the token in the API Tokens modal. You can modify the name and permissions of the token.
 API Token Usage [#api-token-usage]
Using API Tokens with REST API: [#using-api-tokens-with-rest-api]
 Install llmster [#install-llmster]
**Linux / Mac**
```bash
curl -fsSL https://lmstudio.ai/install.sh | bash
```
**Windows**
```bash
irm https://lmstudio.ai/install.ps1 | iex
```
Start llmster [#start-llmster]
```bash
lms daemon up
```
See the [daemon CLI docs](/docs/cli/daemon/daemon-up) for full reference.
For setting up llmster as a startup task on Linux, see [Linux Startup Task](/docs/developer/core/headless_llmster).
Option 2: Desktop app in headless mode [#option-2-desktop-app-in-headless-mode]
This works on Mac, Windows, and Linux machines with a graphical user interface. It's useful if you already have the desktop app installed and want it to run as a background service.
Run the LLM service on machine login [#run-the-llm-service-on-machine-login]
Head to app settings (`Cmd` / `Ctrl` + `,`) and check the box to run the LLM server on login.
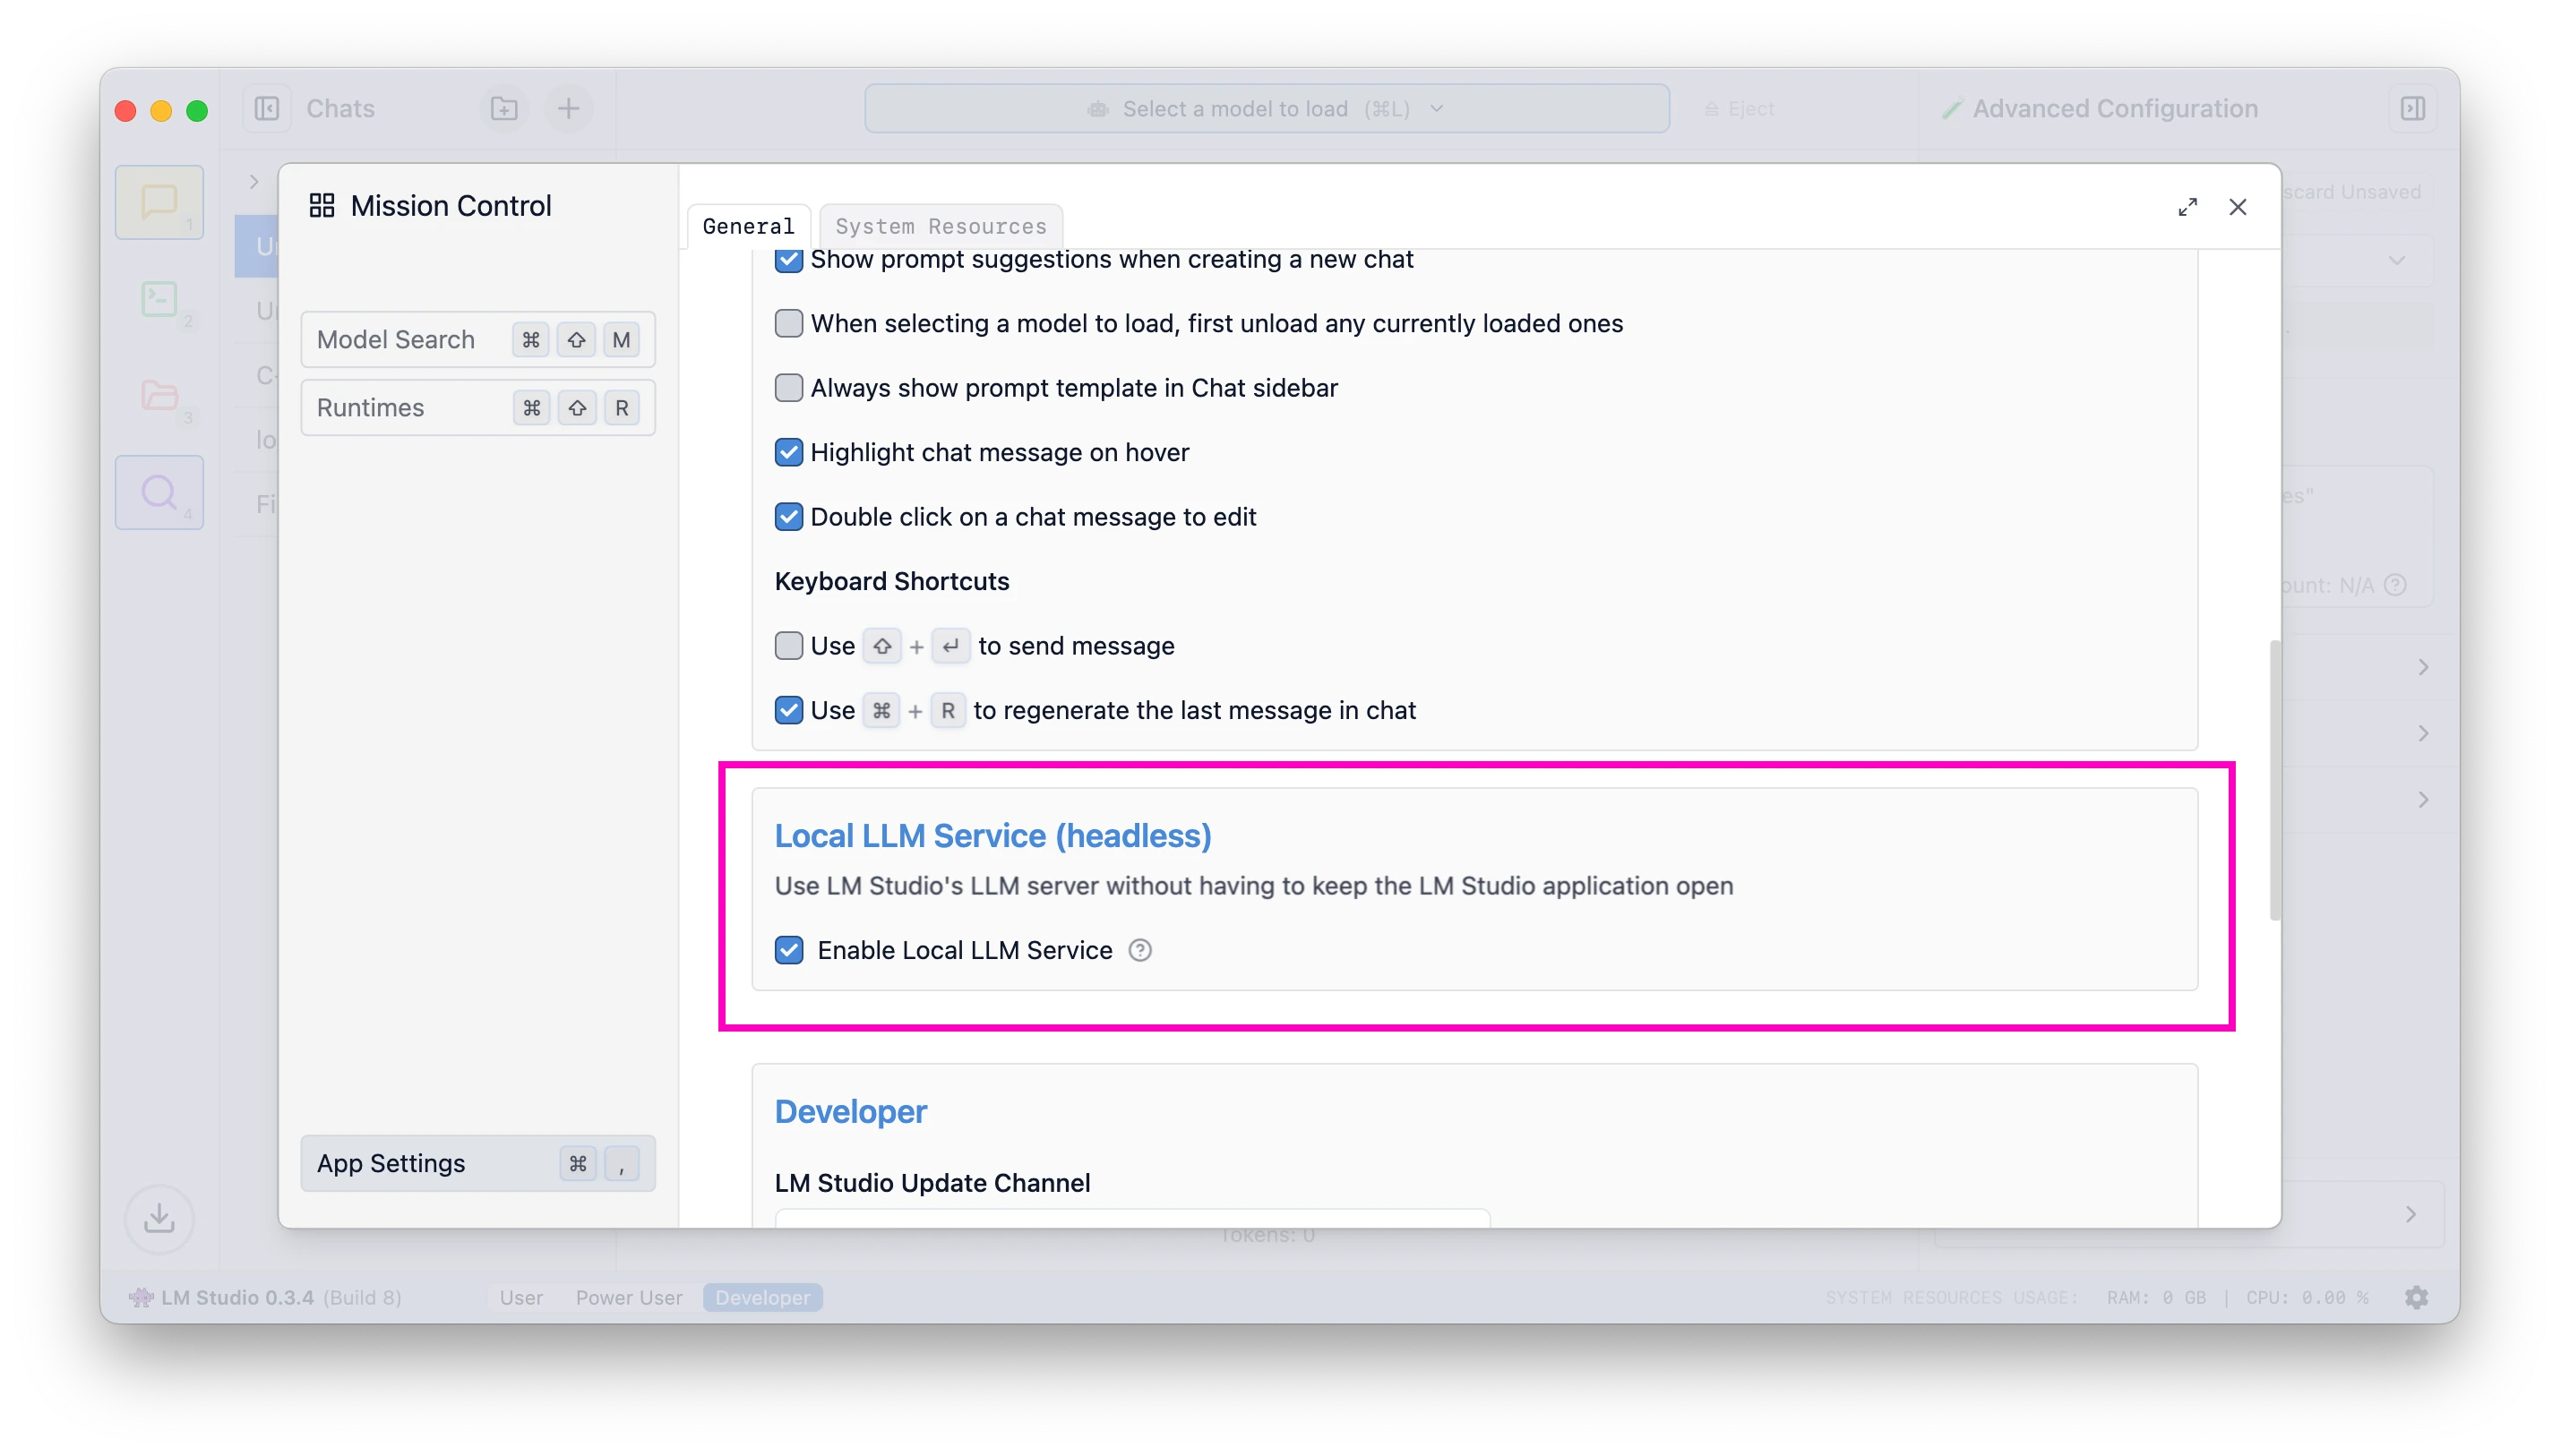 When this setting is enabled, exiting the app will minimize it to the system tray, and the LLM server will continue to run in the background.
Auto Server Start [#auto-server-start]
Your last server state will be saved and restored on app or service launch.
To achieve this programmatically:
```bash
lms server start
```
Just-In-Time (JIT) model loading for REST endpoints [#just-in-time-jit-model-loading-for-rest-endpoints]
Applies to both options. Useful when using LM Studio as an LLM service with other frontends or applications.
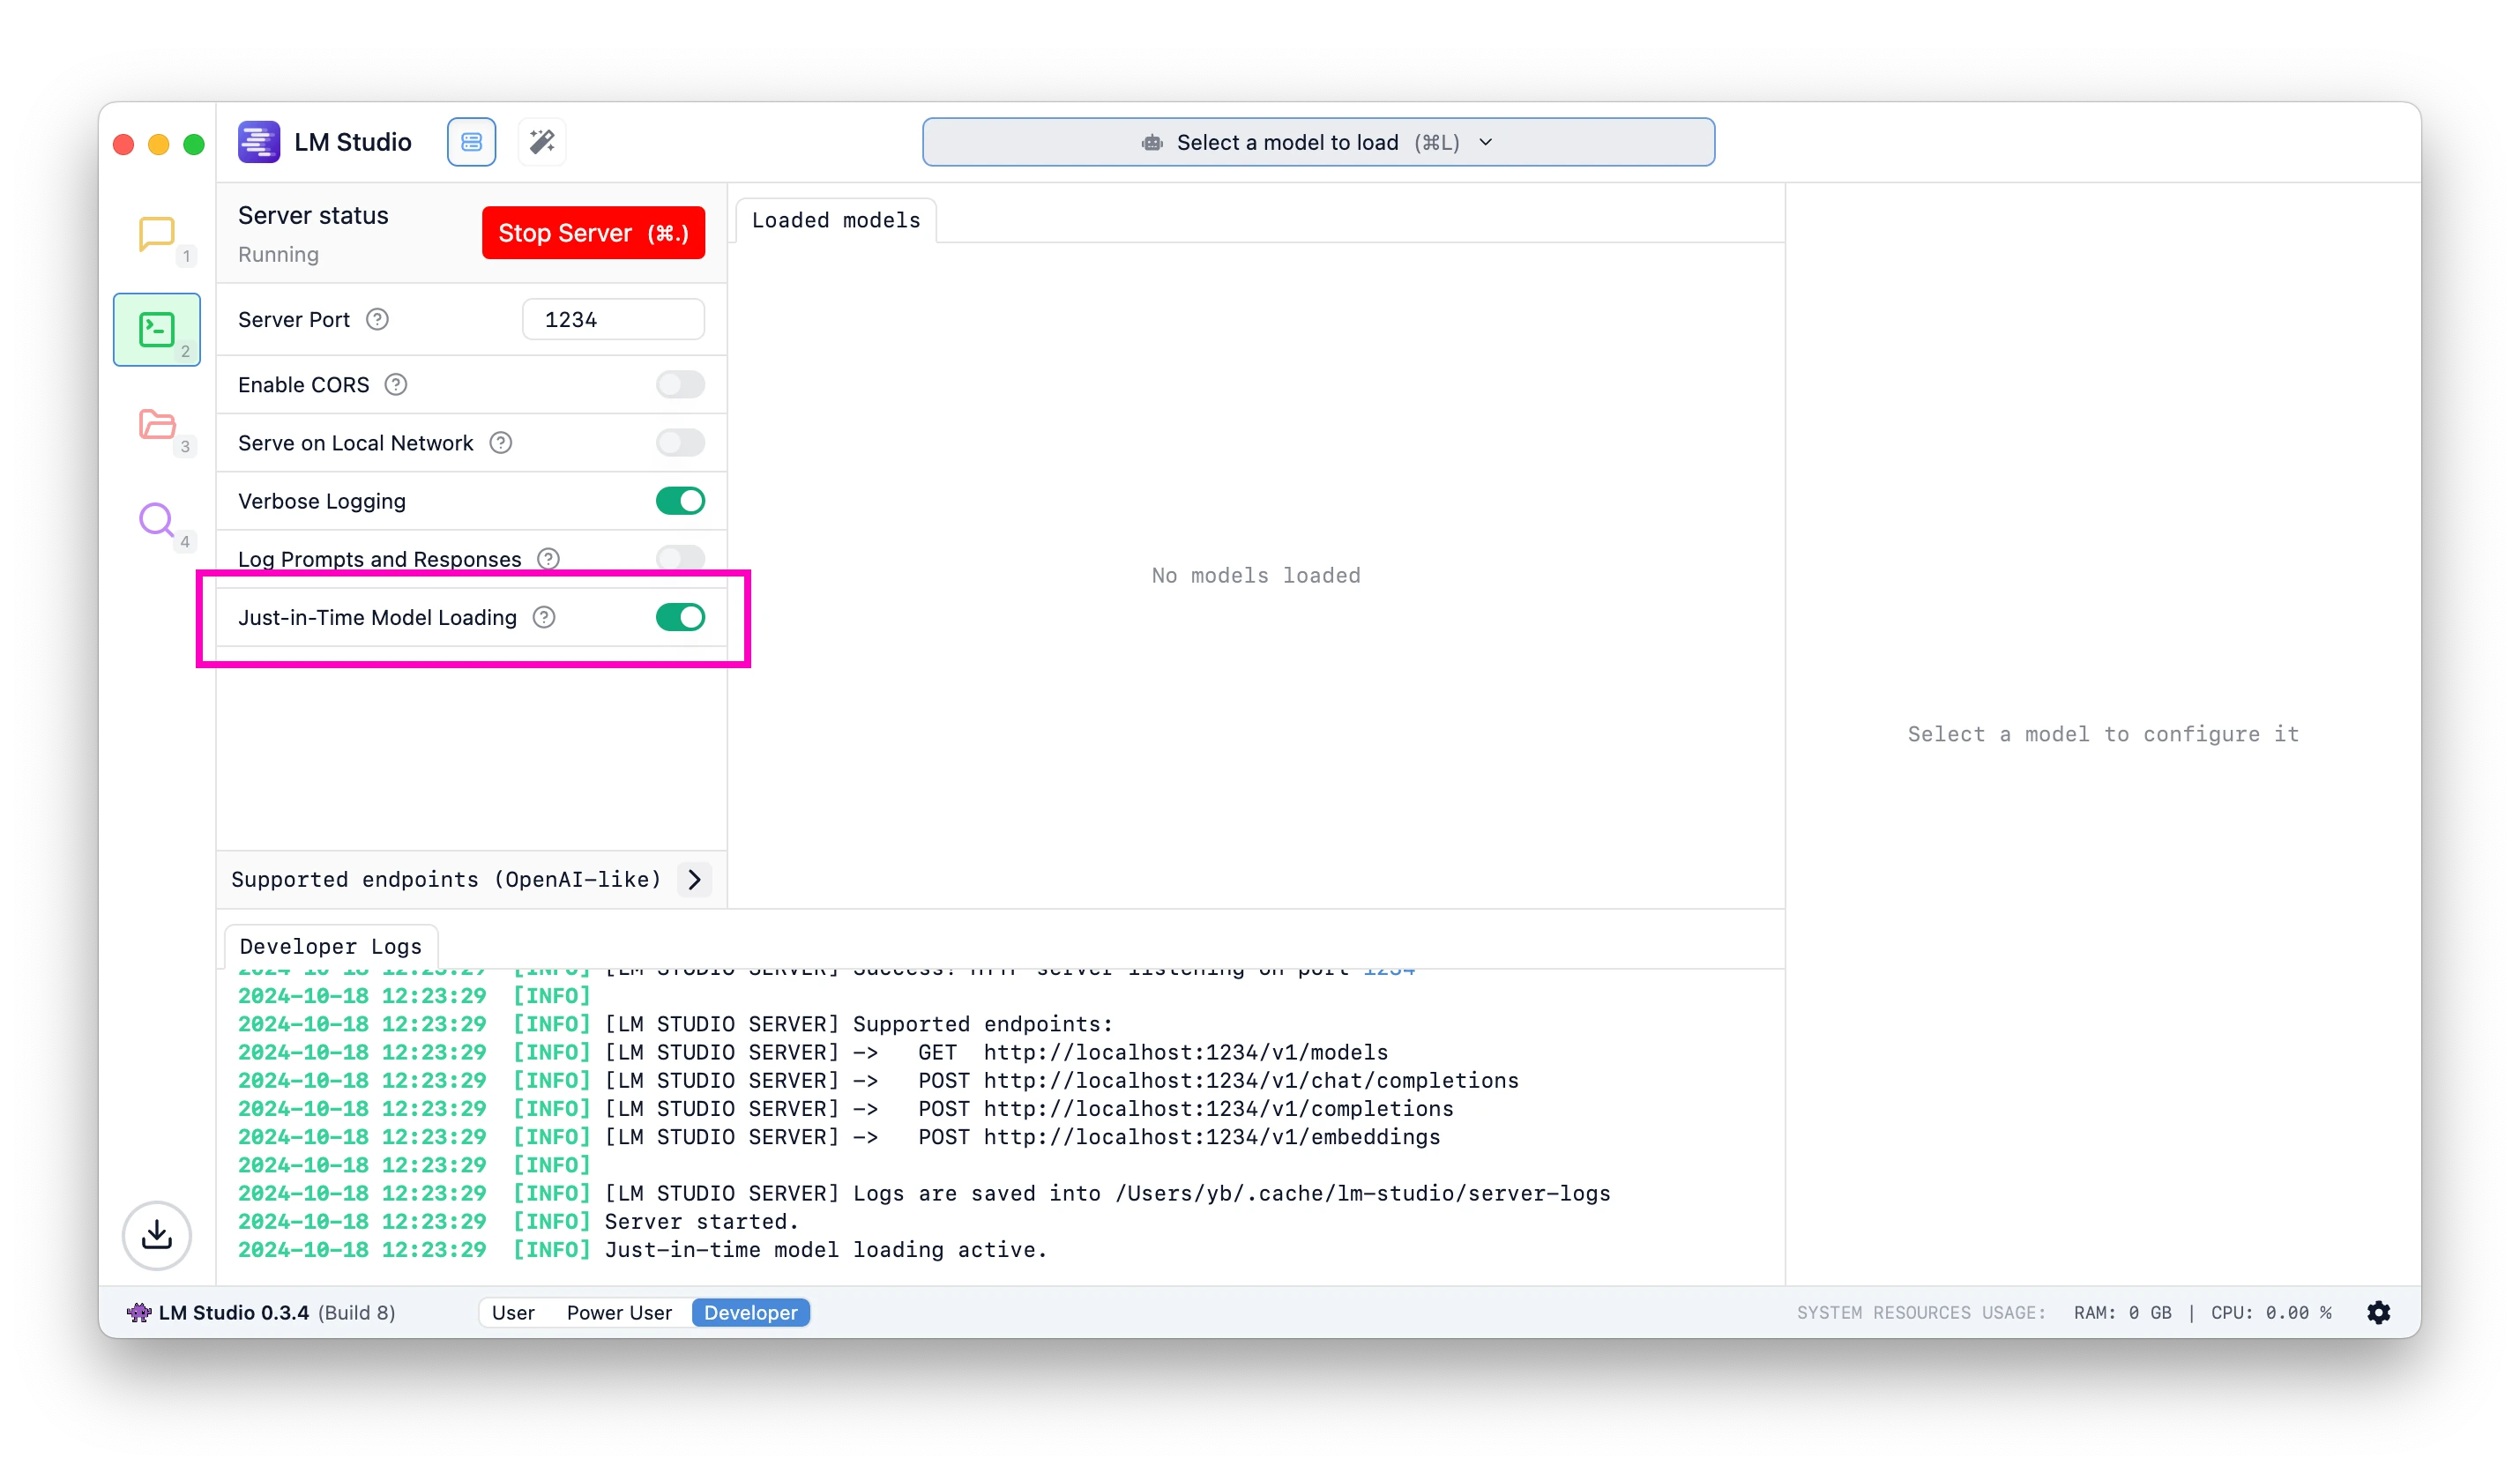 When JIT loading is ON: [#when-jit-loading-is-on]
* Calls to OpenAI-compatible `/v1/models` will return all downloaded models, not only the ones loaded into memory
* Calls to inference endpoints will load the model into memory if it's not already loaded
When JIT loading is OFF: [#when-jit-loading-is-off]
* Calls to OpenAI-compatible `/v1/models` will return only the models loaded into memory
* You have to first load the model into memory before being able to use it
What about auto unloading? [#what-about-auto-unloading]
JIT loaded models will be auto-unloaded from memory by default after a set period of inactivity ([learn more](/docs/developer/core/ttl-and-auto-evict)).
Community [#community]
Chat with other LM Studio developers, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC).
Please report bugs and issues in the [lmstudio-bug-tracker](https://github.com/lmstudio-ai/lmstudio-bug-tracker/issues) GitHub repository.
`llmster`, LM Studio's headless daemon, can be configured to run on startup. This guide covers setting up `llmster` to launch, load a model, and start an HTTP server automatically using `systemctl` on Linux.
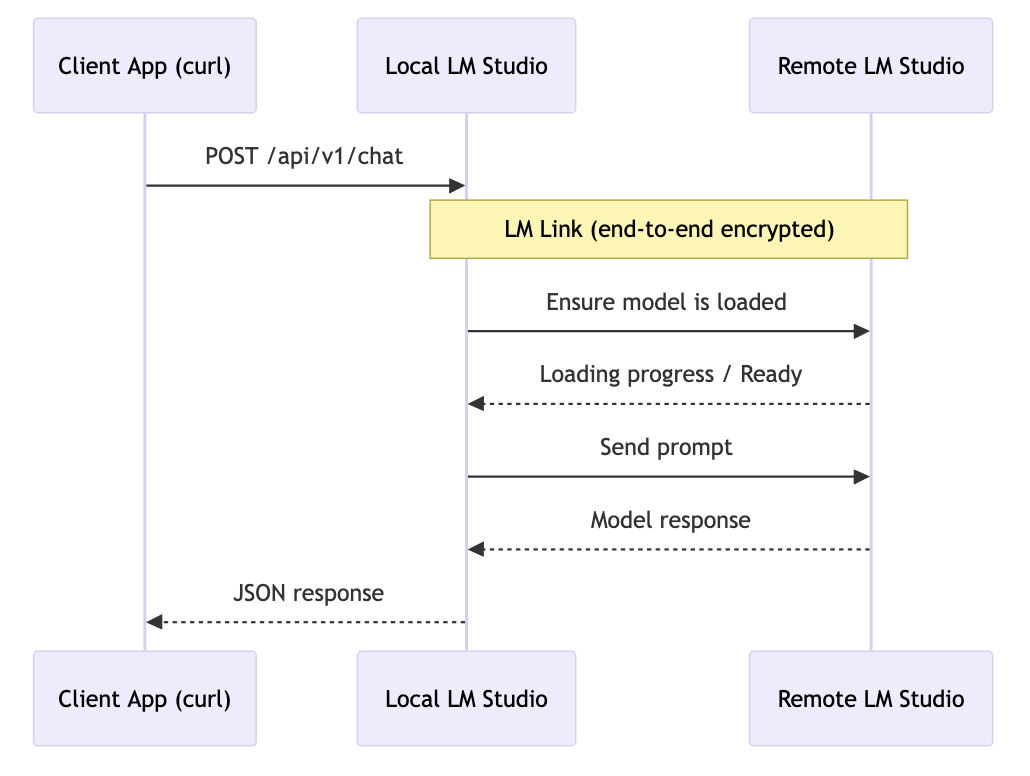 The preferred device setting is per-machine. Each device on the link independently controls which remote machine it prefers. See [how to set a preferred device](/docs/lmlink/basics/preferred-device) for more details.
Use the REST API as normal [#use-the-rest-api-as-normal]
Use the REST API exactly as you would locally. See the [REST API docs](/docs/developer/rest) for usage details.
If you're running into trouble, hop onto our [Discord](https://discord.gg/lmstudio)
Requires LM Studio 0.4.0 or newer. [#requires-lm-studio-040-or-newer]
LM Studio supports Model Context Protocol (MCP) usage via API. MCP allows models to interact with external tools and services through standardized servers.
How it works [#how-it-works]
MCP servers provide tools that models can call during chat requests. You can enable MCP servers in two ways: as ephemeral servers defined per-request, or as pre-configured servers in your `mcp.json` file.
Ephemeral vs mcp.json servers [#ephemeral-vs-mcpjson-servers]
| Feature | Ephemeral | mcp.json |
|---|---|---|
| How to specify in request |
integrations
->
"type": "ephemeral_mcp"
|
integrations
->
"type": "plugin"
|
| Configuration | Only defined per-request |
Pre-configured in
mcp.json
|
| Use case | One-off requests, remote MCP tool execution |
MCP servers that require
command
, frequently used servers
|
| Server ID |
Specified via
server_label
in integration
|
Specified via
id
(e.g.,
mcp/playwright
) in integration
|
| Custom headers |
Supported via
headers
field
|
Configured in
mcp.json
|
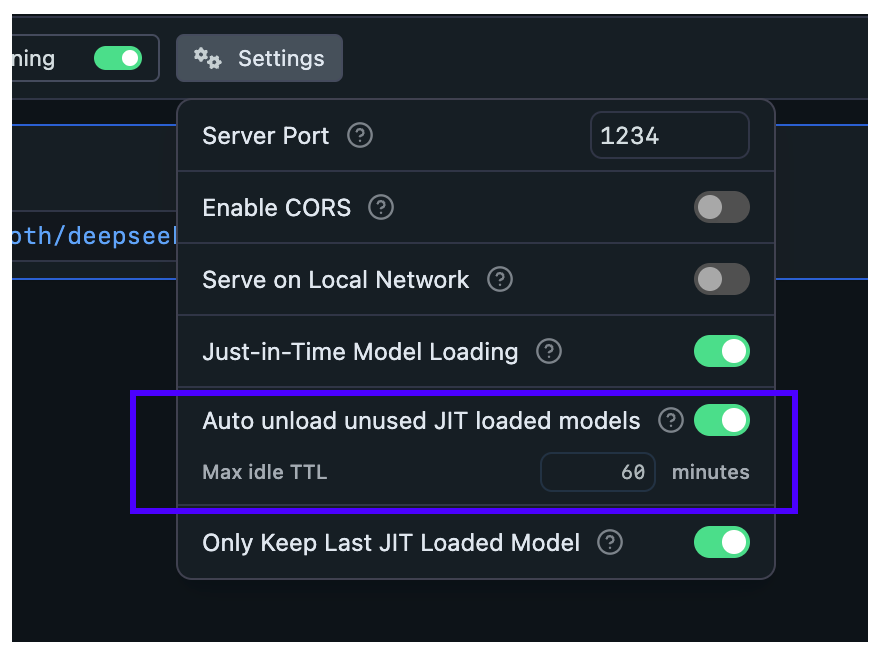 Set per-model TTL-model in API requests [#set-per-model-ttl-model-in-api-requests]
When JIT loading is enabled, the **first request** to a model will load it into memory. You can specify a TTL for that model in the request payload.
This works for requests targeting both the [OpenAI compatibility API](/docs/developer/openai-api) and the [LM Studio's REST API](/docs/developer/rest):
```diff
curl http://localhost:1234/api/v0/chat/completions \
-H "Content-Type: application/json" \
-d '{
"model": "deepseek-r1-distill-qwen-7b",
+ "ttl": 300,
"messages": [ ... ]
}'
```
This will set a TTL of 5 minutes (300 seconds) for this model if it is JIT loaded. [#this-will-set-a-ttl-of-5-minutes-300-seconds-for-this-model-if-it-is-jit-loaded]
Set TTL for models loaded with `lms` [#set-ttl-for-models-loaded-with-lms]
By default, models loaded with `lms load` do not have a TTL, and will remain loaded in memory until you manually unload them.
You can set a TTL for a model loaded with `lms` like so:
```bash
lms load
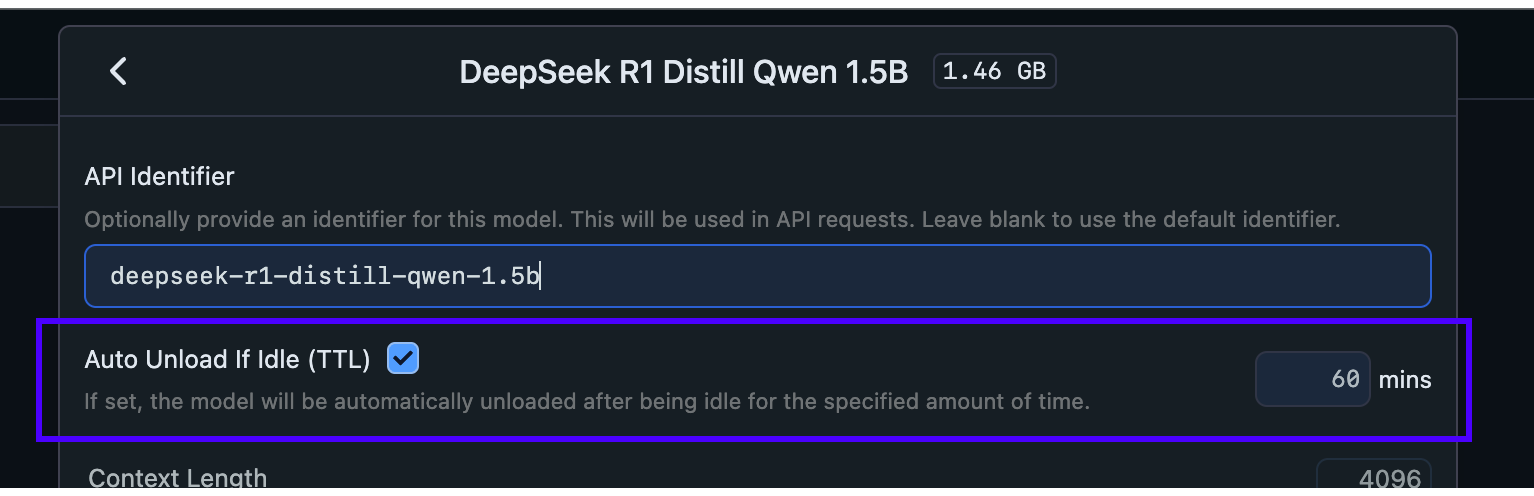 Configure Auto-Evict for JIT loaded models [#configure-auto-evict-for-jit-loaded-models]
With this setting, you can ensure new models loaded via JIT automatically unload previously loaded models first.
This is useful when you want to switch between models from another app without worrying about memory building up with unused models.
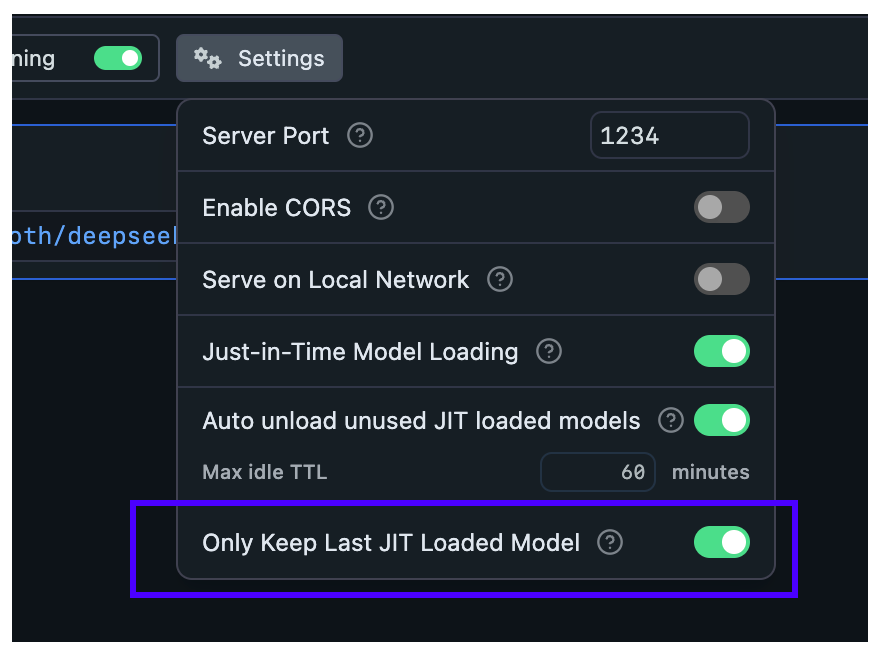 **When Auto-Evict is ON** (default):
* At most `1` model is kept loaded in memory at a time (when loaded via JIT)
* Non-JIT loaded models are not affected
**When Auto-Evict is OFF**:
* Switching models from an external app will keep previous models loaded in memory
* Models will remain loaded until either:
* Their TTL expires
* You manually unload them
This feature works in tandem with TTL to provide better memory management for your workflow.
Nomenclature [#nomenclature]
`TTL`: Time-To-Live, is a term borrowed from networking protocols and cache systems. It defines how long a resource can remain allocated before it's considered stale and evicted.
| Endpoint | Method | Docs |
|---|---|---|
/api/v1/chat
|
|
Chat |
/api/v1/models
|
|
List Models |
/api/v1/models/load
|
|
Load |
/api/v1/models/unload
|
|
Unload |
/api/v1/models/download
|
|
Download |
/api/v1/models/download/status
|
|
Download Status |
| Feature |
/api/v1/chat
|
/v1/responses
|
/v1/chat/completions
|
/v1/messages
|
|---|---|---|---|---|
| Streaming | ✅ | ✅ | ✅ | ✅ |
| Stateful chat | ✅ | ✅ | ❌ | ❌ |
| Remote MCPs | ✅ | ✅ | ❌ | ❌ |
| MCPs you have in LM Studio | ✅ | ✅ | ❌ | ❌ |
| Custom tools | ❌ | ✅ | ✅ | ✅ |
| Include assistant messages in the request | ❌ | ✅ | ✅ | ✅ |
| Model load streaming events | ✅ | ❌ | ❌ | ❌ |
| Prompt processing streaming events | ✅ | ❌ | ❌ | ❌ |
| Specify context length in the request | ✅ | ❌ | ❌ | ❌ |
| Endpoint | Method | Docs |
|---|---|---|
/v1/models
|
|
Models |
/v1/responses
|
|
Responses |
/v1/decisions
|
|
Decisions |
/v1/chat/completions
|
|
Chat Completions |
/v1/embeddings
|
|
Embeddings |
/v1/completions
|
|
Completions |
Set the `base url` to point to LM Studio [#set-the-base-url-to-point-to-lm-studio] You can reuse existing OpenAI clients (in Python, JS, C#, etc) by switching up the "base URL" property to point to your LM Studio instead of OpenAI's servers. Note: The following examples assume the server port is `1234` Python Example [#python-example] ```diff from openai import OpenAI client = OpenAI( + base_url="http://localhost:1234/v1" ) # ... the rest of your code ... ``` Typescript Example [#typescript-example] ```diff import OpenAI from 'openai'; const client = new OpenAI({ + baseUrl: "http://localhost:1234/v1" }); // ... the rest of your code ... ``` cURL Example [#curl-example] ```diff - curl https://api.openai.com/v1/chat/completions \ + curl http://localhost:1234/v1/chat/completions \ -H "Content-Type: application/json" \ -d '{ - "model": "gpt-4o-mini", + "model": "use the model identifier from LM Studio here", "messages": [{"role": "user", "content": "Say this is a test!"}], "temperature": 0.7 }' ``` Using Codex with LM Studio [#using-codex-with-lm-studio] Codex is supported because LM Studio implements the OpenAI-compatible `POST /v1/responses` endpoint. See: [Use Codex with LM Studio](/docs/integrations/codex) and [Responses](/docs/developer/openai-compat/responses). *** Other OpenAI client libraries should have similar options to set the base URL. If you're running into trouble, hop onto our [Discord](https://discord.gg/lmstudio) and enter the `#🔨-developers` channel. * Method: `GET` * Returns the models visible to the server. The list may include all downloaded models when Just‑In‑Time loading is enabled. cURL [#curl] ```bash curl http://localhost:1234/v1/models ``` * Method: `POST` * See OpenAI docs: [https://platform.openai.com/docs/api-reference/responses](https://platform.openai.com/docs/api-reference/responses) cURL (non‑streaming) [#curl-nonstreaming] ```bash curl http://localhost:1234/v1/responses \ -H "Content-Type: application/json" \ -d '{ "model": "openai/gpt-oss-20b", "input": "Provide a prime number less than 50", "reasoning": { "effort": "low" } }' ``` Stateful follow‑up [#stateful-followup] Use the `id` from a previous response as `previous_response_id`. ```bash curl http://localhost:1234/v1/responses \ -H "Content-Type: application/json" \ -d '{ "model": "openai/gpt-oss-20b", "input": "Multiply it by 2", "previous_response_id": "resp_123" }' ``` Streaming [#streaming] ```bash curl http://localhost:1234/v1/responses \ -H "Content-Type: application/json" \ -d '{ "model": "openai/gpt-oss-20b", "input": "Hello", "stream": true }' ``` You will receive SSE events such as `response.created`, `response.output_text.delta`, and `response.completed`. Tools and Remote MCP (opt‑in) [#tools-and-remote-mcp-optin] Enable Remote MCP in the app (Developer → Settings). Example payload using an MCP server tool: ```bash curl http://localhost:1234/v1/responses \ -H "Content-Type: application/json" \ -d '{ "model": "ibm/granite-4-micro", "input": "What is the top trending model on hugging face?", "tools": [ { "type": "mcp", "server_label": "huggingface", "server_url": "https://huggingface.co/mcp", "allowed_tools": [ "model_search" ] } ] }' ``` You can enforce a particular response format from an LLM by providing a JSON schema to the `/v1/chat/completions` endpoint, via LM Studio's REST API (or via any OpenAI client).
Start LM Studio as a server [#start-lm-studio-as-a-server] To use LM Studio programmatically from your own code, run LM Studio as a local server. You can turn on the server from the "Developer" tab in LM Studio, or via the `lms` CLI: ``` lms server start ``` Install `lms` by running `npx lmstudio install-cli` [#install-lms-by-running-npx-lmstudio-install-cli] This will allow you to interact with LM Studio via the REST API. For an intro to LM Studio's REST API, see [REST API Overview](/docs/developer/rest). Structured Output [#structured-output] The API supports structured JSON outputs through the `/v1/chat/completions` endpoint when given a [JSON schema](https://json-schema.org/overview/what-is-jsonschema). Doing this will cause the LLM to respond in valid JSON conforming to the schema provided. It follows the same format as OpenAI's recently announced [Structured Output](https://platform.openai.com/docs/guides/structured-outputs) API and is expected to work via the OpenAI client SDKs. **Example using `curl`** This example demonstrates a structured output request using the `curl` utility. To run this example on Mac or Linux, use any terminal. On Windows, use [Git Bash](https://git-scm.com/download/win). ```bash curl http://localhost:1234/v1/chat/completions \ -H "Content-Type: application/json" \ -d '{ "model": "{{model}}", "messages": [ { "role": "system", "content": "You are a helpful jokester." }, { "role": "user", "content": "Tell me a joke." } ], "response_format": { "type": "json_schema", "json_schema": { "name": "joke_response", "strict": "true", "schema": { "type": "object", "properties": { "joke": { "type": "string" } }, "required": ["joke"] } } }, "temperature": 0.7, "max_tokens": 50, "stream": false }' ``` All parameters recognized by `/v1/chat/completions` will be honored, and the JSON schema should be provided in the `json_schema` field of `response_format`. The JSON object will be provided in `string` form in the typical response field, `choices[0].message.content`, and will need to be parsed into a JSON object. **Example using `python`** ```python from openai import OpenAI import json # Initialize OpenAI client that points to the local LM Studio server client = OpenAI( base_url="http://localhost:1234/v1", api_key="lm-studio" ) # Define the conversation with the AI messages = [ {"role": "system", "content": "You are a helpful AI assistant."}, {"role": "user", "content": "Create 1-3 fictional characters"} ] # Define the expected response structure character_schema = { "type": "json_schema", "json_schema": { "name": "characters", "schema": { "type": "object", "properties": { "characters": { "type": "array", "items": { "type": "object", "properties": { "name": {"type": "string"}, "occupation": {"type": "string"}, "personality": {"type": "string"}, "background": {"type": "string"} }, "required": ["name", "occupation", "personality", "background"] }, "minItems": 1, } }, "required": ["characters"] }, } } # Get response from AI response = client.chat.completions.create( model="your-model", messages=messages, response_format=character_schema, ) # Parse and display the results results = json.loads(response.choices[0].message.content) print(json.dumps(results, indent=2)) ``` **Important**: Not all models are capable of structured output, particularly LLMs below 7B parameters. Check the model card README if you are unsure if the model supports structured output. Structured output engine [#structured-output-engine] * For `GGUF` models: utilize `llama.cpp`'s grammar-based sampling APIs. * For `MLX` models: using [Outlines](https://github.com/dottxt-ai/outlines). The MLX implementation is available on Github: [lmstudio-ai/mlx-engine](https://github.com/lmstudio-ai/mlx-engine).
Community [#community] Chat with other LM Studio users, discuss LLMs, hardware, and more on the [LM Studio Discord server](https://discord.gg/aPQfnNkxGC). Tool use enables LLMs to request calls to external functions and APIs through the `/v1/chat/completions` and `v1/responses` endpoints ([Learn more](/docs/developer/openai-compat)), via LM Studio's REST API (or via any OpenAI client). This expands their functionality far beyond text output.
Quick Start [#quick-start]
Start LM Studio as a server
To use LM Studio programmatically from your own code, run LM Studio as a local server. You can turn on the server from the "Developer" tab in LM Studio, or via the `lms` CLI: ```bash lms server start ``` **Install `lms` by running `npx lmstudio install-cli`** This will allow you to interact with LM Studio via the REST API. For an intro to LM Studio's REST API, see [REST API Overview](/docs/developer/rest).Load a Model
You can load a model from the "Chat" or "Developer" tabs in LM Studio, or via the `lms` CLI: ```bash lms load ```Copy, Paste, and Run an Example!
* `Curl` * [Single Turn Tool Call Request](#example-using-curl) * `Python` * [Single Turn Tool Call + Tool Use](#single-turn-example) * [Multi-Turn Example](#multi-turn-example) * [Advanced Agent Example](#advanced-agent-example)Expand to see example of default tool use format
```bash -> % lms log stream Streaming logs from LM Studio timestamp: 11/13/2024, 9:35:15 AM type: llm.prediction.input modelIdentifier: gemma-2-2b-it modelPath: lmstudio-community/gemma-2-2b-it-GGUF/gemma-2-2b-it-Q4_K_M.gguf input: "
multi-turn-example.py
(click to expand)
```python
from datetime import datetime, timedelta
import json
import random
from openai import OpenAI
# Point to the local server
client = OpenAI(base_url="http://localhost:1234/v1", api_key="lm-studio")
model = "lmstudio-community/qwen2.5-7b-instruct"
def get_delivery_date(order_id: str) -> datetime:
# Generate a random delivery date between today and 14 days from now
# in a real-world scenario, this function would query a database or API
today = datetime.now()
random_days = random.randint(1, 14)
delivery_date = today + timedelta(days=random_days)
print(
f"\nget_delivery_date function returns delivery date:\n\n{delivery_date}",
flush=True,
)
return delivery_date
tools = [
{
"type": "function",
"function": {
"name": "get_delivery_date",
"description": "Get the delivery date for a customer's order. Call this whenever you need to know the delivery date, for example when a customer asks 'Where is my package'",
"parameters": {
"type": "object",
"properties": {
"order_id": {
"type": "string",
"description": "The customer's order ID.",
},
},
"required": ["order_id"],
"additionalProperties": False,
},
},
}
]
messages = [
{
"role": "system",
"content": "You are a helpful customer support assistant. Use the supplied tools to assist the user.",
},
{
"role": "user",
"content": "Give me the delivery date and time for order number 1017",
},
]
# LM Studio
response = client.chat.completions.create(
model=model,
messages=messages,
tools=tools,
)
print("\nModel response requesting tool call:\n", flush=True)
print(response, flush=True)
# Extract the arguments for get_delivery_date
# Note this code assumes we have already determined that the model generated a function call.
tool_call = response.choices[0].message.tool_calls[0]
arguments = json.loads(tool_call.function.arguments)
order_id = arguments.get("order_id")
# Call the get_delivery_date function with the extracted order_id
delivery_date = get_delivery_date(order_id)
assistant_tool_call_request_message = {
"role": "assistant",
"tool_calls": [
{
"id": response.choices[0].message.tool_calls[0].id,
"type": response.choices[0].message.tool_calls[0].type,
"function": response.choices[0].message.tool_calls[0].function,
}
],
}
# Create a message containing the result of the function call
function_call_result_message = {
"role": "tool",
"content": json.dumps(
{
"order_id": order_id,
"delivery_date": delivery_date.strftime("%Y-%m-%d %H:%M:%S"),
}
),
"tool_call_id": response.choices[0].message.tool_calls[0].id,
}
# Prepare the chat completion call payload
completion_messages_payload = [
messages[0],
messages[1],
assistant_tool_call_request_message,
function_call_result_message,
]
# Call the OpenAI API's chat completions endpoint to send the tool call result back to the model
# LM Studio
response = client.chat.completions.create(
model=model,
messages=completion_messages_payload,
)
print("\nFinal model response with knowledge of the tool call result:\n", flush=True)
print(response.choices[0].message.content, flush=True)
```
agent-chat-example.py
(click to expand)
```python
import json
from urllib.parse import urlparse
import webbrowser
from datetime import datetime
import os
from openai import OpenAI
# Point to the local server
client = OpenAI(base_url="http://localhost:1234/v1", api_key="lm-studio")
model = "lmstudio-community/qwen2.5-7b-instruct"
def is_valid_url(url: str) -> bool:
try:
result = urlparse(url)
return bool(result.netloc) # Returns True if there's a valid network location
except Exception:
return False
def open_safe_url(url: str) -> dict:
# List of allowed domains (expand as needed)
SAFE_DOMAINS = {
"lmstudio.ai",
"huggingface.co",
"github.com",
"google.com",
"wikipedia.org",
"weather.com",
"stackoverflow.com",
"python.org",
"docs.python.org",
}
try:
# Add http:// if no scheme is present
if not url.startswith(('http://', 'https://')):
url = 'http://' + url
# Validate URL format
if not is_valid_url(url):
return {"status": "error", "message": f"Invalid URL format: {url}"}
# Parse the URL and check domain
parsed_url = urlparse(url)
domain = parsed_url.netloc.lower()
base_domain = ".".join(domain.split(".")[-2:])
if base_domain in SAFE_DOMAINS:
webbrowser.open(url)
return {"status": "success", "message": f"Opened {url} in browser"}
else:
return {
"status": "error",
"message": f"Domain {domain} not in allowed list",
}
}
except Exception as e:
return {"status": "error", "message": str(e)}
def get_current_time() -> dict:
"""Get the current system time with timezone information"""
try:
current_time = datetime.now()
timezone = datetime.now().astimezone().tzinfo
formatted_time = current_time.strftime("%Y-%m-%d %H:%M:%S %Z")
return {
"status": "success",
"time": formatted_time,
"timezone": str(timezone),
"timestamp": current_time.timestamp(),
}
except Exception as e:
return {"status": "error", "message": str(e)}
def analyze_directory(path: str = ".") -> dict:
"""Count and categorize files in a directory"""
try:
stats = {
"total_files": 0,
"total_dirs": 0,
"file_types": {},
"total_size_bytes": 0,
}
for entry in os.scandir(path):
if entry.is_file():
stats["total_files"] += 1
ext = os.path.splitext(entry.name)[1].lower() or "no_extension"
stats["file_types"][ext] = stats["file_types"].get(ext, 0) + 1
stats["total_size_bytes"] += entry.stat().st_size
elif entry.is_dir():
stats["total_dirs"] += 1
# Add size of directory contents
for root, _, files in os.walk(entry.path):
for file in files:
try:
stats["total_size_bytes"] += os.path.getsize(os.path.join(root, file))
except (OSError, FileNotFoundError):
continue
return {"status": "success", "stats": stats, "path": os.path.abspath(path)}
except Exception as e:
return {"status": "error", "message": str(e)}
tools = [
{
"type": "function",
"function": {
"name": "open_safe_url",
"description": "Open a URL in the browser if it's deemed safe",
"parameters": {
"type": "object",
"properties": {
"url": {
"type": "string",
"description": "The URL to open",
},
},
"required": ["url"],
},
},
},
{
"type": "function",
"function": {
"name": "get_current_time",
"description": "Get the current system time with timezone information",
"parameters": {
"type": "object",
"properties": {},
"required": [],
},
},
},
{
"type": "function",
"function": {
"name": "analyze_directory",
"description": "Analyze the contents of a directory, counting files and folders",
"parameters": {
"type": "object",
"properties": {
"path": {
"type": "string",
"description": "The directory path to analyze. Defaults to current directory if not specified.",
},
},
"required": [],
},
},
},
]
def process_tool_calls(response, messages):
"""Process multiple tool calls and return the final response and updated messages"""
# Get all tool calls from the response
tool_calls = response.choices[0].message.tool_calls
# Create the assistant message with tool calls
assistant_tool_call_message = {
"role": "assistant",
"tool_calls": [
{
"id": tool_call.id,
"type": tool_call.type,
"function": tool_call.function,
}
for tool_call in tool_calls
],
}
# Add the assistant's tool call message to the history
messages.append(assistant_tool_call_message)
# Process each tool call and collect results
tool_results = []
for tool_call in tool_calls:
# For functions with no arguments, use empty dict
arguments = (
json.loads(tool_call.function.arguments)
if tool_call.function.arguments.strip()
else {}
)
# Determine which function to call based on the tool call name
if tool_call.function.name == "open_safe_url":
result = open_safe_url(arguments["url"])
elif tool_call.function.name == "get_current_time":
result = get_current_time()
elif tool_call.function.name == "analyze_directory":
path = arguments.get("path", ".")
result = analyze_directory(path)
else:
# llm tried to call a function that doesn't exist, skip
continue
# Add the result message
tool_result_message = {
"role": "tool",
"content": json.dumps(result),
"tool_call_id": tool_call.id,
}
tool_results.append(tool_result_message)
messages.append(tool_result_message)
# Get the final response
final_response = client.chat.completions.create(
model=model,
messages=messages,
)
return final_response
def chat():
messages = [
{
"role": "system",
"content": "You are a helpful assistant that can open safe web links, tell the current time, and analyze directory contents. Use these capabilities whenever they might be helpful.",
}
]
print(
"Assistant: Hello! I can help you open safe web links, tell you the current time, and analyze directory contents. What would you like me to do?"
)
print("(Type 'quit' to exit)")
while True:
# Get user input
user_input = input("\nYou: ").strip()
# Check for quit command
if user_input.lower() == "quit":
print("Assistant: Goodbye!")
break
# Add user message to conversation
messages.append({"role": "user", "content": user_input})
try:
# Get initial response
response = client.chat.completions.create(
model=model,
messages=messages,
tools=tools,
)
# Check if the response includes tool calls
if response.choices[0].message.tool_calls:
# Process all tool calls and get final response
final_response = process_tool_calls(response, messages)
print("\nAssistant:", final_response.choices[0].message.content)
# Add assistant's final response to messages
messages.append(
{
"role": "assistant",
"content": final_response.choices[0].message.content,
}
)
else:
# If no tool call, just print the response
print("\nAssistant:", response.choices[0].message.content)
# Add assistant's response to messages
messages.append(
{
"role": "assistant",
"content": response.choices[0].message.content,
}
)
except Exception as e:
print(f"\nAn error occurred: {str(e)}")
exit(1)
if __name__ == "__main__":
chat()
```
tool-streaming-chatbot.py
(click to expand)
```python
from openai import OpenAI
import time
client = OpenAI(base_url="http://localhost:1234/v1", api_key="lm-studio")
MODEL = "lmstudio-community/qwen2.5-7b-instruct"
TIME_TOOL = {
"type": "function",
"function": {
"name": "get_current_time",
"description": "Get the current time, only if asked",
"parameters": {"type": "object", "properties": {}},
},
}
def get_current_time():
return {"time": time.strftime("%H:%M:%S")}
def process_stream(stream, add_assistant_label=True):
"""Handle streaming responses from the API"""
collected_text = ""
tool_calls = []
first_chunk = True
for chunk in stream:
delta = chunk.choices[0].delta
# Handle regular text output
if delta.content:
if first_chunk:
print()
if add_assistant_label:
print("Assistant:", end=" ", flush=True)
first_chunk = False
print(delta.content, end="", flush=True)
collected_text += delta.content
# Handle tool calls
elif delta.tool_calls:
for tc in delta.tool_calls:
if len(tool_calls) <= tc.index:
tool_calls.append({
"id": "", "type": "function",
"function": {"name": "", "arguments": ""}
})
tool_calls[tc.index] = {
"id": (tool_calls[tc.index]["id"] + (tc.id or "")),
"type": "function",
"function": {
"name": (tool_calls[tc.index]["function"]["name"] + (tc.function.name or "")),
"arguments": (tool_calls[tc.index]["function"]["arguments"] + (tc.function.arguments or ""))
}
}
return collected_text, tool_calls
def chat_loop():
messages = []
print("Assistant: Hi! I am an AI agent empowered with the ability to tell the current time (Type 'quit' to exit)")
while True:
user_input = input("\nYou: ").strip()
if user_input.lower() == "quit":
break
messages.append({"role": "user", "content": user_input})
# Get initial response
response_text, tool_calls = process_stream(
client.chat.completions.create(
model=MODEL,
messages=messages,
tools=[TIME_TOOL],
stream=True,
temperature=0.2
)
)
if not tool_calls:
print()
text_in_first_response = len(response_text) > 0
if text_in_first_response:
messages.append({"role": "assistant", "content": response_text})
# Handle tool calls if any
if tool_calls:
tool_name = tool_calls[0]["function"]["name"]
print()
if not text_in_first_response:
print("Assistant:", end=" ", flush=True)
print(f"**Calling Tool: {tool_name}**")
messages.append({"role": "assistant", "tool_calls": tool_calls})
# Execute tool calls
for tool_call in tool_calls:
if tool_call["function"]["name"] == "get_current_time":
result = get_current_time()
messages.append({
"role": "tool",
"content": str(result),
"tool_call_id": tool_call["id"]
})
# Get final response after tool execution
final_response, _ = process_stream(
client.chat.completions.create(
model=MODEL,
messages=messages,
stream=True
),
add_assistant_label=False
)
if final_response:
print()
messages.append({"role": "assistant", "content": final_response})
if __name__ == "__main__":
chat_loop()
```
| Endpoint | Method | Docs |
|---|---|---|
/v1/messages
|
|
Messages |
| Endpoint | Method | Docs |
|---|---|---|
/v1/systemone
|
|
System One |
Call `.cancel()` on the prediction
Every prediction method returns an `OngoingPrediction` instance. Calling `.cancel()` stops generation and causes the final `stopReason` to be `"userStopped"`. In the example below we schedule the cancel call on a timer: ```typescript import { LMStudioClient } from "@lmstudio/sdk"; const client = new LMStudioClient(); const model = await client.llm.model("qwen2.5-7b-instruct"); const prediction = model.respond("What is the meaning of life?", { maxTokens: 50, }); setTimeout(() => prediction.cancel(), 1000); // cancel after 1 second const result = await prediction.result(); console.info(result.stats.stopReason); // "userStopped" ```Use an `AbortController`
If your application already uses an `AbortController` to propagate cancellation, you can pass its `signal` to the prediction method. Aborting the controller stops the prediction with the same `stopReason`: ```typescript import { LMStudioClient } from "@lmstudio/sdk"; const client = new LMStudioClient(); const model = await client.llm.model("qwen2.5-7b-instruct"); const controller = new AbortController(); const prediction = model.respond("What is the meaning of life?", { maxTokens: 50, signal: controller.signal, }); setTimeout(() => controller.abort(), 1000); // cancel after 1 second const result = await prediction.result(); console.info(result.stats.stopReason); // "userStopped" ```Instantiate a Model
First, you need to load a model to generate completions from. This can be done using the `model` method on the `llm` handle. ```typescript title="index.ts" import { LMStudioClient } from "@lmstudio/sdk"; const client = new LMStudioClient(); const model = await client.llm.model("qwen2.5-7b-instruct"); ```Generate a Completion
Once you have a loaded model, you can generate completions by passing a string to the `complete` method on the `llm` handle.Print Prediction Stats
You can also print prediction metadata, such as the model used for generation, number of generated tokens, time to first token, and stop reason. ```typescript title="index.ts" console.info("Model used:", completion.modelInfo.displayName); console.info("Predicted tokens:", completion.stats.predictedTokensCount); console.info("Time to first token (seconds):", completion.stats.timeToFirstTokenSec); console.info("Stop reason:", completion.stats.stopReason); ```Instantiate the Model
Connect to LM Studio and obtain a handle to the VLM (Vision-Language Model) you want to use. ```typescript import { LMStudioClient } from "@lmstudio/sdk"; const client = new LMStudioClient(); const model = await client.llm.model("qwen2-vl-2b-instruct"); ```Prepare the Image
Use the `client.files.prepareImage()` method to get a handle to the image that can be subsequently passed to the model. ```typescript const imagePath = "/path/to/image.jpg"; // Replace with the path to your image const image = await client.files.prepareImage(imagePath); ``` If you only have the image in the form of a base64 string, you can use the `client.files.prepareImageBase64()` method instead. ```typescript const imageBase64 = "Your base64 string here"; const image = await client.files.prepareImageBase64(imageBase64); ``` The LM Studio server supports JPEG, PNG, and WebP image formats.Pass the Image to the Model in `.respond()`
Generate a prediction by passing the image to the model in the `.respond()` method. ```typescript const prediction = model.respond([ { role: "user", content: "Describe this image please", images: [image] }, ]); ```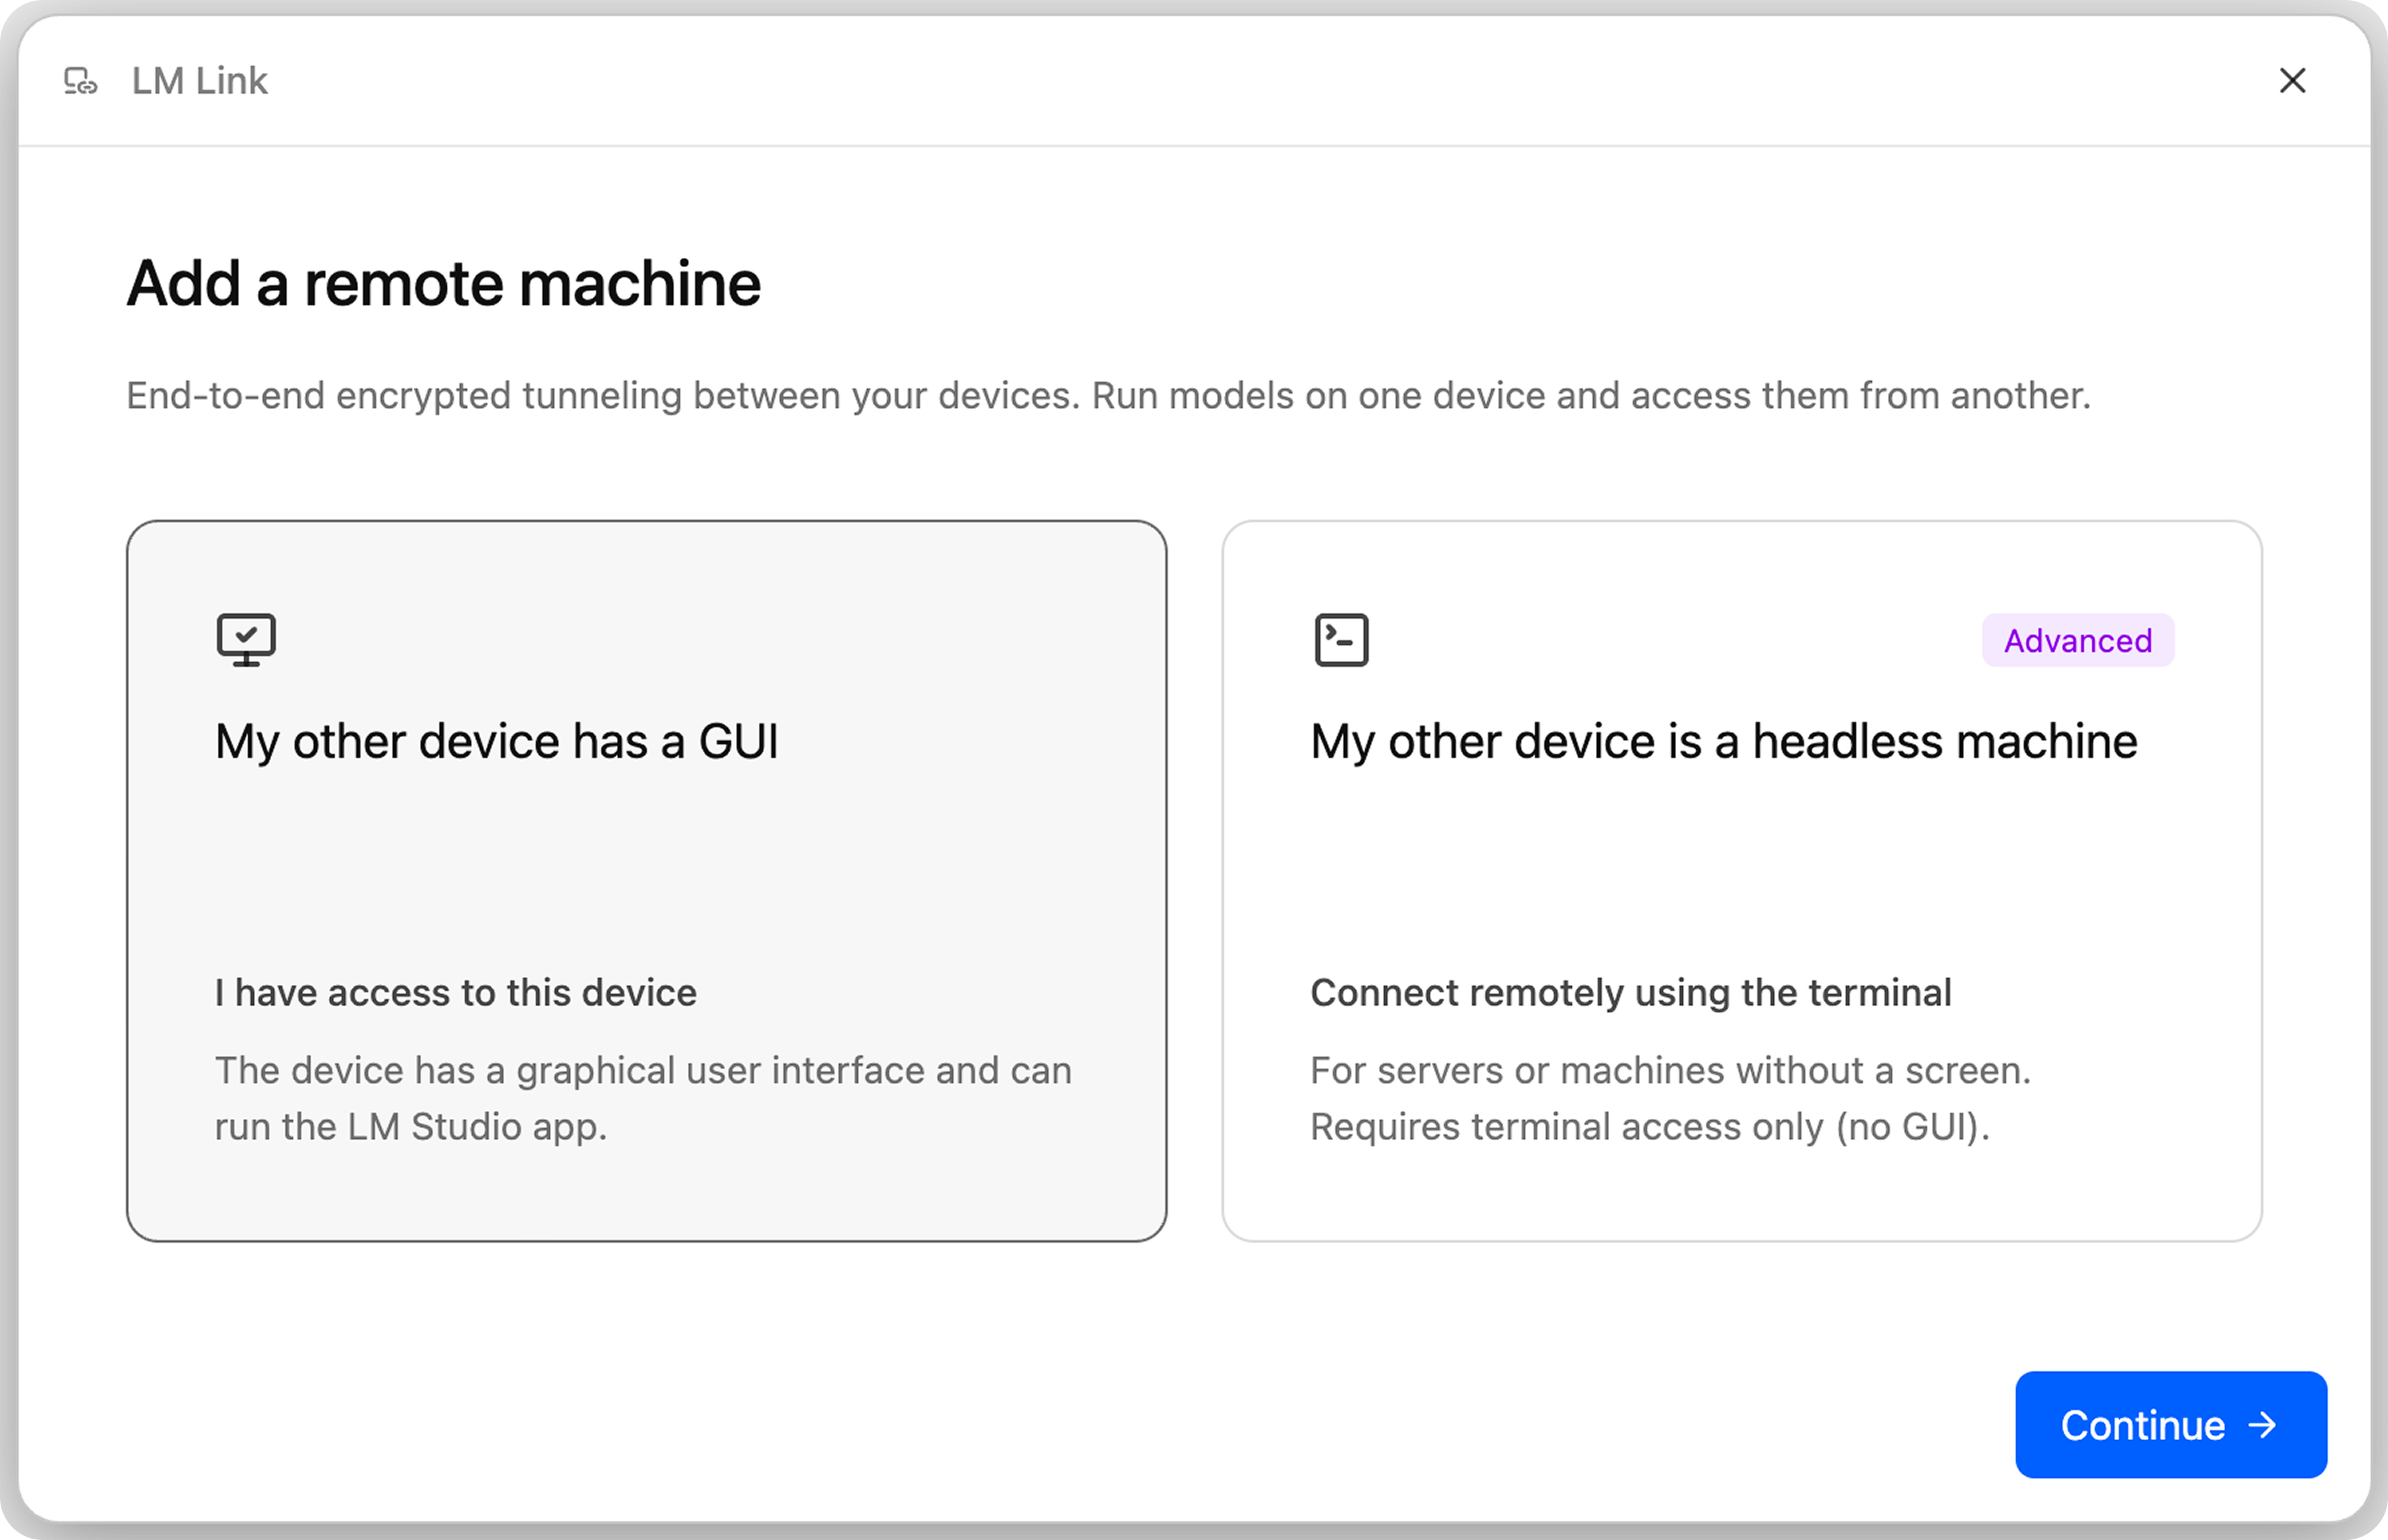 Machines with GUI [#machines-with-gui]
To begin using LM Link, add an additional device to the link:
1. Download and install LM Studio on the device, at [https://lmstudio.ai/download](https://lmstudio.ai/download)
2. Click on LM Link in the sidebar and follow the steps to enable LM Link.
Once LM Link is enabled, your devices will connect to each other automatically.
Machines without GUI [#machines-without-gui]
To add a headless machine, connect remotely by using llmster in the terminal:
1. Install `llmster` on the headless machine
```bash
curl -fsSL https://lmstudio.ai/install.sh | bash
```
2. Log in from the terminal
```bash
lms login
```
3. Follow the instructions in your terminal output to complete login.
4. Once logged in, run the following command:
```bash
lms link enable
```
Your devices will automatically discover each other over the link, and your headless machine will immediately appear on the LM Link page for your other device. Once connected, models from remote machines will appear locally for loading and inference.
Load models on remote machines [#load-models-on-remote-machines]
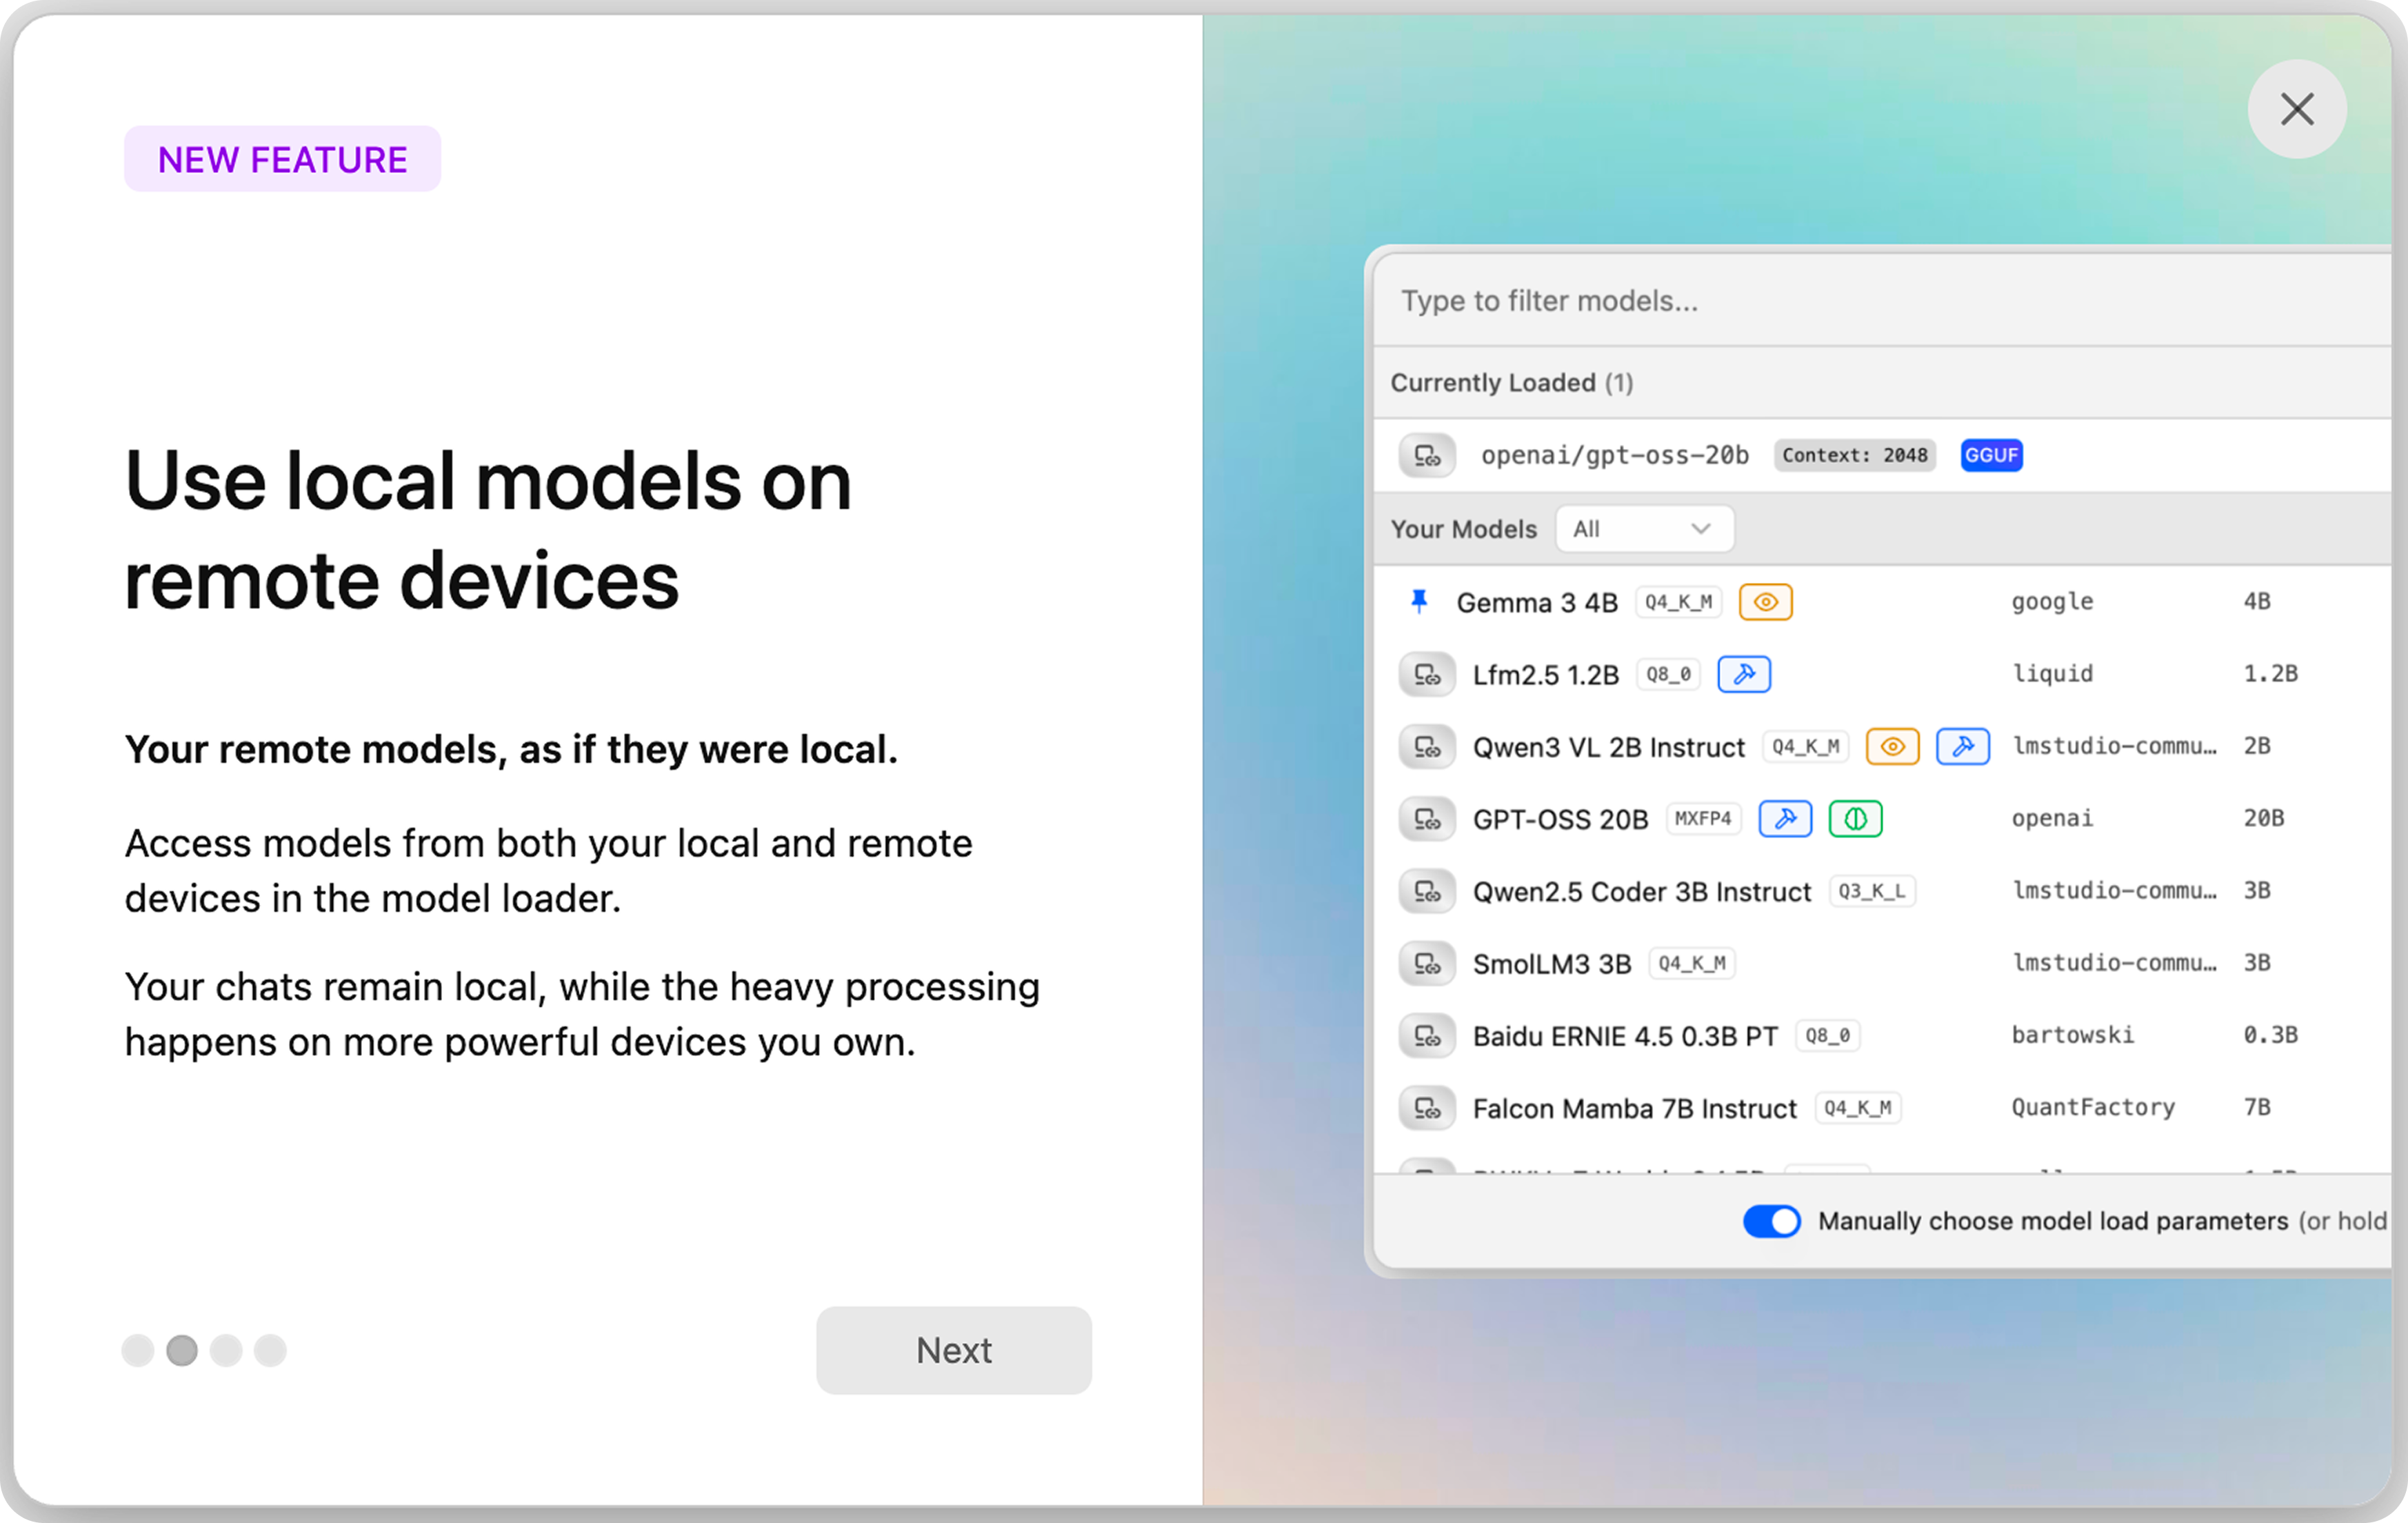 When using LM Link, the model loader shows both local models and remote models on linked devices.
You can filter the model loader to display only local or remote models, or to display all available models at once. Remote models can be loaded and configured with the same familiar controls, either in the GUI or by using lms in the terminal.
If you have the same model on multiple devices, they will show up as separate entries, with the associated device name identified. If you are loading models via API/SDK, you can [set a preferred device](/docs/lmlink/basics/preferred-device) to specify which device to load the model from when multiple options are available.
Using LM Studio’s parallel requests, you can also serve multiple clients simultaneously across your LM Link network.
Q&A [#qa]
Got questions about LM Link? We cover some of the most common questions below.
Q: Does LM Link open up my computer to the public internet? [#q-does-lm-link-open-up-my-computer-to-the-public-internet]
A: No! All your devices in the LM Link network communicate with each other using Tailscale’s internal end-to-end encrypted connections. None of your devices are ever exposed to the public Internet.
Q: Can I use remote models with LM Studio's local server? [#q-can-i-use-remote-models-with-lm-studios-local-server]
A: Yes. Any model in your LM Link network can be used as if they are local. This means that any tool that already connects to your local LM Studio will be able to use remote models as well, just by pointing to localhost:1234 as usual.
Q: Can I use remote models through the LM Studio API/SDKs? [#q-can-i-use-remote-models-through-the-lm-studio-apisdks]
A: Yes. Any model in your LM Link network can be used as if they are local. Just specify the model key as usual. If the model can be found on a remote device, it can be used through LM Link.
Q: Will LM Link interfere with my existing Tailscale VPN? [#q-will-lm-link-interfere-with-my-existing-tailscale-vpn]
A: No. LM Link is an entirely separate and self-contained utilization of Tailscale VPN primitives. LM Link will coexist with other Tailscale utilization on your machine or network, with no interference or interplay.
Q: Can the LM Studio Hub see my chats? [#q-can-the-lm-studio-hub-see-my-chats]
A: No. The LM Studio Hub is only used to facilitate discovery between LM Studio/llmster instances. All communication afterwards, including chats and model listing, happens within Tailscale’s end-to-end encrypted connection.
Q: How can I disable LM Link? [#q-how-can-i-disable-lm-link]
A: In the LM Studio app, go to Settings -> LM Link -> Enable LM Link - OFF. If you are using llmster (our headless daemon), run `lms link disable`.
Q: Why does a device show up as “disconnected”? [#q-why-does-a-device-show-up-as-disconnected]
A: LM Link uses end-to-end encrypted tunnels to connect to each other. If a device shows up as “disconnected”, it is possible that device has crashed but has not reported to the discovery server. Please make sure LM Studio/llmster is indeed running on that device. If the error persists, please report a bug at [bugs@lmstudio.ai](mailto:bugs@lmstudio.ai).
Q: If I have the same model on multiple devices, how do I choose which one to use? [#q-if-i-have-the-same-model-on-multiple-devices-how-do-i-choose-which-one-to-use]
A: If you are loading the model via LM Studio or `lms load`, the same model on different devices will show up as separate entries, with the device name identified. If you are loading models via API/SDK, you can set a preferred device from the in-app LM Link page, or use command `lms link set-preferred-device`. Once set, the model will always load on your preferred device.
Q: Can linked devices do anything besides LM Studio tasks on my computer? [#q-can-linked-devices-do-anything-besides-lm-studio-tasks-on-my-computer]
A: No. LM Link only lets LM Studio/llmster talk to each other for model and API access. It does not expose your operating system, files, or other services to linked devices.
Q: Can I use my existing Tailscale network? [#q-can-i-use-my-existing-tailscale-network]
A: Not at the moment. When you enable LM Link we create a dedicated network programmatically and take full control over the ACL. This will not work well with any existing Tailscale networks. If you wish, you can DIY several aspects of the LM Link feature set yourself.
Requesting Access [#requesting-access]
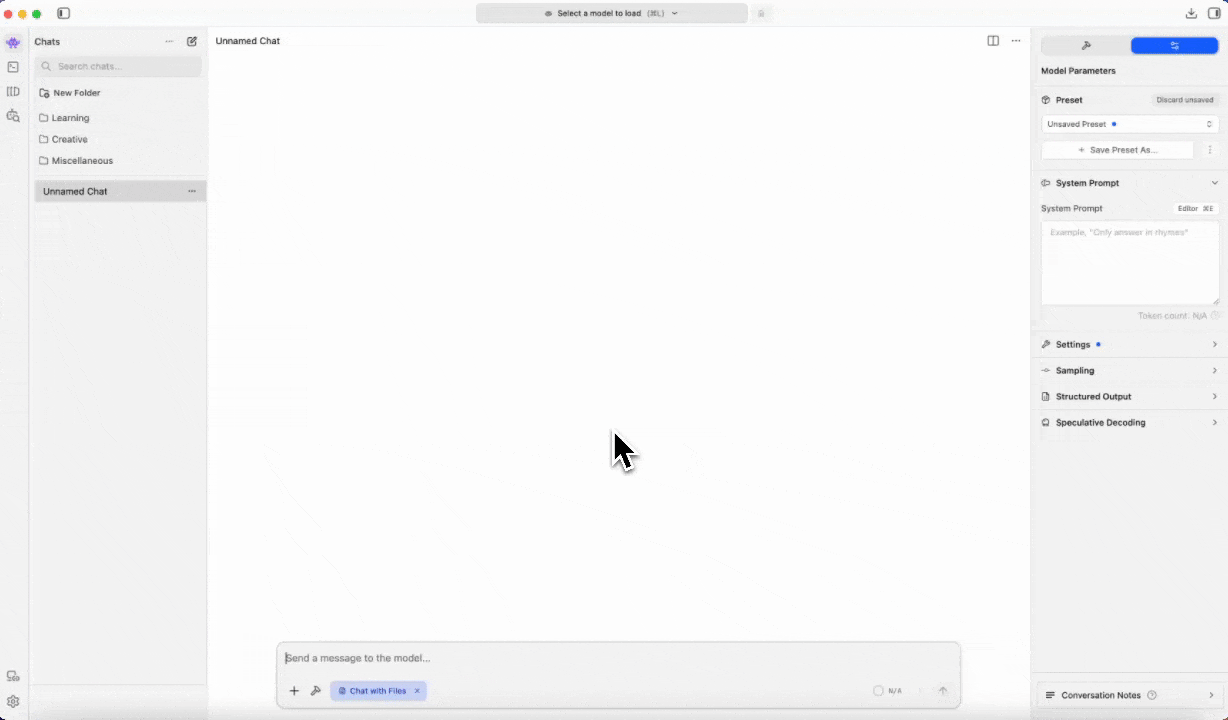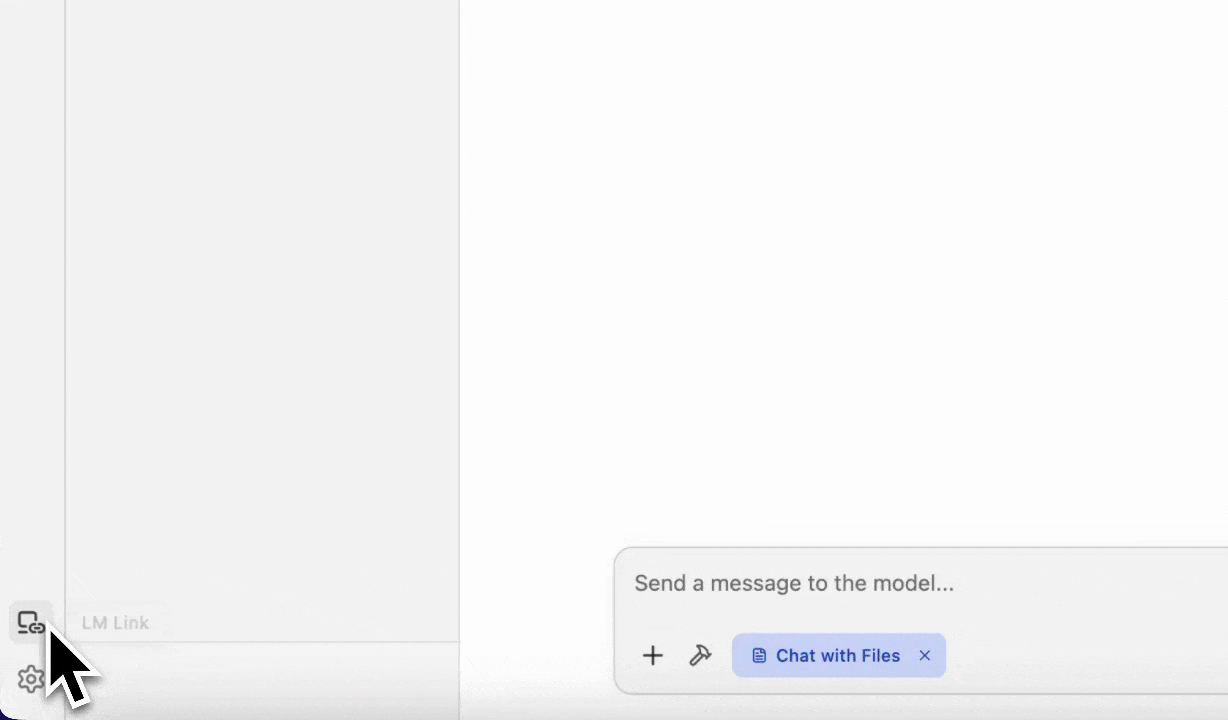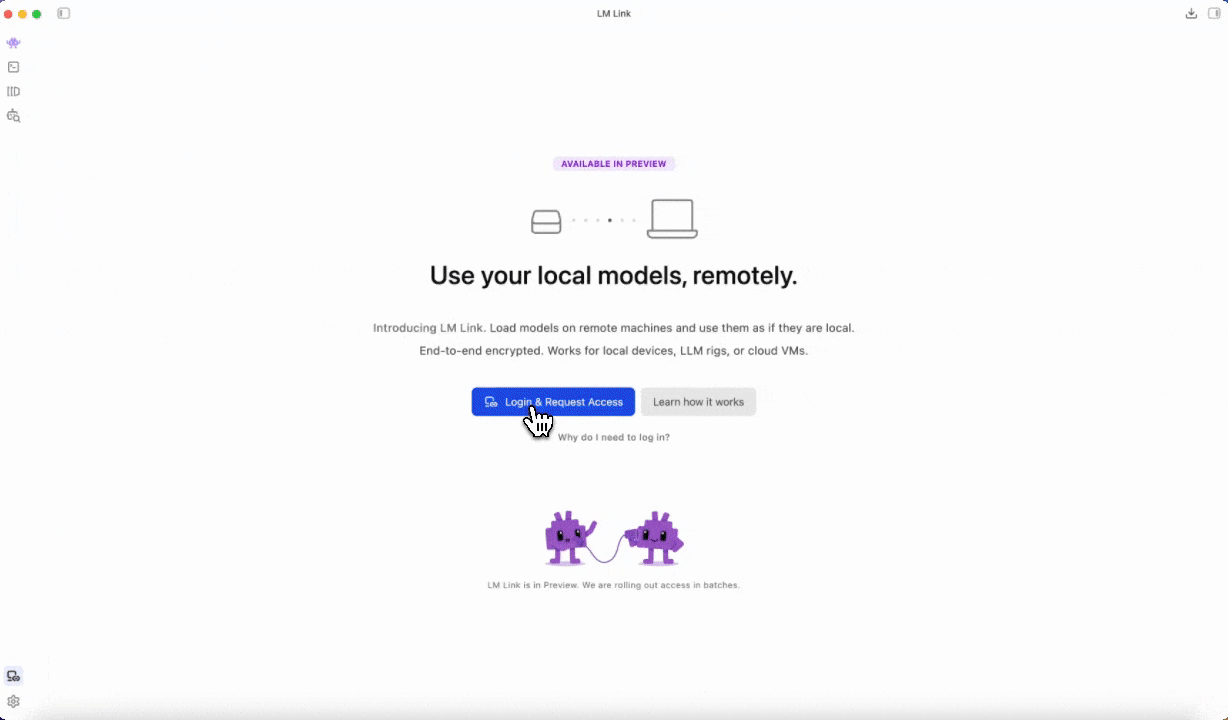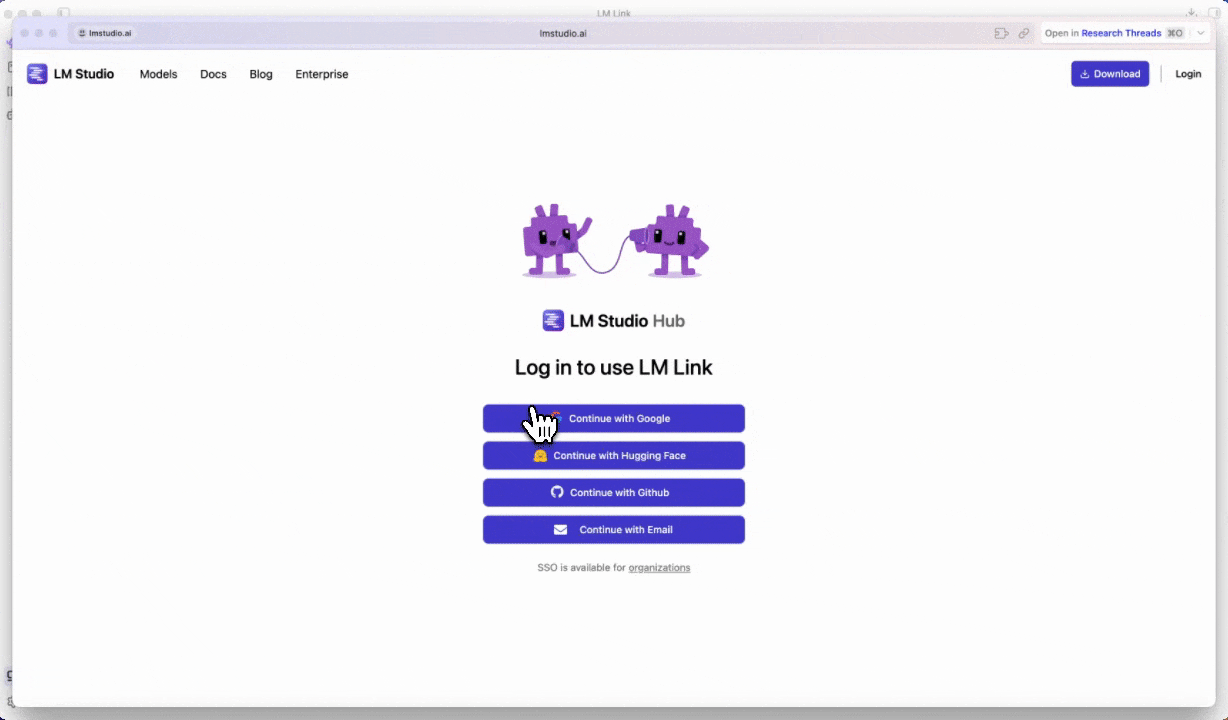 To get started, find the LM Link icon in the LM Studio app, just above the Settings gear icon. LM Link is a network between your devices, so log-in is required to associate devices to users in order to facilitate discovery.
A custom link is **automatically provisioned** for you the first time you access the feature.
Once your first device has joined the link, [add another device](/docs/lmlink/basics/add-device) to experience the power of LM Link!
Choosing a preferred device [#choosing-a-preferred-device]
When the same model is available on multiple devices in the link, LM Link uses the preferred device to load and use the model. This setting is per-machine: each device on the link independently controls which remote machine it prefers.
This is especially relevant when accessing remote models via the SDK or [REST API](/docs/developer/core/lmlink).
Machines with GUI [#machines-with-gui]
In the app, head to the LM Link page, select the device and toggle the "Set as preferred device" option.
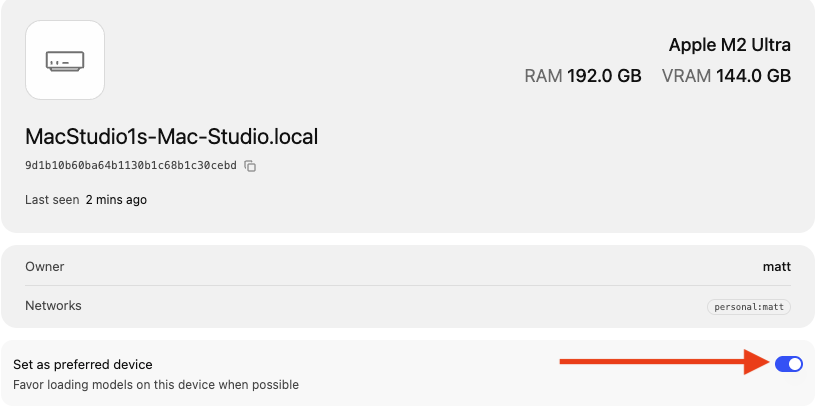 Machines without GUI [#machines-without-gui]
To set a preferred device from the terminal, use the following command:
```bash
lms link set-preferred-device
```
LM Studio now supports MCP with OAuth. Seamlessly connect integrations that require authentication without copying tokens or configuring headers. Simply add your integration, log in via browser, and its tools are instantly available to your models in LM Studio.
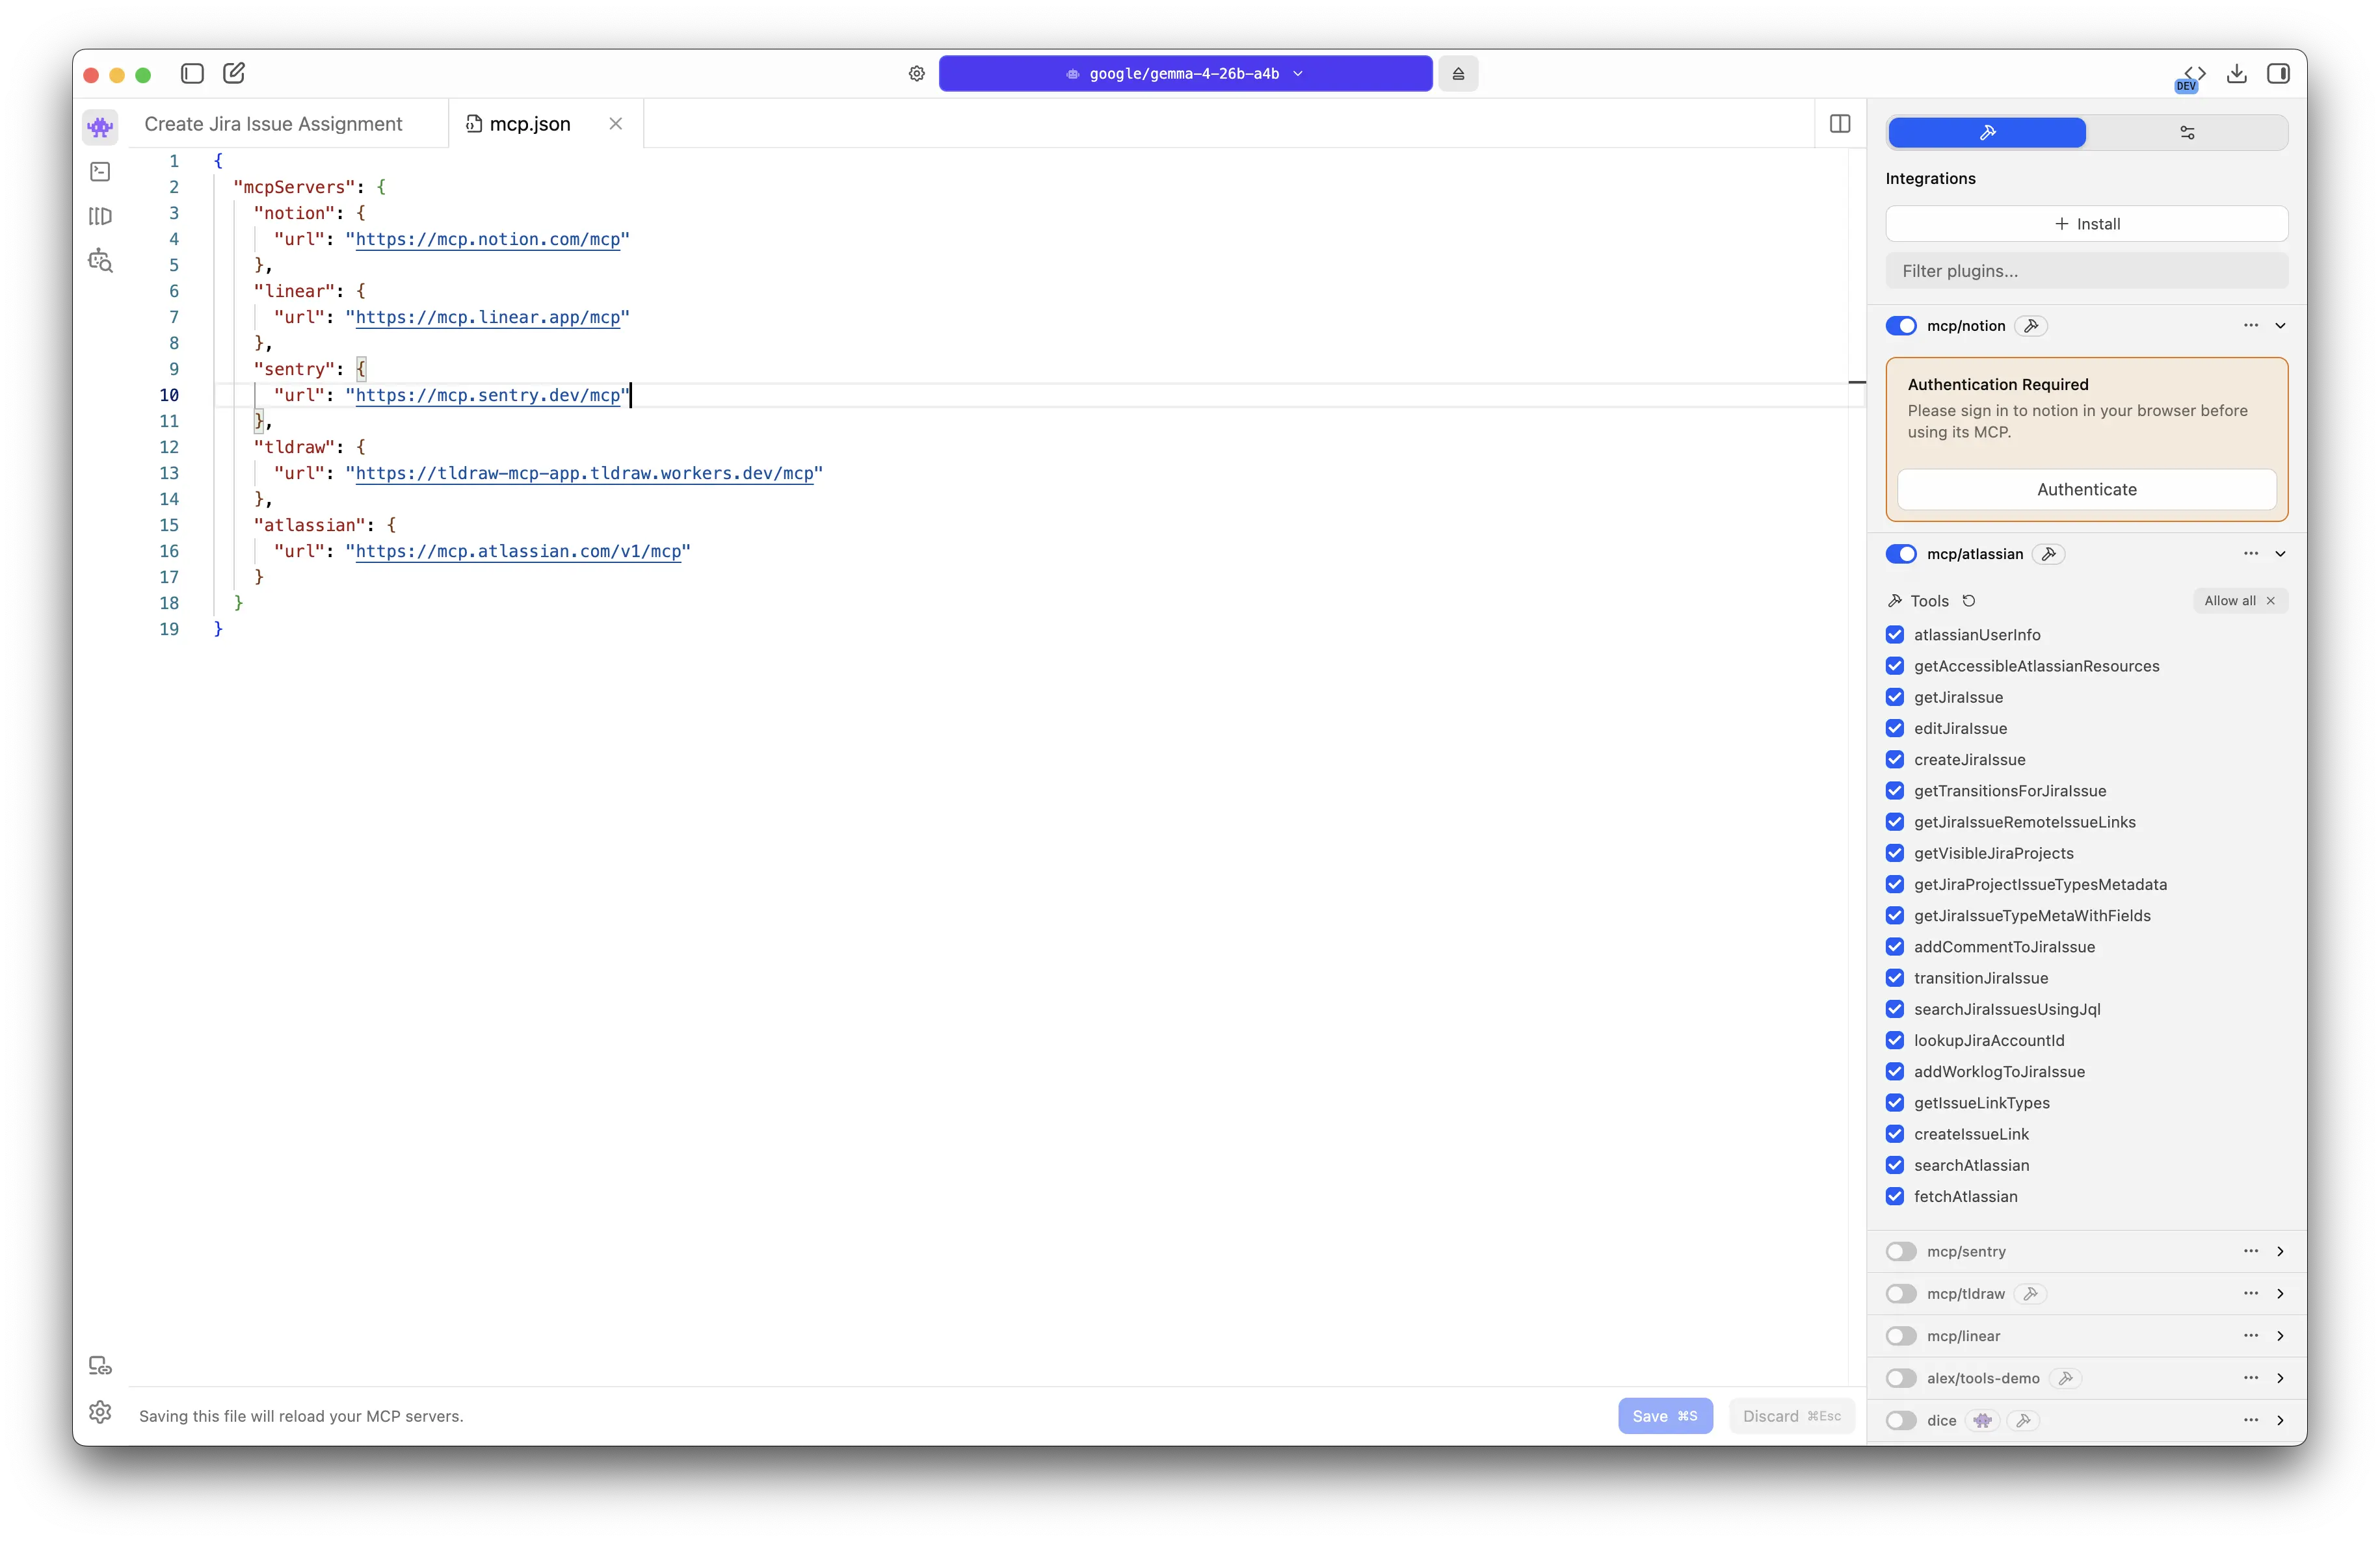 How it works [#how-it-works]
When you add an OAuth-backed MCP integration, LM Studio:
1. Opens a browser window to the service's authorization page
2. Stores the token securely after you approve access
3. Makes the server's tools available in chat
From that point on, your model can call tools from that service just like any other MCP server.
***
Connecting with your own OAuth credentials [#connecting-with-your-own-oauth-credentials]
Some services require you to bring your own OAuth app, either because they don't support dynamic client registration, or because they need a specific redirect URL whitelisted in their developer portal.
In these cases, add an `auth` object to the server entry in `mcp.json`. When configuring your OAuth app, use the following callback URL:
```
http://127.0.0.1:33389/mcp-oauth-callback
```
```json
{
"mcpServers": {
"oauth-server": {
"url": "https://api.example.com/mcp",
"auth": {
"CLIENT_ID": "TEST_CLIENT_ID",
"CLIENT_SECRET": "TEST_CLIENT_SECRET"
}
}
}
}
```
Linear [#linear]
Create issues, search projects, update statuses, and more in Linear, directly from LM Studio.
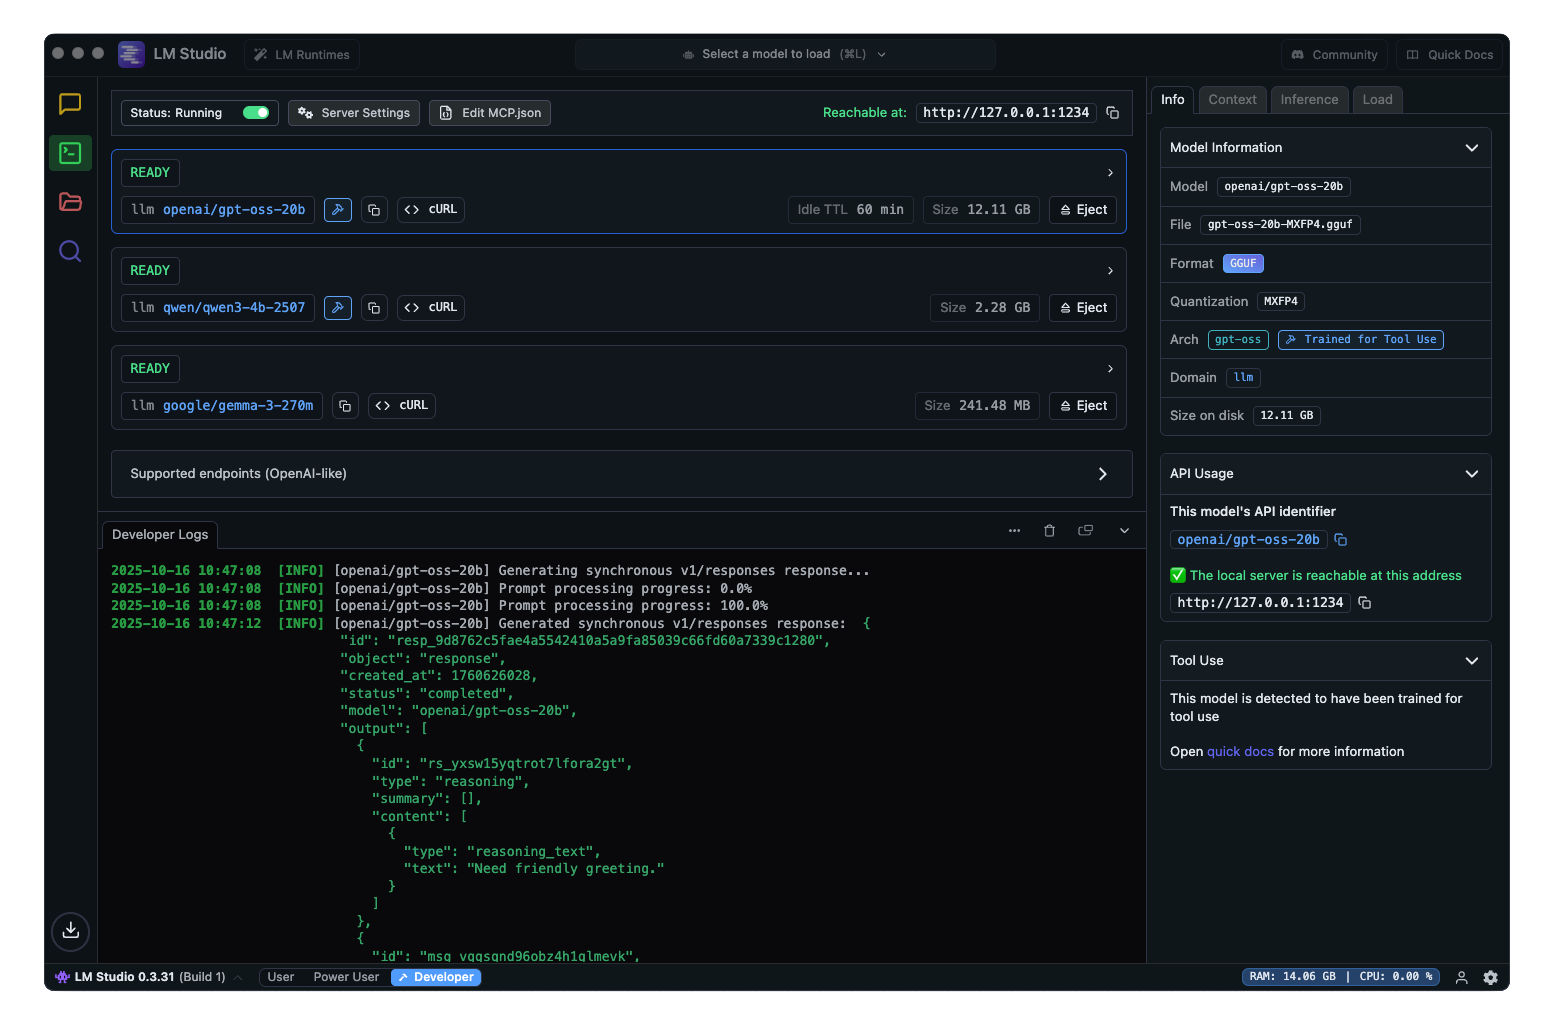 Running the server [#running-the-server]
To run the server, go to the Developer tab in LM Studio, and toggle the "Start server" switch to start the API server.
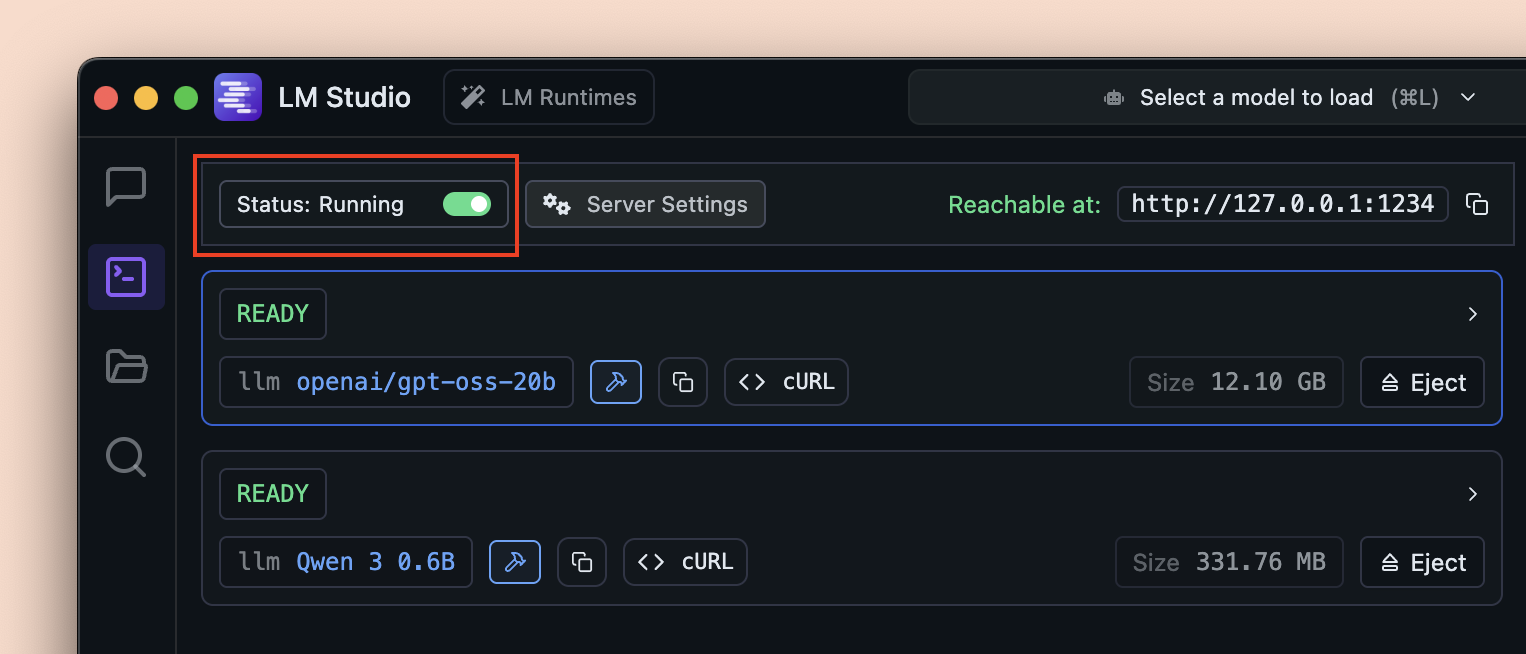 Alternatively, you can use `lms` ([LM Studio's CLI](/docs/cli)) to start the server from your terminal:
```bash
lms server start
```
API options [#api-options]
* [LM Studio REST API](/docs/developer/rest)
* [TypeScript SDK](/docs/typescript) - `lmstudio-js`
* [Python SDK](/docs/python) - `lmstudio-python`
* [OpenAI-compatible endpoints](/docs/developer/openai-compat)
* [Anthropic-compatible endpoints](/docs/developer/anthropic-compat)
* [Jev (TypeSafe AI)-compatible endpoints](/docs/developer/jev-compat)
Enabling the "Serve on Local Network" option allows the LM Studio API server running on your machine to be accessible by other devices connected to the same local network.
This is useful for scenarios where you want to:
* Use a local LLM on your other less powerful devices by connecting them to a more powerful machine running LM Studio.
* Let multiple people use a single LM Studio instance on the network.
* Use the API from IoT devices, edge computing units, or other services in your local setup.
Once enabled, the server binds to a non-localhost address instead of localhost. The API access URL updates accordingly, which you can use in your applications.
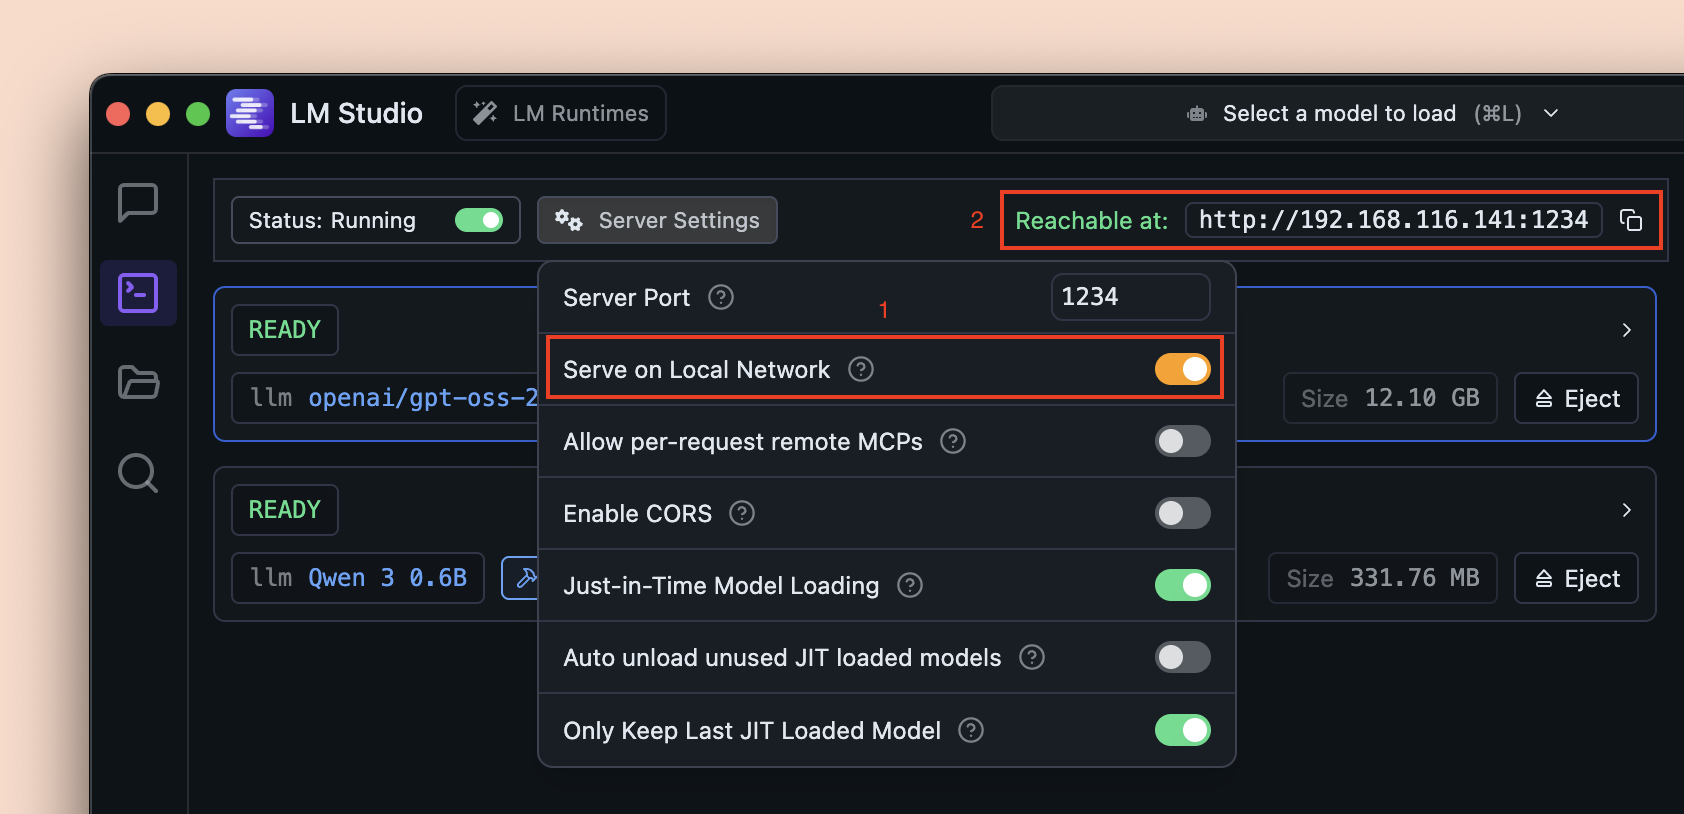 To make the server available on your local network via the CLI, run:
```
lms server start --bind 0.0.0.0
```
You can configure server settings, such as the port number, whether to allow other API clients to access the server and MCP features.
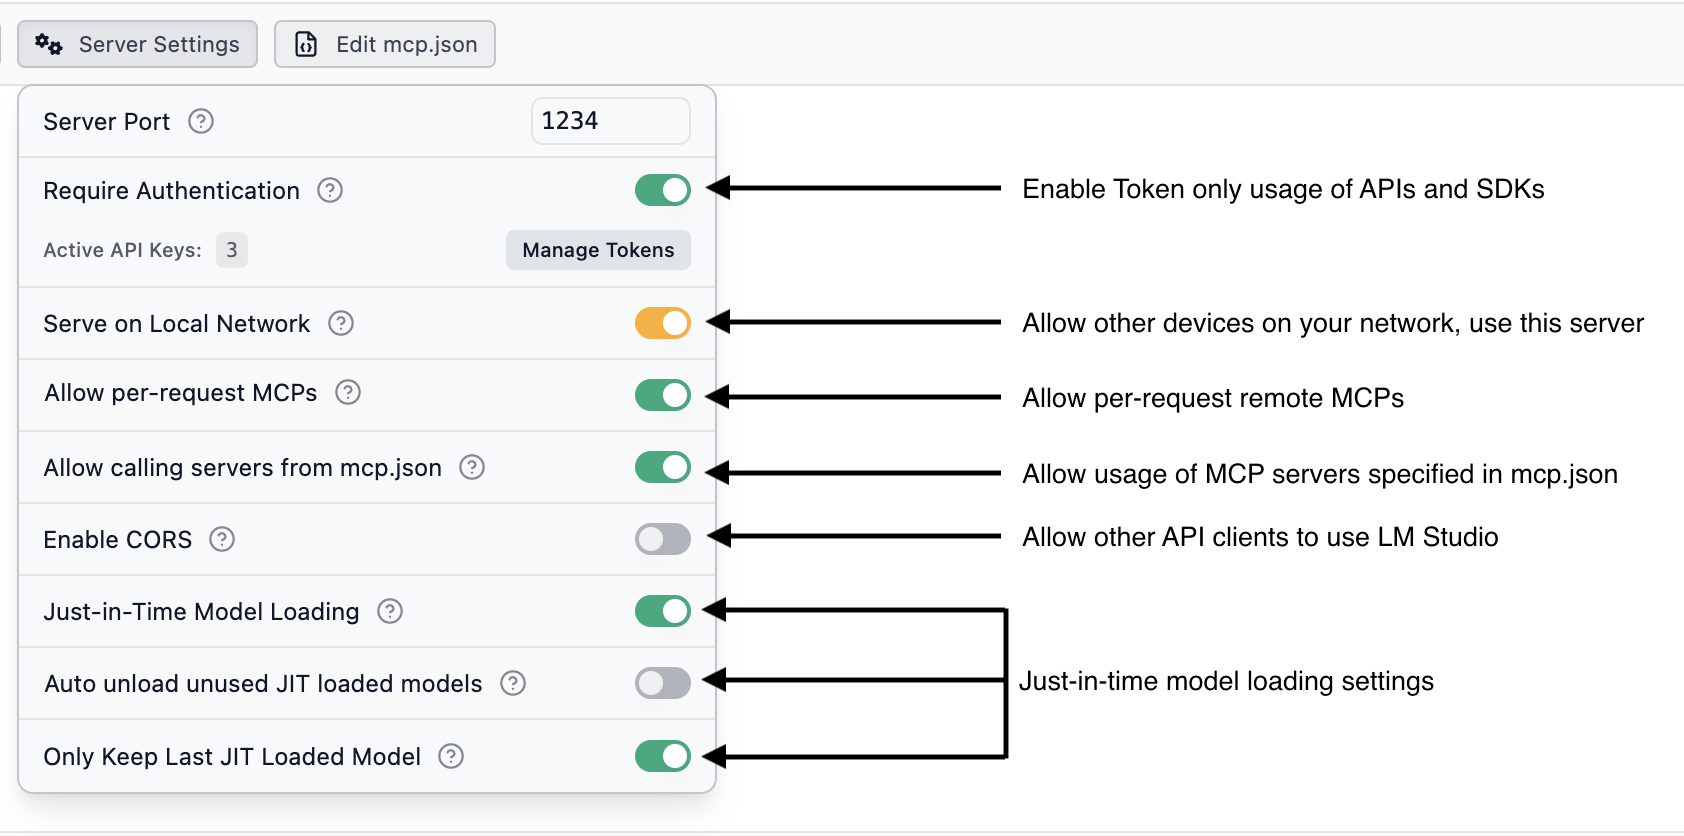 Settings information [#settings-information]